Apify Reddit Scraper Alternative: Posts and Comments per 1,000 Rows, Measured
Reddit Scraper Lite on Apify costs $4.04 for 1,000 comments. We measured $0.0073 for a flat list with no parent ids. For full trees, use Apify.
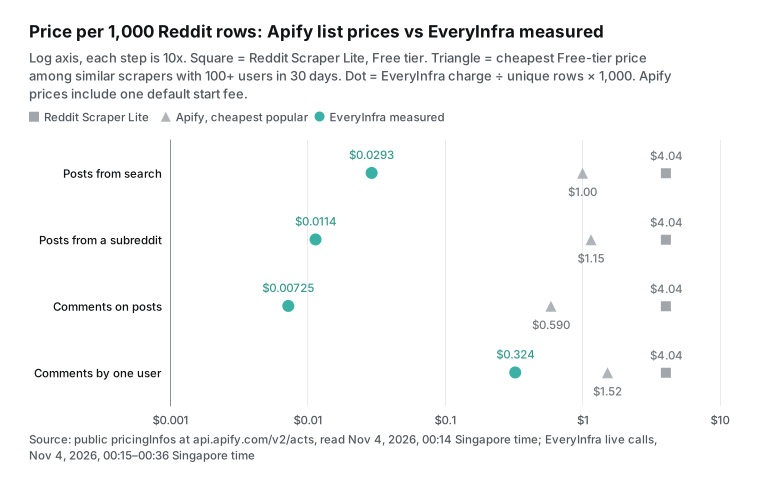
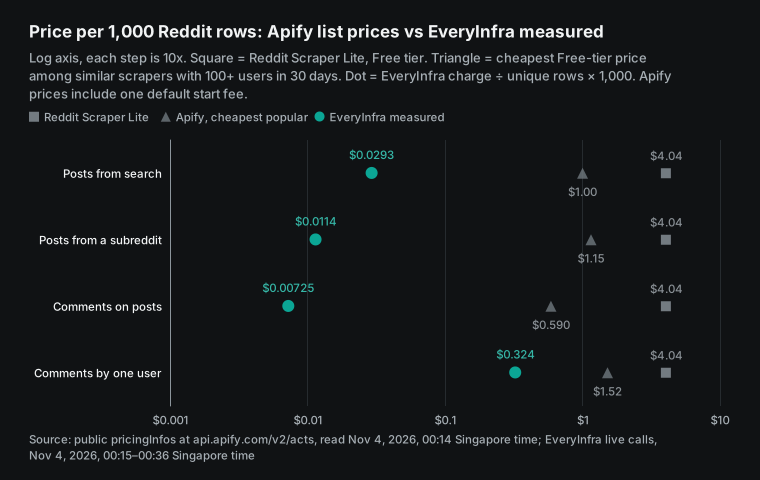
Reddit Scraper Lite is the Reddit scraper with the most users in the Apify Store. At its public Free-tier price, 1,000 Reddit comments cost $4.04: $0.004 per result plus a $0.04 start fee. The cheapest popular alternative in the Store, automation-lab, costs about $0.59 for the same job. On November 4, 2026, we called the EveryInfra reddit/comments endpoint for 13 posts.
Each call cost $0.000556. We got 997 unique comments for $0.007228 in total, or $0.00725 per 1,000. That is 557 times cheaper than Lite and 81 times cheaper than automation-lab. For posts, keyword search came to $0.0293 per 1,000 and subreddit listings to $0.0114 per 1,000.
There are also three jobs where Apify is the better tool, and this article says so in each test. First, we return at most 100 comments per post, so a thread with 771 comments gave us only 13% of them. Second, our comment rows include second- and third-level replies, but they carry no parent id, so you cannot rebuild the tree. Third, eight sort orders on one subreddit gave us only 286 unique posts, not 1,000.
Below we test four kinds of Reddit data one by one. We also cover the deprecated "Reddit Scraper" on Apify and the price spread of 746 Reddit scrapers in the Store. Last, we cover the timeline that closes Reddit's public Data API.
How to read the numbers in this article
In this article, "cost per 1,000" means the money actually charged, divided by the unique rows actually returned, times 1,000. It answers one question: what do 1,000 Reddit posts or comments cost you? EveryInfra charges per request, and one request returns one page. Search returns up to 25 rows, and subreddit listings and comments up to 100. User posts return up to 50 (see max_limit in the free catalog).
Almost every Reddit scraper in the Apify Store charges per result instead. It charges once for each row written to the dataset. You can only compare the two models after you convert both to the same unit.
On our side, the divisor is always the row count after de-duplication by id. We never divide by the limit that we asked for. So calls that return few rows, or many duplicates, can only make our price look higher. On the Apify side, we used public material only.
That means Store pages, the pricing page, the docs, and the public actor metadata endpoint that needs no account (Get Actor API docs). An actor is Apify's name for a cloud scraping program. We did not sign up for Apify and we did not run any actor. Every Apify number in this article is a public list price, not a measured bill.
Apify Reddit scraper vs EveryInfra: the summary table
This table is the result of the whole article. Each row lists two Apify prices. One is Reddit Scraper Lite, the Reddit scraper with the most users. The other is the cheapest Free-tier price among scrapers that do the same job and had at least 100 users in the last 30 days.
We read the prices from the pricingInfos field in Apify's public metadata at 00:15 Singapore time on November 4, 2026. Every Apify price assumes one run that returns 1,000 rows on the Free tier, plus the default start fee. Every EveryInfra number comes from our own live calls. The charge is billing.charged_usd from the response, the rows are results, and de-duplication is by id.
| Data | EveryInfra endpoint | Measured: calls / rows / unique / charged | EveryInfra per 1,000 (unique) | Reddit Scraper Lite (Free) | Ratio | Cheapest popular on Apify (Free) | Ratio |
|---|---|---|---|---|---|---|---|
| Posts from keyword search | reddit/search | 10 / 195 / 190 / $0.00556 | $0.0293 | $4.04 | 138x | clearpath Search $1.00 | 34x |
| Posts from one subreddit | reddit/subreddit_posts | 10 / 837 / 486 / $0.00556 | $0.0114 | $4.04 | 353x | automation-lab $1.15 | 101x |
| Comments on posts | reddit/comments | 13 / 997 / 997 / $0.007228 | $0.00725 | $4.04 | 557x | automation-lab $0.59 | 81x |
| Comments by one user | reddit/user_comments | 1 / 100 / 100 / $0.032403 | $0.324 | $4.04 | 12.5x | harshmaur User $1.52 | 4.7x |
Each ratio is the Apify price divided by ours. Keep four points in mind when you read the table. First, most of the gap comes from "one request, one page." A comments call returns up to 100 rows, so a full page spreads the fixed price thin. When each call returns only one or two rows, the result flips, and the break-even section below shows the math.
Second, the automation-lab comment price of $0.59 uses $0.000575 per comment, a $0.003 start fee, and 10 post rows at $0.00115 each. Its Store page says the Free-tier comment price goes up to $0.00075 on November 17. By the same math, that gives $0.76 (automation-lab Store page).
Third, we are cheaper on both post rows, but we cannot always reach 1,000 posts. Search covers only the last month, and subreddit listings have no pagination. The next sections show how many posts we actually got. Fourth, Apify prices change every month or two, and the "What changed recently" section lists the dates.
How we tested, and what counted as a pass
We wrote the pass and fail rules before the first call. Each of the four data types needed at least two live calls, spread over three or more different times. Cost per 1,000 always used unique rows as the divisor. To judge comment tree coverage, we compared our rows one by one against a third-party reading of at least two post pages.
We did not infer coverage from a field list. If Apify was cheaper, more complete or a better fit for any job, the text and the summary table had to say so. At least two calls had to return no data, and we had to record what each one cost. We made at most one live call to reddit/user_comments, and no live call to reddit/painpoint.
Every request went to POST https://api.everyinfra.com/api/v1/social. The first request left at 00:15 Singapore time on November 4, 2026. The comment round ran from 00:26 to 00:32 Singapore time, and the last call finished at 00:36 Singapore time. For each call we logged the send time, HTTP status, duration, row count and charged_usd. A script then recomputed every figure from the raw responses. All numbers in the text, tables and charts come from that script.
| Job | Endpoint and parameters | Live calls | Time (Singapore time, Nov 4) | What we checked |
|---|---|---|---|---|
| Keyword search | reddit/search, limit 25. Seven keywords, plus newest, top and popular sorts for "standing desk" | 10 | 00:15 to 00:19 | Rows per call, effect of the sort, date range |
| Subreddit posts | reddit/subreddit_posts. Eight sort and time combinations on r/Python, two on r/smallbusiness, limit 100 | 10 | 00:20 to 00:24 | New posts per extra sort, the ceiling for one community |
| Comments | reddit/comments. 13 posts with 16 to 771 comments, limit 100 | 13 | 00:26 to 00:32 | Rows per post, share of the post's count, nested replies |
| Users | reddit/user_posts seven times on three accounts. reddit/user_comments once | 8 | 00:24 to 00:35 | How far back it goes, what one expensive call returns |
| Post detail | reddit/post_detail on two posts | 2 | 00:33 | Does the count match the listing? |
| No data | No key, bad sort value, extra parameter, missing subreddit, missing post, missing user | 6 | 00:25 to 00:36 | Which cases cost money |
The article used 49 live calls, and the total charge was $0.056311. All calls shared one test key with a limit of 10 calls per minute. During the run we hit HTTP 429 (too many requests) several times. Our script waited 60 seconds and sent the call again. A 429 is not charged, and it is not counted in the totals above.
Test 1: the most common Apify Reddit scraper job, 1,000 posts from keyword search
reddit/search returns up to 25 rows per call. Its time range is fixed to the last month. The catalog note on the sort parameter says the range stays one month whatever sort you pick. We searched seven different keywords once each: standing desk, notion alternative, claude code, best vpn, airpods pro 3, home espresso machine and sourdough starter.
The calls returned 25, 17, 25, 25, 25, 24 and 25 rows, an average of 23.7. Every post was dated between October 3 and November 3, 2026, which matches the one-month range. The seven calls cost $0.003892, and none of the 166 rows was a duplicate. That is $0.0234 per 1,000.
The sort order changed the counts a lot. For the same keyword, standing desk, the default relevance sort returned 25 rows and popular returned 22. But top returned only 4 and newest returned only 3, all three from November 3. The catalog explains why. Search returns only posts that match the keyword, so the count can fall below the limit.
A call with zero rows is refunded as an empty result. A call with three rows is charged the normal $0.000556. With those three sort calls included, the 10 calls returned 195 rows, 190 of them unique, for $0.00556. That is $0.0293 per 1,000, and the summary table uses this more cautious figure.
To collect 1,000 posts at 23.7 per call, you need about 42 searches. That means 42 different keywords or keyword combinations, at a cost of about $0.0234. If you care about only one or two keywords, you will not reach 1,000. One keyword matches only so many posts in one month, and our search does not go back further.
Apify is different here. The time parameter in Lite accepts all, year, month and other values (Store page, "Advanced parameters"). The clearpath search scraper supports five sort orders and time filters. It costs $0.00099 per result plus $0.00001 per dataset write and a small start fee, so $1.00 per 1,000 (clearpath Search Store page).
So for 1,000 posts on a topic from past years, Apify is the better choice. For daily or weekly monitoring of a set of keywords over the last month, we cost $0.000556 for 20 or more posts per call. That is much cheaper.
| Keyword | Sort | Rows | Earliest post (UTC) | Charged |
|---|---|---|---|---|
| standing desk | default (relevance) | 25 | October 3 | $0.000556 |
| standing desk | popular | 22 | October 27 | $0.000556 |
| standing desk | top | 4 | October 6 | $0.000556 |
| standing desk | newest | 3 | November 3 | $0.000556 |
| notion alternative | default | 17 | October 3 | $0.000556 |
| The other 5 keywords | default | 24 to 25 | October 3 to 6 | $0.000556 each |
Test 2: 1,000 posts from one subreddit, where we got 286
reddit/subreddit_posts returns up to 100 rows per call and has no pagination parameter. To get more, you can only change the sort and the time window. sort accepts newest, popular, top, rising and relevance. date_range applies only with sort=top, as the catalog says. We ran eight combinations once each on r/Python. The chart shows how many new posts each extra combination added.
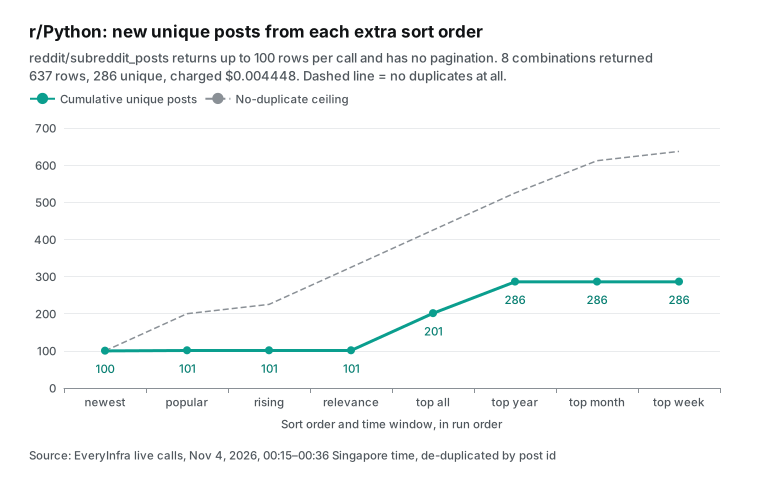
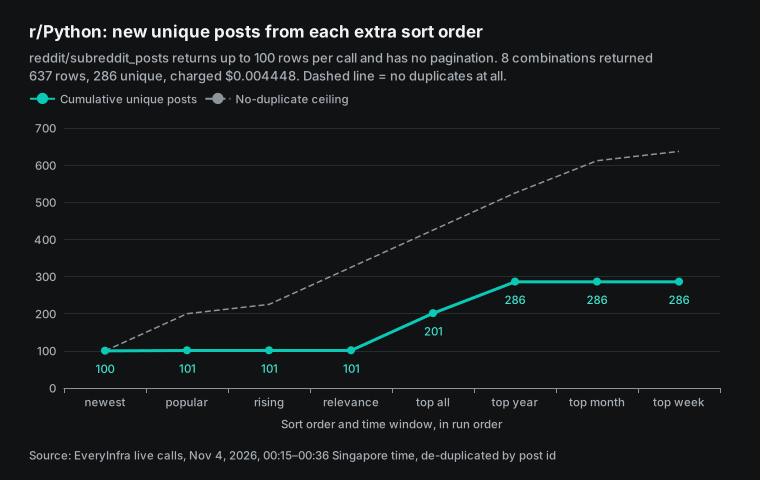
The result is clear. The 100 rows from newest, popular and relevance were almost the same set, 101 unique posts in total. Rising returned 25 rows, all already seen. Only two combinations brought new posts: top with all_time (100 posts, the oldest from 2017) and top with past_year (85 new). The 87 rows from past_month and the 25 from past_week were all duplicates. The eight calls cost $0.004448 for 286 unique posts, or $0.0156 per 1,000.
If you know in advance that only newest, top all time and top past year matter, three calls get the same 286 posts for $0.001668. That is $0.0058 per 1,000. On r/smallbusiness, two calls (newest and top past year) returned 100 rows each with no overlap, which is $0.0056 per 1,000. All 10 subreddit calls together returned 837 rows, 486 unique, for $0.00556. That is $0.0114 per 1,000, the figure in the summary table.
So we cannot deliver "1,000 posts from one subreddit," and Apify is the better fit for that job. Reddit's own listings go back only about 1,000 items. The Lite readme says the same and suggests combining sort orders, search and time filters to collect more (Store page, "Reddit's 1,000 items limit"). A scraper that can paginate gets close to 1,000 rows per sort order. We return only the first page of 100 for each sort.
For a daily look at new and popular posts in a community, two calls (newest plus top past day) cost $0.001112. For a one-time export of years of history from a community, use Apify, or apply to Reddit's own researcher program.
Test 3: what an Apify Reddit comment scraper must beat, 1,000 comments and the tree
Comments show the largest price gap in this test. They are also where Apify has the clearest feature lead. reddit/comments takes one post URL and returns up to 100 comments per call. We picked 13 posts with 16 to 771 comments each and called each one once.
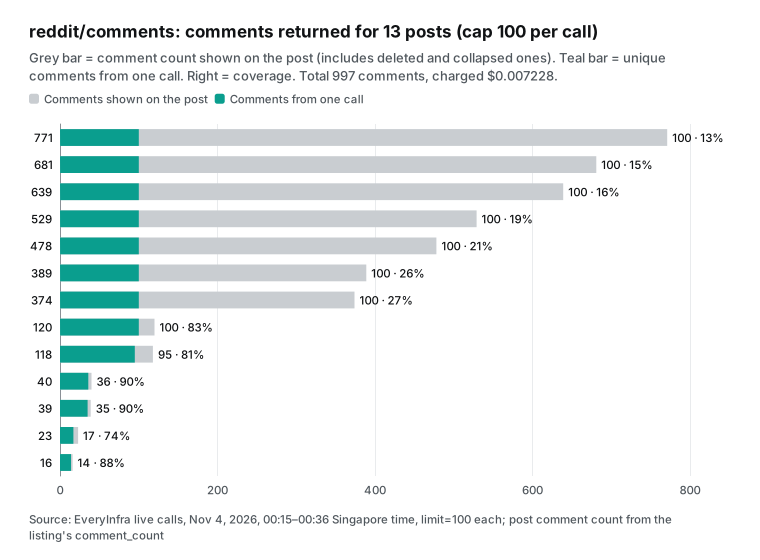
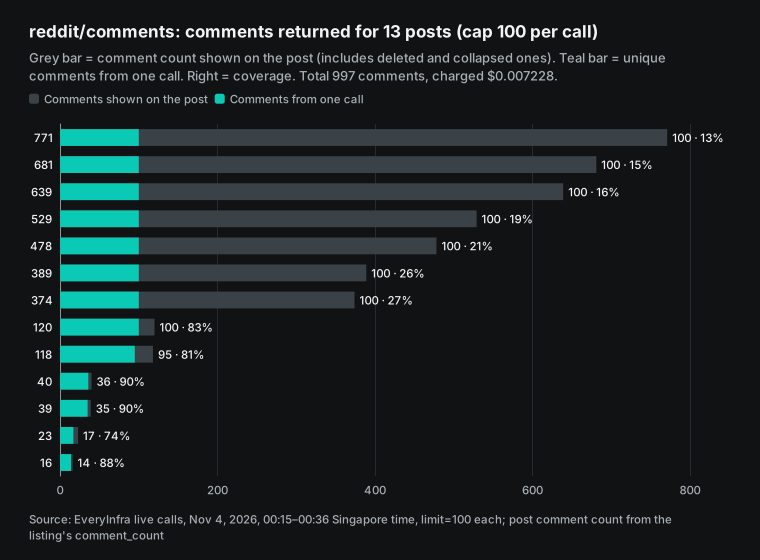
The 13 calls cost $0.007228 and returned 997 comments with no duplicates. That is $0.00725 per 1,000, and the figure comes with two conditions. First, on posts with fewer than 100 comments, we got 74% to 90% of the count the post shows. Part of the gap is deleted or removed comments, which still count on the post but have no text. The rest is comments that Reddit folds behind "load more."
Second, on posts with more than 100 comments, one call returns 100. On the 771-comment thread that is 13%. With our cap you cannot get every comment from a busy thread. The clearpath comments scraper says that maxCommentsPerPost set to 0 with expandAllComments on returns the full tree. That includes replies nested 10 or more levels deep behind "continue this thread" (clearpath Store page). For this job, Apify is the better tool.
| Comments shown on the post | We got | Coverage | Time (Singapore time) | Charged |
|---|---|---|---|---|
| 771 | 100 | 13% | 00:26 | $0.000556 |
| 681 | 100 | 15% | 00:27 | $0.000556 |
| 639 | 100 | 16% | 00:27 | $0.000556 |
| 529 | 100 | 19% | 00:28 | $0.000556 |
| 478 | 100 | 21% | 00:28 | $0.000556 |
| 389 | 100 | 26% | 00:29 | $0.000556 |
| 374 | 100 | 27% | 00:29 | $0.000556 |
| 120 | 100 | 83% | 00:30 | $0.000556 |
| 118 | 95 | 81% | 00:30 | $0.000556 |
| 40 | 36 | 90% | 00:31 | $0.000556 |
| 39 | 35 | 90% | 00:32 | $0.000556 |
| 23 | 17 | 74% | 00:32 | $0.000556 |
| 16 | 14 | 88% | 00:32 | $0.000556 |
"Is the comment tree complete?" has two parts. The first part is whether nested replies come back at all. We took the two posts with 16 and 23 comments. A third-party page reader fetched each post page with its comments. The two pages showed 27 comments, and one of them was a deleted placeholder.
We searched our rows for the other 26 by the start of their text, and we found all 26. That set had 12 top-level comments, 10 second-level replies and 4 third-level replies. We also returned 5 comments that the page reader did not show. So the rows are not just top-level comments. Second- and third-level replies are there too.
The second part is structure. Every comment row in these 13 calls had seven fields: id, text, author_username, like_count, url, posted_at and platform. The catalog also lists community, but none of these responses had it, so do not depend on it. For the community name, use community from the post list or the comment url. There is no parent comment id and no depth.
You know that 14 of those rows are replies, but not who replied to whom. On the Apify side, Lite comment records carry parentId and numberOfReplies (Store page, "Example Reddit post"). automation-lab carries depth and parentId. It also states that commentCoverage is unverified and does not promise the whole tree (Store page, "Comment fields"). The clearpath update on October 6 fixed depth for replies in fully expanded threads.
What does this mean for your use case? For sentiment counts, keyword frequency, topic tagging or finding complaint quotes, a flat comment table is enough, at $0.00725 per 1,000. For "who argues with whom," "how deep the reply chains go," or "which questions the poster answered," you need a tool with parentId. We covered PRAW's MoreComments placeholder and replace_more in why Reddit comment exports are incomplete (PRAW docs). The tree that Reddit returns has unexpanded slots by design. Reddit's JSON docs call them more objects (reddit-archive wiki).
Research has seen this problem before. In 2018, Gaffney and Matias studied a widely used dataset that claimed to hold "all public Reddit comments." They found large gaps in it. They said the risk is highest for studies of user histories and network structure (arXiv paper). Whatever tool you use, store two numbers with every export: how many comments you got, and how many the post shows.
We also called reddit/post_detail twice. For the 771-comment and 40-comment posts, its comment_count matched the listing, and each call cost $0.000556. If you pick posts before you pull comments, sort by the listing's comment_count. You do not need a separate detail call.
Test 4: posts and comments by one user, and when the expensive endpoint is not worth it
reddit/user_posts returns up to 50 rows per call at the same $0.000556 as most endpoints. We first tried spez, the account of Reddit's CEO, with newest, top all time, top past year and popular. All four calls returned the same 24 posts. The oldest was from July 11, 2015, and the newest was the login-wall post of October 29. So the sort had no effect on this account, the four calls cost $0.002224, and calls two to four were wasted.
A publisher account, washingtonpost, returned a full 50 posts in one call, from April 20 to November 3, 2026, which is $0.0111 per 1,000. A second call with top all time returned the same 50 posts. NASA's account, nasa, also returned 50 posts with newest, from June 5, 2025 to October 29, 2026. So one call caps at 50 user posts, and other sorts do not reach older ones.
To go back through the full history of an active account, a paginating Apify scraper fits better. The harshmaur Reddit User Scraper says it returns a user's full post and comment history. The clearpath user content scraper says it returns up to 1,000 items per user.
reddit/user_comments is a different case. One call costs $0.032403, which is 58 times a normal call, and returns up to 200 rows. We called it once for spez with limit 200 and got 100 rows, from July 31, 2025 to October 29, 2026. That is $0.324 per 1,000. One more fact must be stated plainly.
The longest comment text in those 100 rows was exactly 300 characters, and the average was 160. The catalog field_note for this endpoint explains it. When other sources are unavailable, results come from a fallback source that cuts text to the first 300 characters. That is what happened on this call. This result is good for where a person posts, how often, and how many upvotes they get. It is not good for analysis of long comment text.
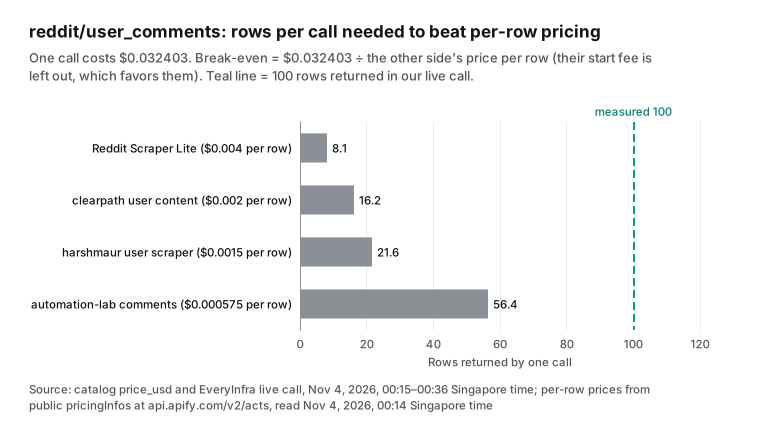
When is this endpoint not worth it? The answer depends on rows per call. Divide $0.032403 by an Apify per-row price, and you get the minimum rows per call for us to be cheaper. Against Lite at $0.004, the break-even is 8.1 rows.
Against the clearpath user content scraper at $0.002 ($0.00199 plus $0.00001 per write), it is 16.2 rows. Against the harshmaur user scraper at $0.0015, it is 21.6 rows. Against the automation-lab comment price of $0.000575, it is 56.4 rows.
| Per-row price on Apify (Free) | Break-even rows per call | Our live call returned |
|---|---|---|
| Reddit Scraper Lite, $0.004 | 8.1 | 100 |
| clearpath user content, $0.002 | 16.2 | 100 |
| harshmaur user scraper, $0.0015 | 21.6 | 100 |
| automation-lab comments, $0.000575 | 56.4 | 100 |
So skip it in three cases. First, when the user has only a few comments, such as a new account or one with a dozen posts, a per-row scraper is cheaper. Second, when you really want the discussion under one post, use reddit/comments, which is 45 times cheaper at $0.00725 per 1,000. Third, when you need long comment text and this call hits the 300-character cut, change tools or retry later.
For bulk research across many users, one call returns 100 to 200 rows. That is $0.16 to $0.32 per 1,000, or 4.7 to 9.4 times cheaper than $1.52 for the harshmaur user scraper. But if you also need karma or account age for each user, that harshmaur scraper returns them in one run.
reddit/painpoint costs even more: $0.072 per call. We did not call it, so here is only what the catalog says it sells. It finds up to 15 posts for a keyword and reads their top-level comments. It returns one summary row with posts found, comments read and rough counts of negative and positive comments. The row also lists words that repeat in negative comments, and the communities involved.
It also returns the top posts and the most-upvoted negative comments as quotes. The catalog says negative and positive come from a word list. Sarcasm and mixed tone are not judged well, so the counts are rough and are not a dissatisfaction rate. Common words such as "any" or "it's" can also show up in the top words.
You can build the same thing yourself with 1 reddit/search call and 15 reddit/comments calls. Those 16 calls cost $0.0089, and your own model can do the tagging. That is 8 times cheaper than painpoint, and you get up to 100 comments per post, not just top-level ones.
| Option | Calls | Cost | Comments read per post | How tone is judged |
|---|---|---|---|---|
reddit/painpoint | 1 | $0.072 | Top-level only | Word list, rough counts |
reddit/search + 15 × reddit/comments | 16 | $0.0089 | Up to 100, nested replies included | Your own model |
painpoint suits people who do not want to write code and want a quick look at complaints about a product. For a weekly report, building it yourself is cheaper. We showed the full method in scheduled Claude Code tasks for Reddit pain points.
Do failed and empty calls cost money?
This is where the billing rules of Apify and EveryInfra differ most. We sent six requests on purpose that could not return data.
| Case | Sent (Singapore time) | HTTP status | Response | Charged |
|---|---|---|---|---|
| No key | 00:25 | 401 | missing_key, with a hint to use the Authorization header | $0 |
sort set to hot | 00:25 | 422 | invalid_value, with the allowed values, and did_you_mean popular and top | $0 |
Extra time_filter parameter | 00:25 | 422 | unknown_param, with required and optional parameters and a working example | $0 |
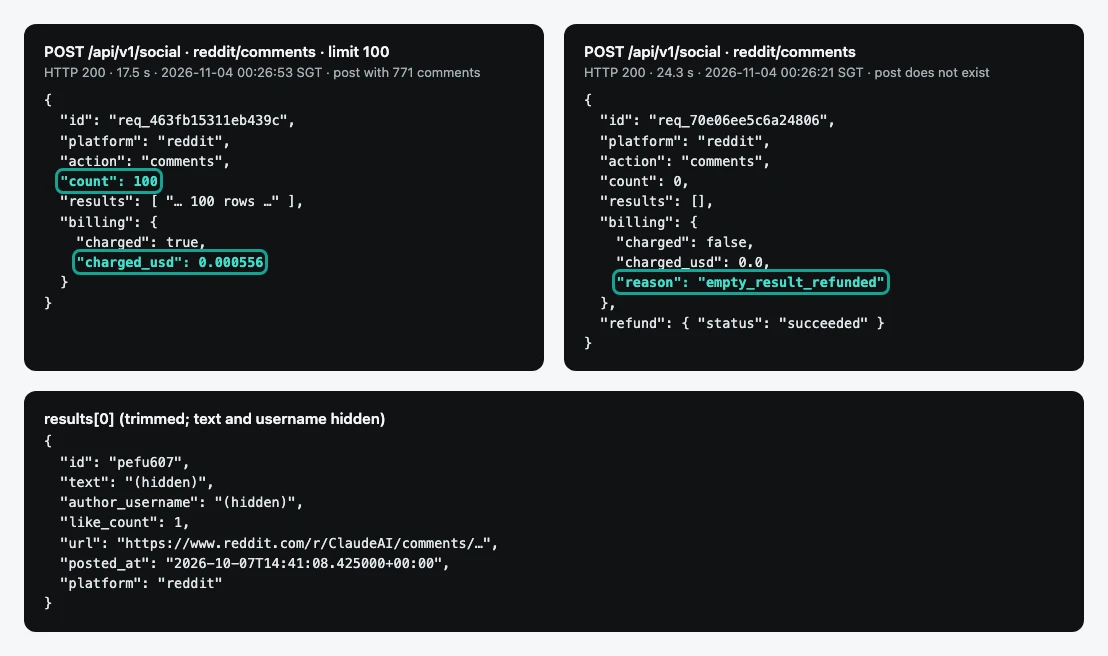
| Subreddit that does not exist | 00:26 | 200 | One placeholder row with only id, community and platform, charged as one result | $0.000556 |
| Post that does not exist | 00:26 | 200 | 0 rows, empty_result_refunded, charge refunded | $0 |
| User that does not exist | 00:36 | 200 | 0 rows, empty_result_refunded | $0 |
The first three cases are parameter errors. We check the key first and the parameters second. A wrong request gets a 4xx at once with no charge. The error says how to fix the call, so an AI client can correct it and send it again. The fifth and sixth cases are normal empty results: the request worked, but nothing matched, so the charge was refunded at once.
The fourth case needs care. For a subreddit name that does not exist, the call returns HTTP 200 and count 1. The only row has an id that starts with target-status:, and it has only the community and platform fields, with no title, text or link. That call cost $0.000556, the price of one result. So in subreddit batches, drop this row by its id prefix before you count rows or work out unit cost. If no rows are left, the name is wrong or the subreddit is gone. Remove it from your list so that you do not pay for it again.
On Apify, each actor sets its own rules. Apify's own Reddit Scraper has a "No result" event at $0.0005. It covers a deleted community, a search with no hits and a post with no comments. Each case writes one record that explains why, at that price (Store page).
automation-lab says runs with no results are not charged. The Lite start fee, charged by memory, is charged when the run starts, even if no result comes back. At the default 2 GB, that is $0.04.
Failed and timed-out runs are more common than you may expect. The next sections show that 10% of Lite's 360,000 runs in the last 30 days timed out. Apify's docs say you can set a maximum charge for each run, and the run stops at that cap (Actors in Store). Set one before a large job.
Apify Reddit Scraper Lite pricing: $0.004 per result plus a 2 GB start fee
Most people who search for "apify reddit scraper" land first on Reddit Scraper Lite by trudax. It had 8,543 users in the last 30 days, the most of any Reddit scraper in the Store. That is about 50% more than the next one. It charges for two things. Each result written to the dataset costs $0.004 on the Free tier, or $4.00 per 1,000. The Bronze tier (Starter plan) is $0.0038, Silver (Scale) is $0.0036 and Gold (Business) is $0.0034.
The user and run counts in this article come from the Store list API, read at 00:14 Singapore time on November 4, 2026. At the same time, the detail API for this actor showed 8,540 users and 363,964 runs. The two sources differ by less than 1%.
Each run also pays a start fee based on memory, at $0.02 per GB. The default memory is 2,048 MB, so a default run starts at $0.04, and the platform sets $0.04 as the minimum charge per run. All of this comes from the pricingInfos and defaultRunOptions fields in Lite's public metadata, read at 00:15 Singapore time on November 4, 2026. Apify's docs map the tiers to plans: Free pays the FREE price, Starter pays BRONZE, Scale pays SILVER and Business pays GOLD. PLATINUM and DIAMOND are for enterprise customers only (Actor pricing and costs).
| Tier (plan) | Per result | 1,000 results in one run, with the $0.04 start fee |
|---|---|---|
| FREE (Free) | $0.004 | $4.04 |
| BRONZE (Starter) | $0.0038 | $3.84 |
| SILVER (Scale) | $0.0036 | $3.64 |
| GOLD (Business) | $0.0034 | $3.44 |
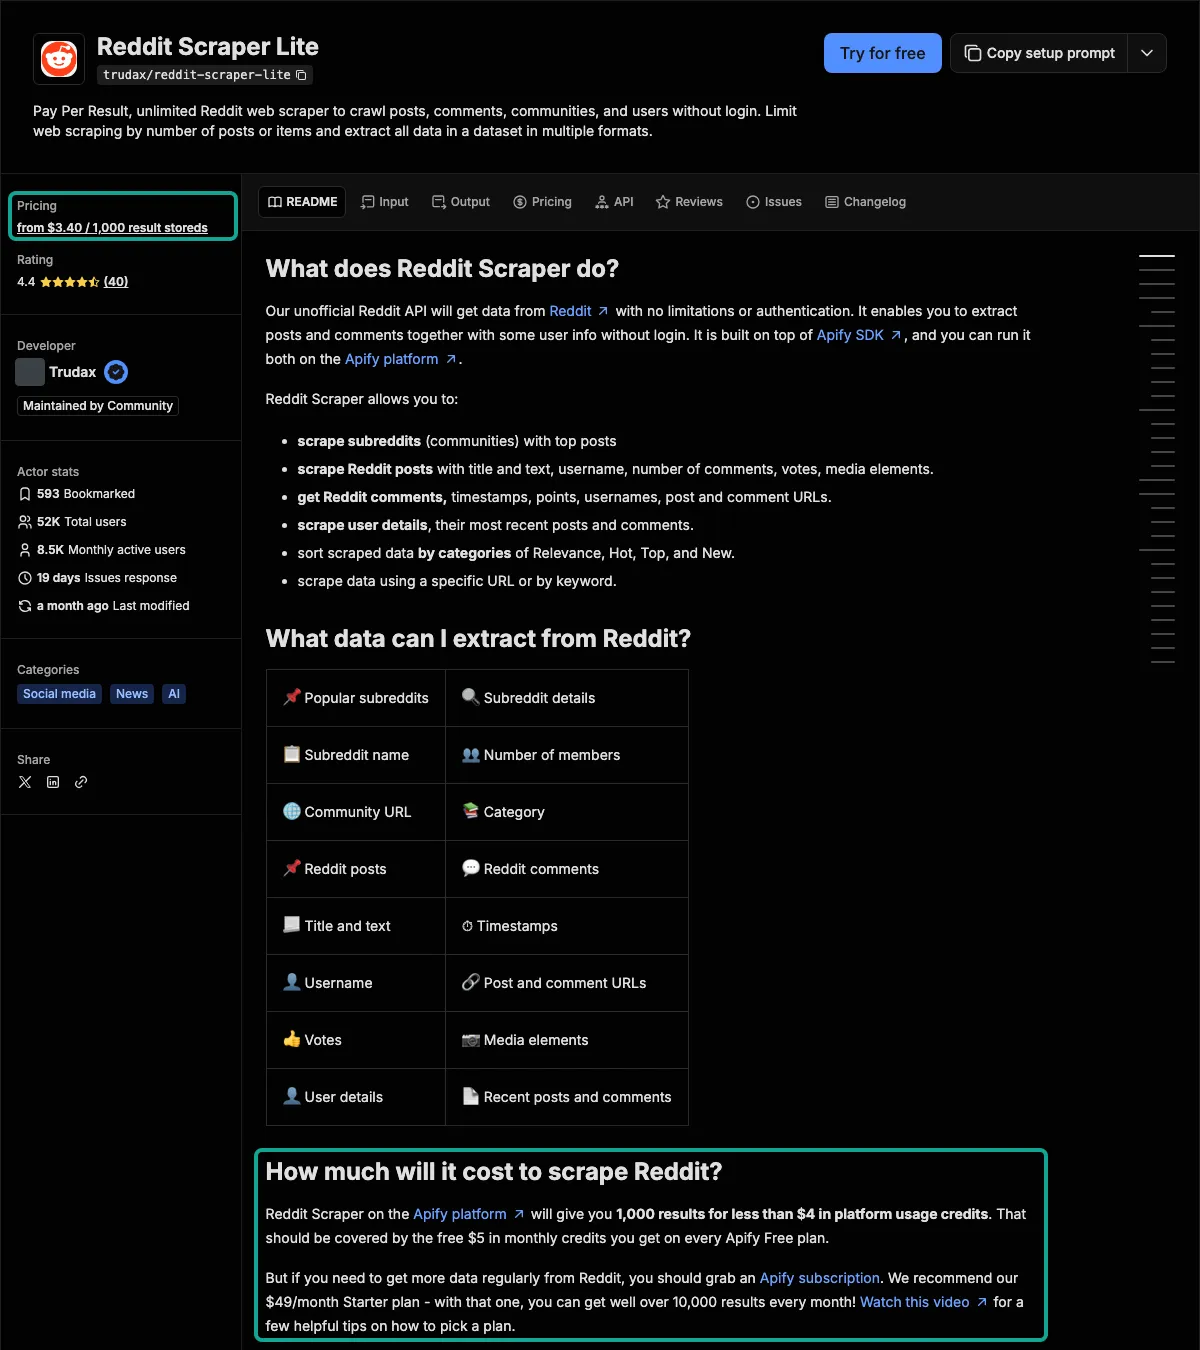
Two parts of this screenshot are easy to misread. First, "from $3.40 / 1,000" in the sidebar is the deepest discount tier. A Free user pays $4.00 plus $0.04 per run. One run for 1,000 results costs $4.04 on Free and $3.44 on Business.
Second, the "$49/month Starter plan" in the text does not match the current pricing page. That page lists $5 of monthly prepaid credit on Free, Starter from $19, Scale at $199 and Business at $999. Unused credit does not roll over. The readme text was not updated with the pricing page, so use the pricing page for your math.
One more detail is easy to miss. Lite counts "each post, comment, user and community" as one result, as the "Results" section of the Store page says. So if you ask for 100 posts from a subreddit and leave comments on, it also writes the comments under those posts to the dataset. Each one is charged at $0.004. The page offers skipComments, maxComments and maxItems. With no cap, a "100 posts" run can write thousands of rows.
"Reddit Scraper" itself is deprecated: since September 21, existing users only
Many tutorials that say "Apify Reddit Scraper" mean a different actor, trudax's Reddit Scraper. From February 2022 it was a monthly rental at $45, with a 1,440-minute trial. On September 21, 2026, it moved to pay-per-event pricing: $0.0001 per result and $0.00005 per start. The change note says that Apify is phasing out monthly rental pricing. It also says the actor will no longer be listed publicly, and existing users keep full access. That text is in the reasonForChange field of its public metadata, read on November 4, 2026.
The same metadata has isDeprecated set to true, and the Store title now carries "[DEPRECATED]". It still had 459 users in the last 30 days, but new users cannot start it. So for a new user today, the two choices with that name are Lite and Apify's own Reddit Scraper.
Apify's own scraper prices four result types separately. Posts cost $0.004 on Free and $0.0025 on Gold. Comments cost $0.0032 on Free and $0.002 on Gold. Communities cost $0.0065, users $0.002, and each start $0.001.
It also has a rare "No result" event at $0.0005. The page covers requests with no results, such as a deleted community, a search with no hits or a post with no comments. In those cases it writes one record that explains why, at a lower price than a normal result. The page also says that the same post reached from two inputs is written twice and charged twice (Store page, "How much will it cost?").
| Event in Apify's own Reddit Scraper | Free | Gold |
|---|---|---|
| Post | $0.004 | $0.0025 |
| Comment | $0.0032 | $0.002 |
| Community | $0.0065 | $0.004 |
| User | $0.002 | $0.001 |
| No result | $0.0005 | $0.0005 (one price) |
| Start | $0.001 | $0.001 (one price) |
746 Reddit scrapers in the Apify Store: price spread and run outcomes
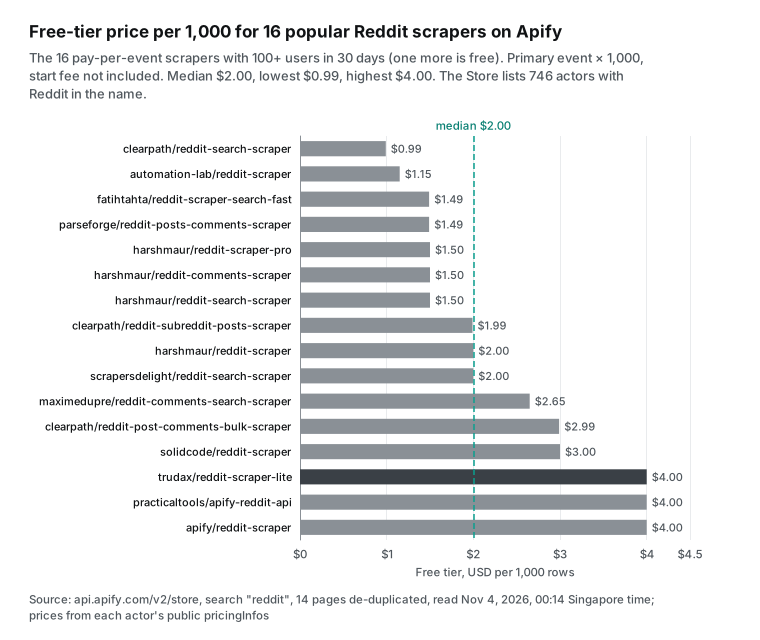
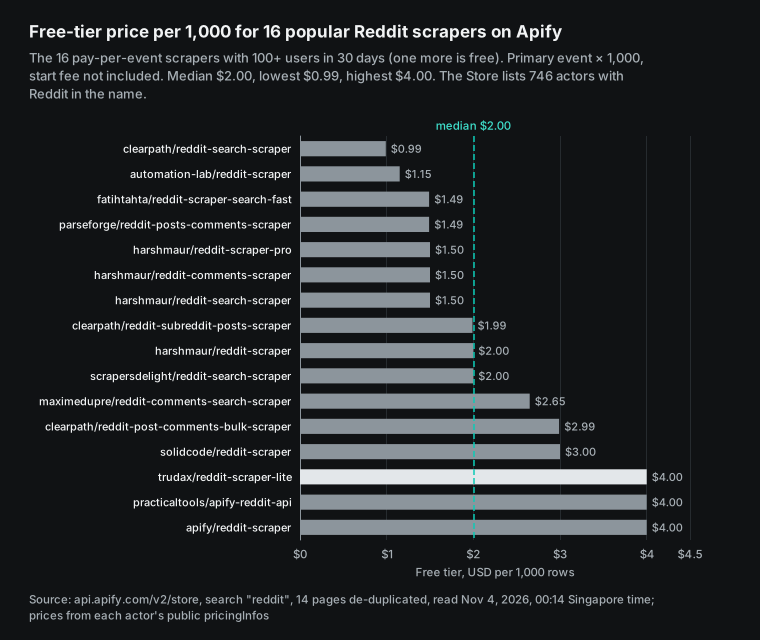
We used Apify's public Store list endpoint (Get list of Actors in Store) to search for "reddit". After 14 pages and de-duplication, 746 actors had Reddit in the title or name. Of those, 717 charge per event and 29 are free. Seventeen had at least 100 users in the last 30 days. The chart shows the Free-tier price of the main event for the 16 that charge per result. The seventeenth is a free one from red_crawler for community info and browsing.
The cheapest is the clearpath search scraper at $0.99 per 1,000. The second and third by users, the harshmaur general scraper and fatihtahta, cost $2.00 and $1.49. The harshmaur Reddit Comment Scraper is $1.50. Three scrapers share the top price of $4.00: Lite, one from practicaltools, and Apify's own. The median is about $2.00. These prices leave out start fees, which are charged per run by memory: $0.04 for Lite, $0.02 for harshmaur and $0.00099 for clearpath.
Besides price, each actor's public metadata has 30-day run stats: how many runs succeeded, failed, timed out or were aborted. The chart shows the four with the most users, plus Apify's own scraper.
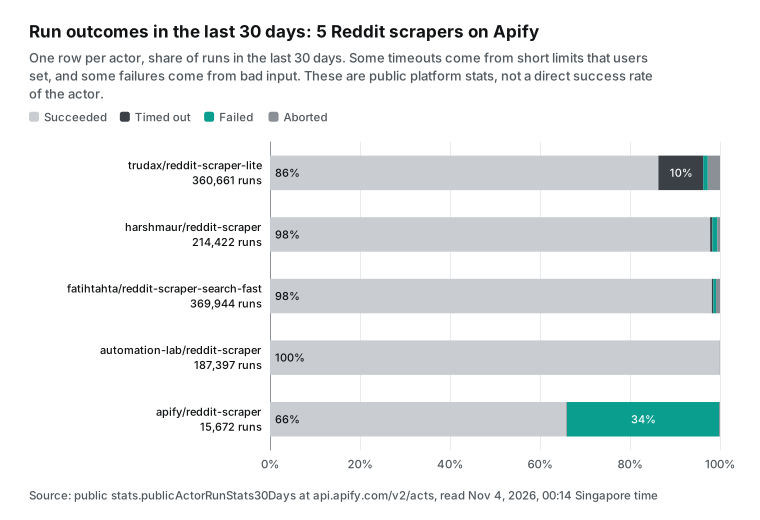
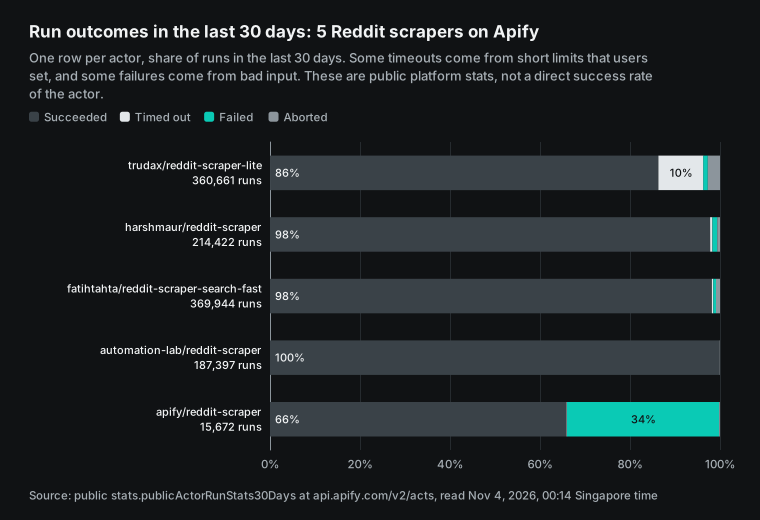
Read two numbers with care. First, 35,919 of Lite's 360,661 runs in the last 30 days timed out. That is about 10%, an order of magnitude more than the others. We can only guess at the cause. Some users may set a short time limit, and some may skip maxItems and ask for too many posts and comments in one run. A run that times out is still charged for the results already in the dataset, and the start fee is also charged.
Second, 5,296 of the 15,672 runs of Apify's own Reddit Scraper failed, about 34%. Its page says that "no result" cases write a $0.0005 record and are not failures. So these failures are more likely bad input or blocks from Reddit. These are public platform stats, not a direct success rate of each actor. Apify's docs define run states in Runs and builds.
| Actor | Runs in 30 days | Succeeded | Timed out | Failed |
|---|---|---|---|---|
| trudax/reddit-scraper-lite | 360,661 | 86.3% | 10.0% | 1.0% |
| harshmaur/reddit-scraper | 214,422 | 97.8% | 0.5% | 1.1% |
| fatihtahta/reddit-scraper-search-fast | 369,944 | 98.2% | 0.3% | 0.6% |
| automation-lab/reddit-scraper | 187,397 | 99.9% | 0.0% | 0.0% |
| apify/reddit-scraper | 15,672 | 65.9% | 0.1% | 33.8% |
The 17 popular actors had 1,526,908 runs in total: 95.3% succeeded, 2.6% timed out, 1.1% failed and 1.0% were aborted. Apify also runs a daily automated test on each public actor. An actor that keeps failing is marked "under maintenance" (Automated testing). Check the Store page for that mark before you pick one.
On our side, 46 of the 49 calls in this article returned HTTP 200. Counting only those 46, each took 6 to 41 seconds, with a median of 14 seconds. The slowest were posts with many comments and the post detail calls. The three 4xx responses were the bad parameters we sent on purpose.
No call timed out or returned a 5xx. But 49 calls are too few for a success rate. We can only say that we saw no failures in this run.
| Endpoint | Calls | Median seconds | Range |
|---|---|---|---|
reddit/search | 10 | 6.4 | 6.0 to 10.2 |
reddit/subreddit_posts | 10 | 17.8 | 9.5 to 30.7 |
reddit/comments | 13 | 22.4 | 11.4 to 40.8 |
reddit/user_posts | 7 | 12.5 | 9.1 to 14.5 |
reddit/post_detail | 2 | 23.6 | 11.2 to 36.0 |
Fields: do both sides return the same data?
The other side of a low price is fewer fields. The table below lists the fields our 49 calls actually returned, not the fields the catalog lists. Where the two differ, we say so. On the Apify side, fields vary a lot between scrapers.
The harshmaur general scraper says it returns 60 or more fields per post, with media and galleries. Lite and automation-lab comment records carry parentId. Check each Store page's sample output for the full list. We did not run them, so we do not list their fields for them.
| Endpoint | Fields actually returned | What is missing |
|---|---|---|
reddit/search, reddit/subreddit_posts | id, title, text, author_username, community, url, like_count, comment_count, posted_at, platform. Subreddit posts also have domain and flair | Image and video URLs, award and pin flags |
reddit/comments | id, text, author_username, like_count, url, posted_at, platform | Parent comment id, depth, reply count. The catalog lists community, but real responses did not have it. Do not depend on it |
reddit/user_comments | id, text, author_username, like_count, post_id, post_title, url, posted_at, platform | Text can be cut to 300 characters. No karma or account age |
For most "what are people saying" jobs, these columns are enough. Comments have text, author, upvotes and time. Posts have title, community and comment count, so you can pick posts by comment count and then pull their comments. You can pass a post url straight to reddit/comments, and the Python example below chains the calls that way. If you need media files, comment trees or user profiles, a scraper with more fields on Apify fits better. That is what the per-row price buys.
One more point affects billing. Lite runs with a default time limit of 3,600 seconds and 2,048 MB of memory (the defaultRunOptions field in Lite's public metadata). More memory means a higher start fee. Usage and resources says memory also sets how much CPU a run gets.
Less memory saves on the start fee, but the run is slower and more likely to hit the time limit. We have no memory or time limit to tune. One request has one price, and our slowest call, at 41 seconds, still cost $0.000556.
Apify prices change often
Every price period in the public metadata of the 15 Reddit actors we read carries a startedAt date. Apify's own Reddit Scraper had 8 price periods from 2026-09-25 to 2026-10-20, and four of them started on October 1, 2026 alone. The current period started on 2026-10-20, and the page was last changed on 2026-10-27. The current price of the maximedupre comment search scraper started on 2026-10-18. automation-lab has announced a comment price rise from 2026-11-17. The old trudax Reddit Scraper moved to pay-per-event pricing and was deprecated on 2026-09-21.
In contrast, the current Lite price has not changed since June 30, 2026. What this means for you: any price comparison, this one included, can be out of date in a month or two. Before you buy, read pricingInfos again with the Get Actor endpoint, and write down when you read it.
| Actor | Current price started | What changed |
|---|---|---|
| apify/reddit-scraper | 2026-10-20 | Eighth price period since 2026-09-25 |
| maximedupre/reddit-comments-search-scraper | 2026-10-18 | $0.00265 per comment on Free |
| automation-lab/reddit-scraper | 2026-08-25, next on 2026-11-17 | Comment price up 30% |
| trudax/reddit-scraper | 2026-09-21 | Pay-per-event, then deprecated |
| trudax/reddit-scraper-lite | 2026-06-30 | No change since |
The full endpoint list is in the API reference. The rules for per-event billing are in the pay-per-event docs.
Use it from code and AI clients
This Python is the same method as our comment test. It takes a set of post URLs and calls reddit/comments once for each. It de-duplicates by comment id and adds up charged_usd from each call. It also stores two numbers per post, the post's comment count and the rows we got, for coverage. It skips any row whose id starts with target-status:, for the reason in the failure section.
import os, requests

API = "https://api.everyinfra.com/api/v1/social"
HEADERS = {"Authorization": f"Bearer {os.environ['EVERYINFRA_API_KEY']}"}

def call(action, **params):
    r = requests.post(API, headers=HEADERS, timeout=120,
                      json={"platform": "reddit", "action": action, "params": params})
    r.raise_for_status()
    body = r.json()
    rows = [x for x in body["results"] if not str(x.get("id", "")).startswith("target-status:")]
    return rows, body["billing"]["charged_usd"]

posts, spent = call("subreddit_posts", subreddit="Python", sort="top", date_range="past_year", limit=100)
seen, coverage = {}, []
for p in posts[:13]:
    rows, cost = call("comments", url=p["url"], limit=100)
    spent += cost
    seen.update({c["id"]: c for c in rows})
    coverage.append((p["url"], p["comment_count"], len(rows)))

print(len(seen), "unique comments, spent", round(spent, 6), "USD")
for url, listed, got in coverage:
    print(f"{got}/{listed}", url)
In an AI client, connect our remote MCP server at https://api.everyinfra.com/mcp. Tool names start with everyinfra_, and the model can decide whether to search posts first or pull comments directly. Below is a general config example. Claude Code, Cursor and other clients with remote MCP support use a similar format.
For the exact syntax, see the Claude Code MCP docs and the Cursor MCP docs. OpenAI has its own MCP docs. The protocol itself is in the MCP specification.
{
  "mcpServers": {
    "everyinfra": {
      "type": "http",
      "url": "https://api.everyinfra.com/mcp",
      "headers": { "Authorization": "Bearer ${EVERYINFRA_API_KEY}" }
    }
  }
}
Apify has its own MCP server that exposes Store actors as tools to a model (Apify MCP docs, source on GitHub). For code, it has a Python client. The difference is in how the data comes back. Apify's MCP has the model start an actor run, wait for it to finish, and then read the dataset.
That suits exports of tens of thousands of rows. Our MCP returns one page of data per call. That suits questions in a chat, one at a time. See the MCP server page for setup and supported clients.
A monthly bill: three common jobs for 30 days
Take a product team that wants to know what Reddit says about its category every day. The three jobs below use the rows per call we measured. On our side, the cost is calls × $0.000556, or × $0.032403 for user comments. On the Apify side, we used each actor's Free-tier list price, with one default start fee per job run.
| Job for 30 days | Calls and rows | EveryInfra | Reddit Scraper Lite | Cheaper popular scrapers on Apify |
|---|---|---|---|---|
| Comments from 10 busy threads per day, 100 per thread | 300 calls, 30,000 rows | $0.17 | $121.20 | automation-lab $17.69 ($22.94 from November 17). harshmaur comments $45.60 |
| Newest 100 posts from 5 subreddits per day | 150 calls, 15,000 rows | $0.08 | $61.20 | automation-lab $17.34. clearpath subreddit $30.02 |
| Comment history of 200 users per week, 100 rows each | 800 calls, 80,000 rows | $25.92 | $320.16 | harshmaur user scraper $120.08. clearpath user content $160.00 |
These estimates rest on three assumptions. First, every call returns a full page. In our tests, every post with more than 100 comments did return 100. But small posts return fewer, and the user comments call with limit 200 returned only 100.
When we return fewer rows, our total stays the same and our unit price goes up. Second, the Lite row assumes that comment scraping is off (skipComments). If it is on, the post rows grow several times. Third, none of the jobs removes overlap between days.
If you pull the same busy thread the next day, most comments are ones you already have, and both sides charge for the repeats. On Apify, time filters can cut the repeats. On our side, you de-duplicate by id yourself.
Even so, user comments cost us $0.032403 per call. If most of those 200 users have only a dozen comments, our total stays the same. The per-row total on Apify drops to a few dollars, and Apify is the better buy.
Reddit's own API today: no new access requests since October 31
No price comparison is complete without Reddit's own Data API. The Reddit Data API Wiki says eligible users get 100 requests per minute per OAuth client, averaged over a 10-minute window. Traffic without OAuth is blocked. If a post or comment is deleted, you must delete your copy too, and Reddit suggests a cleanup at least every 48 hours.
Outside free use, section 3.1 of the Data API Terms is clear. Reddit keeps the right to charge for future use, at rates it decides. Commercial use, research above the rate limits, and any use the terms do not allow need a separate agreement. The terms took effect on June 19, 2023, and were last revised on July 20, 2026.
| Rule in Reddit's own pages | What it says |
|---|---|
| Free rate limit | 100 requests per minute per OAuth client, averaged over 10 minutes |
| Traffic without OAuth | Blocked |
| Deleted content | Delete your copy, with a cleanup at least every 48 hours |
| Commercial use | Separate agreement, at rates Reddit sets |
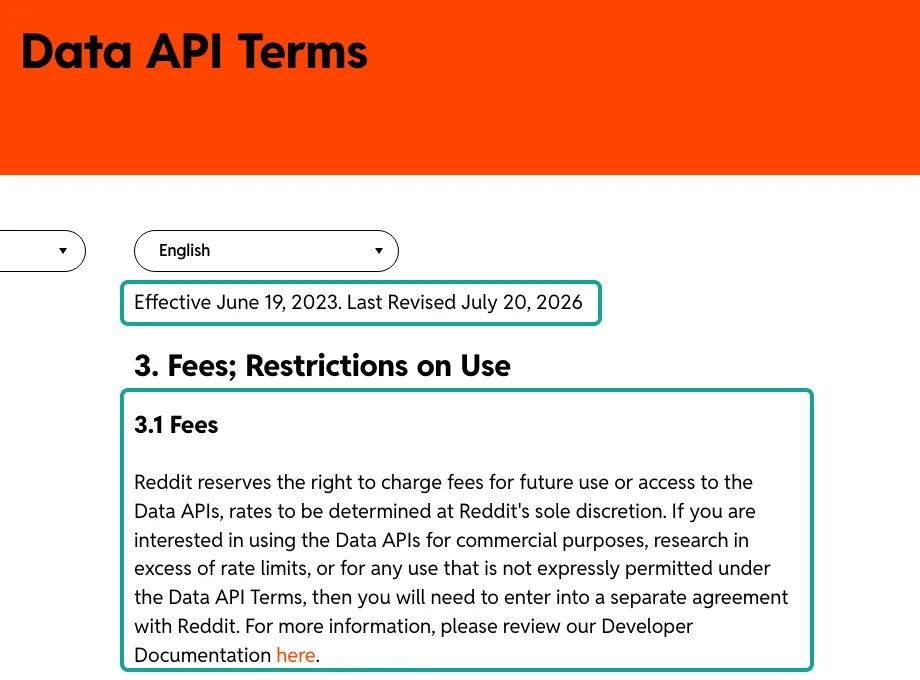
Reddit's current public pages do not give a price for commercial use. Developer Platform & Accessing Reddit Data says only that some developers who need more access may have to pay. It lists examples of commercial use. These include apps with ads or paywalls, services or data access sold for a fee, and subscription services. Selling models trained on Reddit data is also on the list.
The figure of "$0.24 per 1,000 requests" that you often see comes from 2023. On May 31, 2023, Reddit announced on r/redditdev that free-tier rate limits would apply from July 1 (post). The same day, the developer of the Apollo client said Reddit had quoted him $12,000 per 50 million requests (post). That is $0.24 per 1,000.
It is one developer's report, not a price list from Reddit. At that price, with 100 rows per list request, 1,000 posts would cost about $0.0024, less than any third party. But only if you can get that contract.
That path is closing. In August 2026, Reddit first described its plans for the public Data API on r/redditdev (post). On September 30, 2026, it posted the shutdown timeline (post).
| Date | What Reddit's post says | What it means if you collect data |
|---|---|---|
| 2026-10-31 | No new public API access requests | A project that starts today cannot get access |
| 2026-11-10 | Migration progress update and deadline reminder | Check for extensions or exceptions |
| 2026-11-13 | RSS ends (r/modnews post; replacements in after the Reddit RSS shutdown) | RSS-based subreddit monitoring breaks |
| 2026-11-30 | Deadline for the migration bounty | Only for apps that move to Devvit |
| 2027-01-12 | Access starts to close for apps and users that did not register or answer Reddit | Old scripts may stop around this date |
| 2027-03 | All remaining public access closes (no exact day given) | Only partners with written agreements, and Devvit |
The replacement Reddit offers is its own developer platform, Devvit. The migration guide says it is mainly for moderation tools and community apps. Apps in the migration program can earn $1,000 after they move, and the program runs from March 31 to December 31, 2026. It is not an API for exporting data to analyze elsewhere. Devvit apps register through App registration. Outbound requests follow the HTTP Fetch rules, and the full guide is in the Devvit docs.
For researchers, the Responsible Builder Policy says that research on data collected outside the Reddit for Researchers program breaks the policy. Without written approval, you may not sell or license the data or use it to train models.
On October 29, Reddit CEO Steve Huffman posted on his profile that Reddit will move to a "logged-in first" experience. It will test this first in some markets outside the US. One reason he gave is that most unauthorized data collection happens on logged-out pages (post). Axios reported the same day that the home page will stay open to logged-out visitors. Posts reached from search engines or outside links will also stay open, with the exact limits set during the test.
The login wall is a risk for every tool that reads pages without login. That includes the scrapers in the Apify Store, and it includes us. We cannot promise that every endpoint keeps working after Reddit changes.
You can do three things. First, failed requests are not charged, so you do not pay when Reddit blocks a call. Second, when an endpoint breaks, the free catalog marks it "temporarily unavailable" with available set to false, so read the catalog before a large batch. Third, save the data you need long term on your side, and do not depend on one tool to fetch it again later.
Whether you may collect data, and what you may do with it, depends on your jurisdiction, your use and Reddit's terms. This article is not legal advice. For a specific project, ask a lawyer.
When Apify is the better choice
Taken together, the tests point to six jobs where we suggest a scraper from the Apify Store, not EveryInfra. First, posts on a topic from more than a month ago. Our reddit/search covers only the last month, and Lite's time can be set to all. Second, more than 1,000 posts from one subreddit: we return only the first 100 rows per sort, and eight combinations on r/Python gave 286. A scraper that paginates gets close to 1,000 per sort.
Third, every comment on a busy thread, or the full comment tree. We cap at 100 per post with no parent id, while clearpath expands everything and Lite and automation-lab carry parentId and depth. Fourth, user profiles: we have no karma or account age, and the harshmaur user scraper returns them in one run. Fifth, a handful of users: below 22 comments per call, reddit/user_comments costs more than the harshmaur user scraper. Sixth, teams already on Apify schedules, datasets and integrations. A switch means you write your own scheduler and storage, and the savings may not cover that work.
The opposite case is large, frequent, page-by-page data. There we are two to three orders of magnitude cheaper. Examples are comments from hundreds of posts a day and new posts from dozens of communities a day. Reddit lookups from an AI client in a chat are another. We also have reddit/trending_posts. It returns site-wide trending posts at 25 per page, pages through page_token, and costs $0.000556 per page.
It fills part of the gap left by unpaginated subreddit listings. But it is trending posts across the whole site, not one community's history. We covered the traps in both billing models in how Apify pricing works and Apify alternatives. To reconcile refunds, see failure refund reconciliation.
What changed recently
- 2026-11-17: the automation-lab Reddit scraper raises its Free-tier comment price from $0.000575 to $0.00075, up 30% (automation-lab Store page). What it means for you: the $0.59 per 1,000 comments in this article becomes $0.76.
- 2026-10-29: the Reddit CEO's post on the login wall (post). What it means for you: logged-out access tightens first in some markets. Every tool that reads pages without login may feel it, Apify scrapers and ours alike.
- 2026-10-20: the current price of Apify's own Reddit Scraper takes effect, its eighth price period in a month (Store page). What it means for you: use the metadata from the day you read it.
- 2026-10-18: the current price of the maximedupre comment search scraper takes effect, at $0.00265 per row on Free. What it means for you: among comment search scrapers, it is 77% more than harshmaur at $0.0015.
- 2026-10-16 and 2026-10-06: two updates to the clearpath comments scraper fix
depthfor deep replies in fully expanded threads (clearpath Store page). What it means for you: to rebuild trees fromdepth, use a version from after these updates. - 2026-09-21: trudax's Reddit Scraper moves to pay-per-event pricing and is delisted for new users. What it means for you: the "$45 per month, no limits" plan in old tutorials is gone.
Get started: from one trial call to a daily job
The 48 calls in this article, without the user comments call, cost about $0.024 in total. Sign up, run a small test first, and then decide whether to use it in bulk. Get a key in the quickstart. The Reddit Scraper API page lists all endpoints. Run the playground once each for Reddit search, subreddit posts and Reddit comments.
For post detail and user data, see post detail, user posts and user comments. For a quick look at complaints about a product, use Reddit pain points. For site-wide trending posts, use trending posts. The same method works for the Twitter Scraper API and the TikTok Scraper API. All endpoints and prices are on the data market and pricing pages, and tool comparisons are on the alternatives page.
Other measured "cost per 1,000" comparisons with Apify: Apify Twitter Scraper alternative, Apify TikTok Scraper alternative and Apify Amazon Scraper alternative.
FAQ
Is the Apify Reddit scraper free?
The Apify Free plan gives $5 of prepaid credit per month (pricing page). At $0.004 per result plus $0.04 per run for Lite, that is about 1,200 results. The Store also has 29 free Reddit actors, but only one of them had more than 100 users in the last 30 days. The monthly-rental Reddit Scraper from trudax is deprecated, and new users cannot start it. Reddit's own API is free for eligible non-commercial use at 100 requests per minute per OAuth client. But it stopped taking new requests on October 31, 2026 (Data API Wiki).
Which one is the "Apify Reddit scraper pro," and is it better than Lite?
The Reddit scraper with "pro" in its name and the most users in the last 30 days is harshmaur's reddit-scraper-pro. Its title is about leads, brand monitoring and alerts. It costs $0.0015 per row on Free and had 435 users in 30 days. Of its runs, 98.7% succeeded (public Store list, read on November 4, 2026). It is more than 60% cheaper than Lite, with far fewer timeouts.
Lite has the most users, the fullest readme, and parentId on comments. Which one is "better" depends on whether you need comment trees. If you do, the clearpath comments scraper is more complete than both.
Can an Apify Reddit comment scraper get every comment on a post?
Yes, if you pick the right actor and set it up. The clearpath comments scraper with maxCommentsPerPost set to 0 and full expansion on returns the whole tree, including deep "continue this thread" replies. Lite sets its cap with maxComments. Reddit's own tree has unexpanded more slots by design (Reddit JSON notes).
If you scrape with PRAW, you also need replace_more. Our reddit/comments returns up to 100 rows per post, with second- and third-level replies but no parent id. It does not fit jobs that need the whole tree.
What does a Reddit scraping API cost, and which is cheaper?
Commercial use of Reddit's own API needs a separate agreement, and the current public pages give no price (Developer Platform & Accessing Reddit Data). The often-quoted $0.24 per 1,000 requests is one developer's 2023 report. Among third parties, popular Reddit scrapers in the Apify Store cost $0.99 to $4.00 per 1,000, with a median of about $2.00. EveryInfra charges per request, and in this article that came to $0.011 to $0.029 per 1,000 posts and $0.0073 per 1,000 comments. For the OAuth flow and endpoint list, see Reddit's OAuth2 notes and the API docs.
Is scraping Reddit without the API legal?
It depends on your jurisdiction, your use, and Reddit's User Agreement, Developer Terms and Public Content Policy. Reddit's Responsible Builder Policy says that research on data collected outside the Reddit for Researchers program breaks the policy. Without written approval, you may not sell or license the data or train models on it. This article is not legal advice. Ask a lawyer before you build a commercial product or train a model on the data.
Is there a Reddit scraper on GitHub, and how does it compare with an API service?
Yes. Reddit's early site code and API notes are archived at reddit-archive/reddit, which no longer gets updates. The most common ready tool is the Python library PRAW. It uses Reddit's OAuth API, is free and has the most fields. But it is limited to 100 requests per minute, and new OAuth clients cannot get access after October 31, 2026.
A home-made scraper must handle the login wall, rate limits and blocks. With Apify or a service like ours, you pay to skip that work. Whatever tool you pick, work out the cost per 1,000 and the start fees first.
References
- Apify / trudax: Reddit Scraper Lite (Store page), read November 4, 2026
- Apify API: public metadata for trudax~reddit-scraper-lite (pricingInfos, stats), read November 4, 2026
- [Apify / trudax: Reddit Scraper [DEPRECATED] (Store page), read November 4, 2026](https://apify.com/trudax/reddit-scraper)
- Apify API: public metadata for trudax~reddit-scraper (with the September 21, 2026 pricing note), read November 4, 2026
- Apify / harshmaur: Reddit Scraper (Store page), read November 4, 2026
- Apify / automation-lab: Reddit Scraper (Store page, with the November 17, 2026 price change), read November 4, 2026
- Apify / clearpath: Reddit Post Comments Scraper (Store page, with October 6 and October 16, 2026 updates), read November 4, 2026
- Apify / fatihtahta: Reddit Scraper Enterprise Grade (Store page), read November 4, 2026
- Apify / harshmaur: Reddit Comment Scraper (Store page), read November 4, 2026
- Apify / harshmaur: Reddit User Scraper (Store page), read November 4, 2026
- Apify / clearpath: Reddit User Posts & Comments Scraper (Store page), read November 4, 2026
- Apify / clearpath: Reddit Search Scraper (Store page), read November 4, 2026
- Apify: Reddit Scraper: Posts, Comments, and Users (Apify's own Store page), read November 4, 2026
- Apify: Pricing page (plans, compute units, Store discount tiers), read November 4, 2026
- Apify docs: Pay-per-event pricing model
- Apify docs: Actor pricing and costs (FREE to DIAMOND tiers)
- Apify docs: Actors in Store (pricing models, under-maintenance label, Store discounts)
- Apify API docs: Get Actor
- Apify API docs: Get list of Actors in Store
- Apify docs: Usage and resources (memory and compute units)
- Apify docs: Runs and builds (run status, timeouts)
- Apify docs: Automated testing (failing Actors get the maintenance label)
- Apify docs: Dataset
- Apify docs: Apify MCP server
- GitHub: apify/apify-mcp-server
- GitHub: apify/apify-client-python
- Reddit: Data API Terms (effective June 19, 2023, revised July 20, 2026), read November 4, 2026
- Reddit: Developer Terms
- Reddit: User Agreement
- Reddit Help: Reddit Data API Wiki (free tier, 100 QPM)
- Reddit Help: Responsible Builder Policy
- Reddit Help: Developer Platform & Accessing Reddit Data (commercial use and fees)
- Reddit Help: Public Content Policy
- Reddit Help: App Migration Program 2026 Terms
- Reddit Developer Platform: Migrating apps from the Data API to Devvit
- Reddit Developer Platform: App registration
- Reddit Developer Platform: HTTP Fetch
- r/redditdev: Moving Data API Apps to the Developer Platform: migration dates and next steps (September 30, 2026)
- r/modnews: Continuing our infrastructure updates: what's changing in the coming months (September 30, 2026, RSS end)
- r/redditdev: Our Plans for the Future of Reddit's Public Data API (August 2026)
- r/redditdev: API Update: Enterprise Level Tier for Large Scale Applications (May 31, 2023)
- r/apolloapp: Had a call with Reddit to discuss pricing (May 31, 2023, a developer's account of the quote)
- u/spez: About that login screen (October 29, 2026)
- Axios: Reddit moves to logged-in experience as AI eats search (October 29, 2026)
- GitHub: reddit-archive/reddit (Reddit's archived open-source code and wiki)
- Reddit Developer Platform: Devvit docs
- Apify API docs: API v2 reference
- GitHub: reddit-archive/reddit wiki, JSON (the more object)
- GitHub: reddit-archive/reddit wiki, OAuth2
- GitHub: praw-dev/praw
- PRAW docs: Comment Extraction and Parsing
- Reddit: API documentation (/dev/api)
- Gaffney and Matias: Caveat Emptor, Computational Social Science: Large-Scale Missing Data in a Widely-Published Reddit Corpus (arXiv, 2018)
- Model Context Protocol: Specification 2025-06-18
- Claude Code docs: Connect Claude Code to tools via MCP
- OpenAI docs: Connectors and MCP servers
- Cursor docs: Model Context Protocol
- EveryInfra: data API catalog (free; price_usd, max_limit), read November 4, 2026
Reference BL-84