Claude Sheets MCP: Put Reviews, Reddit and Search Rows in One Sheet
Claude Sheets cannot call connectors. We tested the fetch: 458 public rows over a remote MCP for $0.0058. Sheet steps follow the help page.
Claude Sheets went into beta on November 10, 2026. Its help page lists one limit that shapes any data sheet: "Sheets can't pull live data from connected apps" (Claude Sheets help page, updated November 16, 2026). So a sheet cannot call a connector by itself. The route that works has two steps.
First, Claude calls a remote MCP server in the chat. Then Claude writes those rows into a sheet. On November 18, 2026, from 00:17 to 00:29 SGT, we made 5 billed calls to the EveryInfra remote MCP and REST API. They returned 458 rows of public data for $0.005751 in total.
From those calls, a 500-row sheet costs $0.0113 to $0.0462 in API fees. The share of search rows sets almost all of that range.
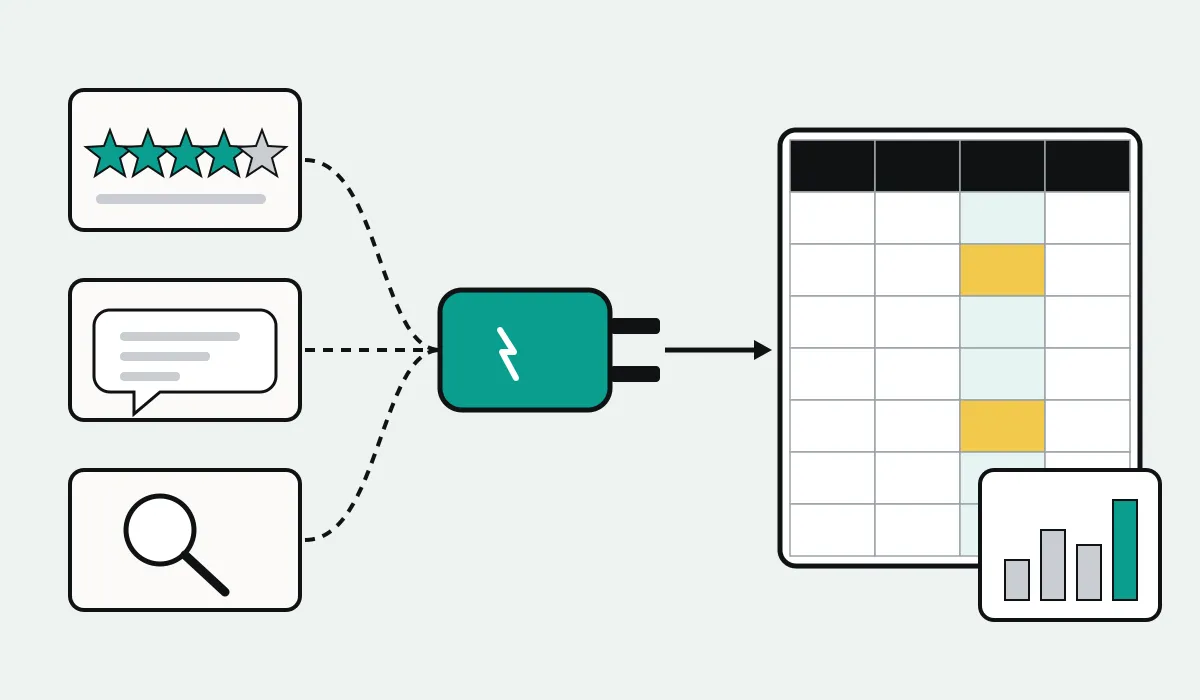
Our example brand is the sportswear label Gymshark. It has many reviews on Trustpilot, its own community on Reddit, and many review pages in web search. So all three kinds of data are available for a weekly brand-feedback sheet. The fetch numbers come from our 5 calls. We did not run the Claude-side steps in Claude Sheets: adding the connector, building the sheet, the prompts and the formulas. We wrote them as configuration examples from Anthropic's help pages and public videos. Read those steps as examples, not as test results.
What Claude Sheets is: the November 10, 2026 beta
Claude Sheets is a spreadsheet inside Claude. Anthropic's launch post says Claude can build a sheet from one prompt, with tabs, formulas, formatting and dropdowns. Claude edits cell by cell and outlines each change.
You can share a sheet, and your team and Claude can edit the same cells (Anthropic launch post, 2026-11-10). Claude Whiteboards shipped on the same day. Claude Dashboards became Claude Data and left beta (Claude post on X, 2026-11-10). TechCrunch put these products in one batch of work tools from Anthropic's San Francisco event (TechCrunch, 2026-11-10).
The help page lists the plans and switches. Claude Sheets is a beta on the Pro, Max, Ultra, Team and Enterprise plans. It is on by default for Team. For Enterprise it is off, and an Owner turns it on under Organization settings > Artifacts > Templates (Claude Sheets help page). The pricing page shows Pro at $17 per month on annual billing or $20 on monthly billing. It lists Sheets and Whiteboards under Pro, and the Free plan does not have them (Claude pricing, read 2026-11-18).
Sheet work counts toward your plan's usage limit. Chat uses the same limit (usage limits). These help page items matter for our task.
| Item | Help page text (read 2026-11-18) | Effect on a public-data sheet |
|---|---|---|
| Sheet features | Tabs, cross-tab formulas, conditional formatting, dropdowns, checkboxes, charts | Topic columns, means, counts and charts fit in the sheet |
| Size | At least 200,000 filled cells per sheet | 500 rows x 15 columns = 7,500 cells |
| Charts | Bar, line, pie, and other types Claude can generate | Star mix, topic share and weekly trend all fit |
| Not yet available | Pivot tables, protected ranges, shared filter views, multi-select dropdowns, PDF export | Summaries need formulas or a summary tab |
| Live data | No live data from connected apps; docs, decks and dashboards cannot use a sheet as a source | Get data in the chat first |
| Platforms | Web and desktop; limited on mobile | Build sheets on a computer |
| Data controls | No HIPAA or ZDR in the beta | Keep sensitive data out |
The size figure changed within one week. On November 11, 2026, a third-party guide recorded "up to 100,000 cells per sheet" (Fynl guide). The version we read on November 18 says "at least 200,000 filled cells". That page was last modified at 23:07 UTC on November 16. Beta numbers still move, so read the help page on the day you plan a large sheet.
For scale, one Google Sheets file holds up to 20 million cells (Google Drive file limits). One Excel worksheet holds 1,048,576 rows by 16,384 columns (Excel specifications and limits). Claude Sheets is for light, shared sheets. The help page itself points to Claude for Excel or Claude for Google Workspace when the file already lives in those tools.
Can Claude Sheets call an MCP connector? The claude sheets mcp answer
No. The help page says: "Sheets can't pull live data from connected apps, and docs, decks, and dashboards can't use a sheet as a data source" (Claude Sheets help page). The limit applies to the sheet itself. A sheet does not bind to a connector and refresh on a schedule. Claude Data does that. It needs a data connector, such as a warehouse or a CRM (Claude Data help page, Anthropic post of October 8). Each Claude Data chart shows when its data last refreshed.
The Whiteboards help page has a similar rule. Claude works only from what is on the board and does not use context from connected apps (Claude Whiteboards help page).
Connectors still work in the chat. The help center says a connector lets Claude fetch data from your apps and act in them. A custom connector points at a remote MCP server.
You turn each one on or off from the "+" menu in a chat (connectors help page). After you connect an app, Claude uses it when it is relevant (how Claude suggests connected apps). So the fetch happens in the chat, and the write happens in Sheets. The context of one chat connects the two steps.
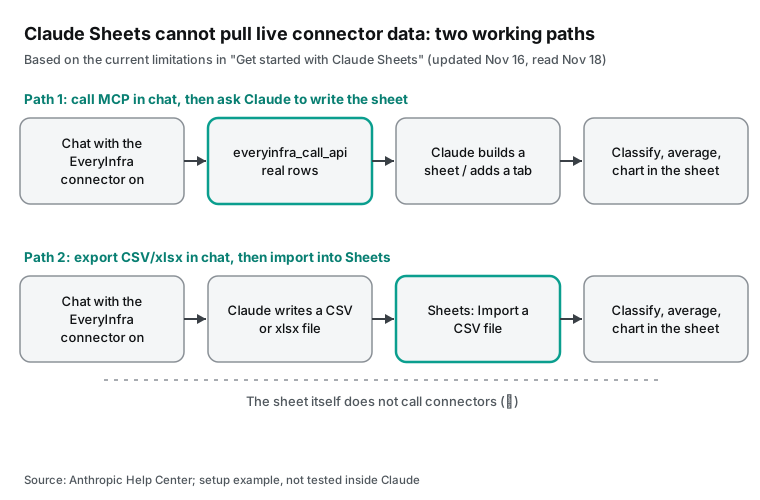
Path 1 depends on Claude keeping the data in the chat. Path 2 uses a file as the handoff. Both paths end in the same sheet, but traceability differs. In path 1, every row is still in a tool result in the chat. You can ask Claude to go back and check a row. In path 2, the file is a snapshot, and only the file name links the sheet to the chat.
A sheet can also continue across chats. In a ZDNET test on November 16, the author pasted the link of an existing sheet into a new chat. Claude then added a tab to that original sheet (ZDNET review). So you can fetch this week's data in this week's chat and add it to last week's sheet.
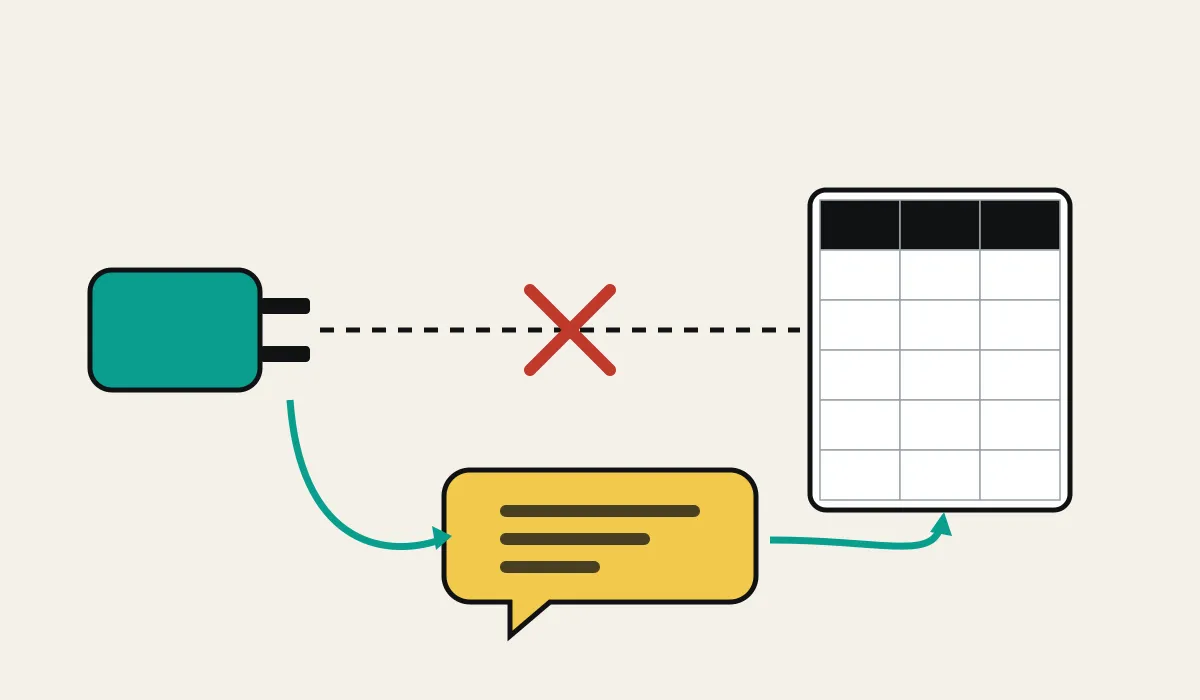
Why did Anthropic split it this way? The help page does not say, so this is our inference. A sheet is a file that several people edit. If it called a connector by itself, each viewer would fetch data with somebody's connector permissions.
The permission boundary would blur. Claude Data handles this with live sharing. Viewers see results of queries that you approved, and they cannot run other queries with your access (Anthropic launch post). Sheets has no such layer yet, so data enters a sheet only through one explicit call in a chat.
Add EveryInfra as a claude sheets connector: two ways
To fetch public data in a chat, use one of the two EveryInfra remote MCP endpoints. https://api.everyinfra.com/mcp takes an API key in a request header. https://api.everyinfra.com/mcp/all uses OAuth, so each person signs in with their own account (MCP server page).
At 00:19 SGT on 2026-11-18, we read the protected resource metadata for /mcp/all. The authorization server is https://auth.everyinfra.com/oidc. The scopes include data:call and search:call (protected resource metadata). A request to /mcp/all without credentials returned 401. Its WWW-Authenticate header points to that metadata. The MCP authorization spec asks for this discovery flow (MCP authorization spec), and RFC 9728 defines the metadata format (RFC 9728).
Anthropic documents the steps to add a custom connector (add a connector that isn't in the directory). On Pro, Max and Ultra, open Customize > Connectors and click "+ Add". Then choose "Add custom connector" and enter a name and the server URL. On Team and Enterprise, an Owner adds the connector in organization settings. Each member then clicks Connect once (custom connectors help page, updated 2026-11-13).
The Free plan allows one custom connector. The connection starts from Anthropic's cloud. So the server must accept public traffic on port 443 (Anthropic IP addresses). Both EveryInfra endpoints meet that rule.
Configuration example (Customize > Connectors > + Add > Add custom connector)

Way A: OAuth, each person uses their own account
  Name:            EveryInfra
  MCP server URL:  https://api.everyinfra.com/mcp/all
  Authentication:  Sign in when needed
  OAuth client:    Use Claude's published identity (else Register automatically)

Way B: API key in a request header, one wallet for the organization
  Name:            EveryInfra
  MCP server URL:  https://api.everyinfra.com/mcp
  Authentication:  No sign-in
  Request headers: Authorization = Bearer <your EveryInfra API key>
Way B has a condition that is easy to miss. The request-header credential is still a beta for a limited set of organizations. Outside that set, the Request headers field does not show at all (connector authentication docs). In that case, use Way A.
Claude sends the header value exactly as you type it. It does not add "Bearer " for you, so type the prefix and the space. You cannot change the authentication method later. To change it, delete the connector and add it again (add a connector that isn't in the directory).
| Item | Way A: `/mcp/all` + OAuth | Way B: `/mcp` + header key |
|---|---|---|
| Who pays | Each caller's own wallet | The wallet of the shared key |
| Option in Claude | Sign in when needed | No sign-in + Request headers |
| Availability | All plans with custom connectors | Header auth is a beta for some organizations |
| Good for | People who each build their own sheet | One account that pulls data and shares the sheet |
| Changing the method | Delete and add again | Delete and add again |
The Free plan is a special case. It can add one custom connector, so the fetch in the chat works. But it has no Claude Sheets. Your data must go through path 2: Claude writes a CSV or xlsx file, and you open it in Excel or Google Sheets. On Team, each member still clicks Connect once after the Owner adds the connector. With Way A, each person signs in to their own EveryInfra account and pays for their own calls.
With either way, tools/list shows the same 12 tools. At 00:16 SGT we sent initialize to /mcp, and the server returned protocol version 2025-06-18. Three tools do the data work. everyinfra_list_capabilities reads the catalog.
everyinfra_call_api calls one capability. everyinfra_get_job reads the result of an async job. In MCP, a server lists tools through tools/list, and a client calls one through tools/call (MCP tools spec). Transport is Streamable HTTP (MCP transports spec).
One real round trip: the tools/call and its 200 reviews
When Claude calls a connector, it sends a JSON-RPC request to the server. At 00:17:08 SGT on 2026-11-18, we sent one in the same format to https://api.everyinfra.com/mcp. It asked for Gymshark's Trustpilot reviews from the last three months, newest first, 200 rows. Below is an excerpt. We decoded the JSON string in the response and removed reviewer names.
{"jsonrpc":"2.0","id":3,"method":"tools/call",
 "params":{"name":"everyinfra_call_api",
  "arguments":{"platform":"trustpilot","action":"reviews",
   "params":{"company":"gymshark.com","limit":200,"date":"last3months","sort":"recency"}}}}

// excerpt of result.content[0].text after decoding
{"id":"req_3cd99d6652cc4b7d","platform":"trustpilot","action":"reviews","count":200,
 "results":[{"title":"Gymshark order HELL!","rating":1,"country":"GB",
             "posted_at":"2026-11-17T12:03:33+00:00","is_verified":false,
             "experience_at":"2026-11-10T00:00:00+00:00", "...": "..."}],
 "billing":{"charged":true,"charged_usd":0.001389}}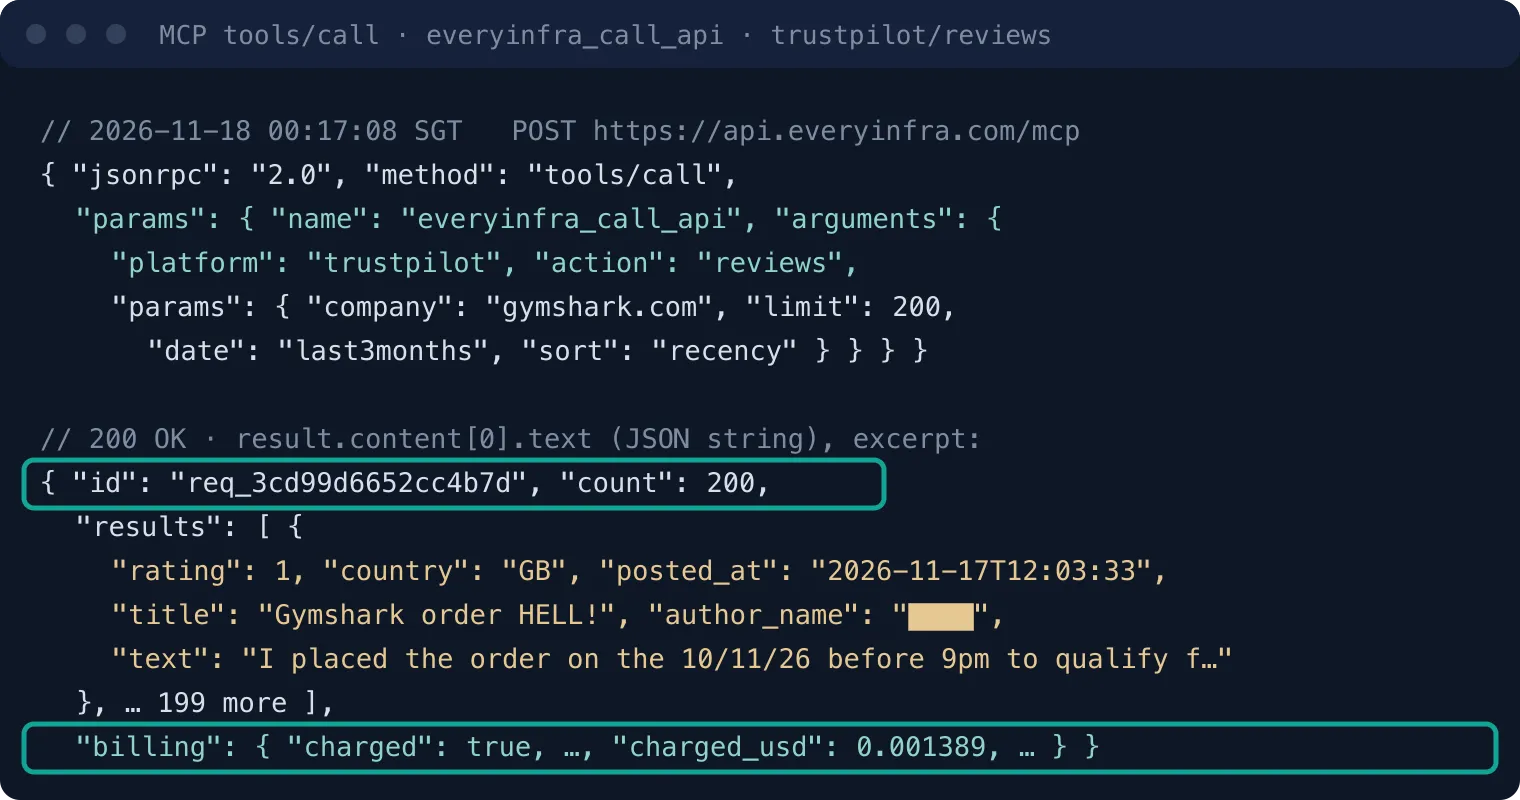
The 200 reviews cost one charge of $0.001389. That matches the price_usd of trustpilot/reviews in the catalog (EveryInfra capability catalog). Billing is per call, not per row.
This sync call took 86 seconds. The catalog notes for trustpilot/reviews give no wait limit.
Only a few capabilities, such as Taobao product details, state a sync limit of about 85 seconds. The async_hint field in this response says to add "mode":"async" for slow tasks and large limits. You then get a job_id at once and poll it. In a chat, a tool call that hangs for 86 seconds is a poor experience. For a large batch, tell Claude to submit in async mode and read the result with everyinfra_get_job.
At 00:28:28 SGT we tested that. We sent reddit/search, newest first, with mode set to async. The submit returned in 1.9 seconds with status: running and a job_id. We then called everyinfra_get_job every few seconds.
At 00:29:01 the status was finalizing. At 00:29:09 it was succeeded, with 23 rows. everyinfra_get_job is free and does not count toward the per-minute limit. No call in this flow took longer than 2 seconds.
The table lists the 5 billed calls. All times are SGT on 2026-11-18. You can recompute each number from the raw responses.
| # | Time | Endpoint | Capability | Main parameters | Rows | charged_usd |
|---|---|---|---|---|---|---|
| 1 | 00:17:08 | MCP sync | trustpilot/reviews | gymshark.com, limit 200, last 3 months, newest | 200 | $0.001389 |
| 2 | 00:18:53 | REST | reddit/search | gymshark, limit 25, relevance | 25 | $0.000792 |
| 3 | 00:19:25 | REST | web/search | gymshark reviews 2026, us, en | 10 | $0.001389 |
| - | 00:19:52 | REST | trustpilot/reviews | star filter sent as numbers | 0 (429) | $0 |
| 4 | 00:20:17 | REST | trustpilot/reviews | 1 and 2 stars only, limit 200 | 200 | $0.001389 |
| 5 | 00:28:28 | MCP async | reddit/search | gymshark, limit 25, newest | 23 | $0.000792 |
| 458 | $0.005751 |
The call at 00:19:52 hit the limit of 10 calls per minute and returned 429. The response said that nothing was charged and suggested a retry after 8 seconds. We waited 25 seconds, and the retry worked. That request also sent the star filter as numbers. The catalog says stars is an array of strings, such as ["1","2"]. We fixed that in the retry.
Test 1: 200 recent reviews, mean 4.36 stars
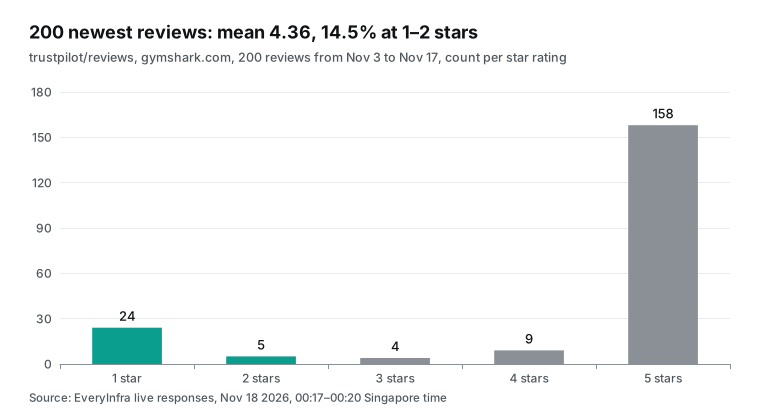
The first call returned 200 reviews posted from 2026-11-03 21:47 UTC to 11-17 12:03 UTC. That is exactly two weeks. The star mix is lopsided: 158 five-star, 9 four-star, 4 three-star, 5 two-star and 24 one-star.
The mean is 4.36, and the median is 5. One- and two-star reviews total 29, or 14.5%. Claude can compute this in the sheet with AVERAGE and COUNTIF. But the sheet must say that the 200 rows cover only two weeks.
A split by country tells you more than the overall mean. The country field is the reviewer's country. Of the 200 rows, 77 are from the UK and 40 from the US. The Netherlands has 12 and Canada 11.
The UK mean is 4.06, against 4.38 for the US. The UK has more low ratings, and its first review complains that an order had not arrived after a week. With 11 or 12 rows, a mean can swing a lot. Put the row count next to each mean.
| Country | Rows | Mean | Note |
|---|---|---|---|
| UK (GB) | 77 | 4.06 | Most low ratings in the two weeks |
| US | 40 | 4.38 | Close to the overall mean |
| Netherlands (NL) | 12 | 5.00 | Few rows, unstable mean |
| Canada (CA) | 11 | 4.45 | Few rows, unstable mean |
| All | 200 | 4.36 | 2026-11-03 to 11-17 |
Two more columns earn a place in the sheet. Only 41 rows, or 20.5%, have is_verified set to true. That does not make the other 159 rows unsolicited. The response also has a verification_level field. All 41 verified rows are invited, and 148 of the 159 unverified rows are invited too. Only 11 rows, or 5.5%, are not-verified, which means no invitation.
So 189 of the 200 reviews (94.5%) came from a company invitation. If the sheet keeps only is_verified, it counts invited but unverified reviews as unsolicited. Keep both columns and average by verification_level. The 148 invited, unverified rows average 4.59. The 41 invited, verified rows average 3.95. The 11 uninvited rows average 2.82, and 6 of them have one or two stars.
The low-star pull reverses the mix. Of its 200 rows, 79 (39.5%) are not-verified, against 5.5% in the full sample. Many unhappy customers write without an invitation. Three group means show this. One overall mean hides it.
Trustpilot has its own rules for these labels, and companies can invite and answer reviews through its business API (Trustpilot developer docs). Review length tracks the rating. The median one-star text has 258 characters, and the median five-star text has 77.5. Low ratings carry more detail, so Claude's topic tags on them are more reliable.
The response also has experience_at, the date of the purchase. It differs from the post time posted_at. In these 200 rows, the median gap from purchase to review is 0.84 days. 131 reviews came within one day, and 13 came more than 7 days later. The longest gap was about 98 days.
| Group | Rows | Median days from purchase to review |
|---|---|---|
| All reviews | 200 | 0.84 |
| One- and two-star | 29 | 1.44 |
| Five-star | 158 | 0.83 |
| Written within 1 day | 131 | - |
| Written after 7 days | 13 | - |
Low ratings often come after some days of waiting for a fix. To see which week's orders went wrong, group by experience_at. To see which week the brand's reputation dropped, group by the post time. Keep both columns, and name the column that each chart uses.
Test 2: low-star topics and a reply rate that the window skews
The fourth call asked for one- and two-star reviews only. Its 200 rows cover 2026-09-22 to 11-17, which is 56 days. There are 182 one-star and 18 two-star rows. The UK has 109 of them and the US 24.
We tagged these rows with keyword rules, and one row can get several topics. For example, "no answer" and "template reply" count as customer service, and "courier" and "tracking" count as delivery. These are our rules. Claude uses its own judgment in a sheet, so its numbers will differ.
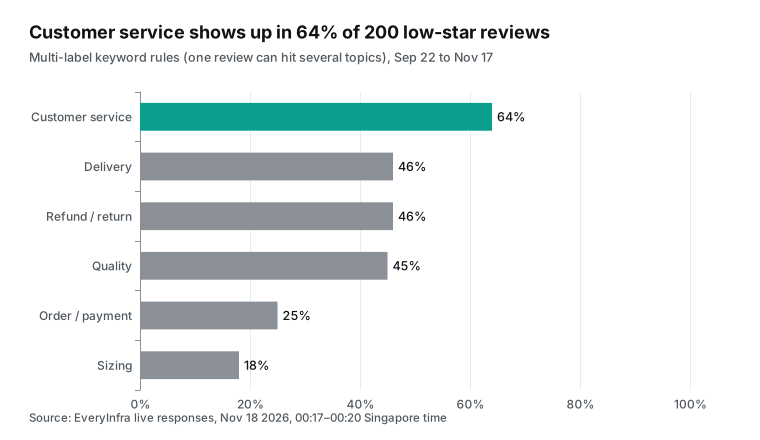
Customer service appears in 128 rows, or 64%. Delivery and refund or return appear in 92 rows each, or 46%. Quality appears in 90 rows (45%), order or payment in 50 (25%), and sizing in 36 (18%). Eight rows match no topic. A low rating rarely has only one complaint. It is usually "my order did not arrive" plus "customer service sent a template reply".
So the topic field must take more than one value per row. Use one 0/1 column per topic. A single-select dropdown loses information. Claude Sheets does not support multi-select dropdowns yet (Claude Sheets help page). So 0/1 columns are the safe choice.
The seller reply rate is easy to get wrong in a sheet. In the first call, only 12 of 24 one-star reviews had a reply. That looks like half. In the fourth call, 181 of 200 low-star reviews had a reply, which is 90.5%. Both numbers are correct. The difference comes from the age of the reviews.
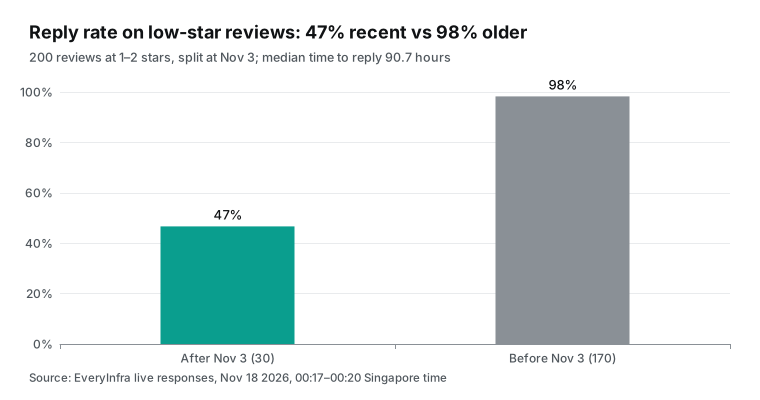
We cut at November 3, 21:47 UTC, the start of the first call's window. 14 of the 30 later low-star reviews had a reply (47%). For the 170 earlier ones, 167 had a reply (98%).
Move the cut by a few hours and the rate moves too. At midnight SGT on November 3 (16:00 UTC on November 2), 19 of 35 later reviews had a reply, 54%. At midnight UTC on November 10, 13 of 19 had a reply, 68%. One set of 200 rows gives 47%, 54% or 68%. So write the cut and the time zone next to any reply rate. The table shows the reply times for the 181 replied reviews.
| Reply time | Reviews | Share of 181 |
|---|---|---|
| Within 24 hours | 24 | 13% |
| Within 72 hours | 53 | 29% |
| Median | 90.7 hours | - |
| Slowest | 36 days | - |
So recent low ratings look ignored mostly because their turn has not come yet. A formula such as COUNTIF(reply column,"<>")/COUNTA(...) changes a lot with the fetch date. A steadier formula counts only reviews that are at least 7 days old. You can also group the rate by post week.
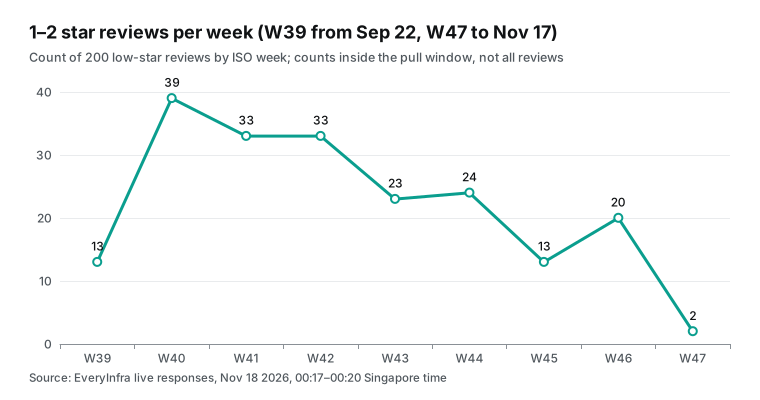
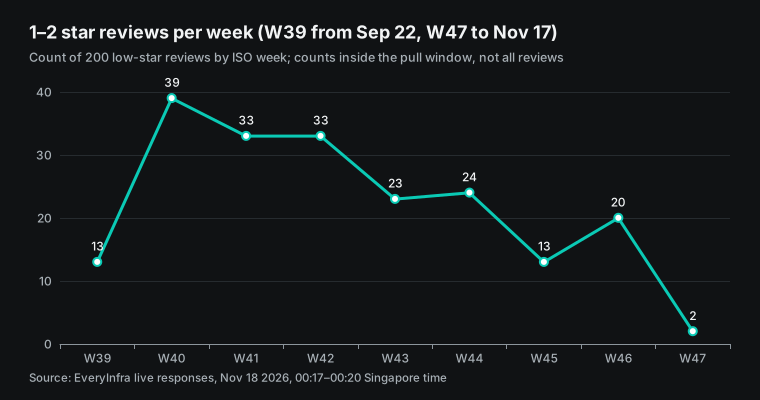
By week, W40 has the most low ratings, with 39. The count then falls to the twenties, drops to 13 in W45, and comes back to 20 in W46. Mark two cut-offs on this line.
W39 starts on September 22 only because the 200-row limit stopped there. W47 has only November 16 and 17. Flag the first and last week in the sheet. Without the flag, readers think that low ratings fell off a cliff in W47.
Test 3: clean Reddit posts and search results first
The second call searched "gymshark" by relevance. It returned 25 posts dated 2026-10-22 to 11-17. The reddit/search range is fixed to the last month, and the sort order does not change it (EveryInfra capability catalog). Nineteen of the 25 posts come from r/Gymshark.
Eleven titles mention "Black Friday", "BF" or "sale". The posts have 511 comments in total. The top post is a news post in r/unitedkingdom about a trademark dispute, with 400 upvotes. The median is only 7 upvotes.
The fifth call sorted by newest. Its 23 results come from 16 communities, and only 6 come from r/Gymshark. Only 2 overlap with the relevance results. Three of the 23 are gift card trade posts.
Their "[H]" and "[W]" marks mean "have" and "want" in trading communities. These rows spoil sentiment and topic counts. Tell Claude to filter by community and keyword before it writes the sheet. Or add a "relevant" column, and compute only on relevant rows.
The third call returned 10 web search results. The domains include Trustpilot, Reddit, a Women's Health review, TikTok, YouTube, the brand's site and Instagram. The published_at field has no single format.
Four values are empty, four are relative ("11 months ago"), and two are dates ("Jun 12, 2026"). Tell Claude to convert them to one date format. Or leave them empty. Do not sort a column that mixes three formats.
You can split these 10 results into groups. Trustpilot and Reddit point to platforms that we already fetched, so drop them. The Women's Health, thingtesting and theadultman results are third-party reviews to read in full. The TikTok, YouTube and Instagram results point to videos and posts. Mark them, and fetch their comments later with the matching capability. For example, YouTube comments cost $0.000556 per call.
| Source capability | Columns for the sheet (catalog `response_fields`) | Work before the rows go in |
|---|---|---|
trustpilot/reviews | id, rating, title, text, country, posted_at, is_verified, verification_level, reply_text, reply_at | Deduplicate by id; no reviewer names; reply rate on reviews 7+ days old |
reddit/search | id, community, title, like_count, comment_count, posted_at, url | Remove trade posts; hide communities named after a person |
web/search | rank, title, url, text, published_at | One date format; keep the top row per domain |
Our data shows why deduplication matters. The first and fourth calls both pulled Gymshark's Trustpilot reviews. All 29 low-star reviews from the first call also appear in the fourth. The two calls give 400 rows, but only 371 unique reviews. Without deduplication by id, the sheet counts some low ratings twice.
Pick fetch parameters so each row is in range
Every row depends on the fetch parameters. An accurate mean of the wrong rows is still wrong. The notes below come from the EveryInfra capability catalog (EveryInfra capability catalog).
| Capability | Parameter | What it does | Common mistake |
|---|---|---|---|
trustpilot/reviews | company | Website domain, such as gymshark.com | A free-text company name |
trustpilot/reviews | date | last7days to last12months (7 to 366 days) | A specific date (returns 422) |
trustpilot/reviews | stars | String array, such as ["1","2"] | Numbers, or a minimum rating |
trustpilot/reviews | lang | Review language, such as ["de","fr"] | Leaving it out gives English only |
reddit/search | sort | relevance, newest, popular, rising, top, controversial | Expecting it to change the one-month range |
web/search | country, language | Region and language preference | Expecting translation |
Language is the parameter that people miss most. Without lang or language, you get Trustpilot's default English reviews. So the 12 Dutch and 11 Canadian rows in our sheet are English reviews. For German or French reviews, make another call with lang. Then add a language column and keep the summaries apart.
reddit/search returns only posts that match the keyword. So you can get fewer rows than limit. We asked for 25 newest posts and got 23. A call with no results is refunded.
web/search returns 10 results at most per call. For more, page through the results, and each page is one call. The catalog notes that published_at can be missing or wrong. That matches the 4 empty and 4 relative dates we saw.
Lay out the columns of a weekly feedback sheet
The layout decides whether Claude's numbers are right later. Keep raw rows apart from computed columns. The Reviews, Reddit and Search tabs hold only fields from the API response.
Claude does not change values in those columns. Topic tags and normalized dates go to the right, with a header prefix such as "calc_". All summaries go on a Summary tab. Then a new round of tags does not touch the raw data.
On the Reviews tab, put the columns in this order: id, posted_at, country, rating, is_verified, verification_level, title, text, reply_at and reply_text. Then add six 0/1 topic columns and one "7 days old" column. On the Summary tab, group by verification_level and show the count and mean for each group. posted_at is in UTC. In SGT, add 8 hours, and reviews near midnight move to the next day. Write the time zone of the weekly summary in the header.
The text column is long. The 200 low-star texts average 474 characters, about 95,000 characters in total. That fits in cells. But if you select the whole column at once, Claude must read all of it. Groups of 50 rows are steadier.
On the Reddit tab, keep community and url. One relevance result came from a community named after a person, and that name must not go into the sheet. With url in the sheet, you can open each row that Claude marks "not relevant". On the Search tab, sort by rank. When one domain appears twice, as YouTube did, keep the higher row for the summary.
Check the topic tags against keyword rules
Topic tags come from Claude's judgment and need an outside reference. Our keyword rules matched no topic in 8 of the 200 low-star rows. We read all 8. Each one is short, 45 to 155 characters with the title.
| What the review says | Rows | Likely topic | Why the rule missed it |
|---|---|---|---|
| Order not received | 2 | Delivery | No "received" in the rule |
| Nobody answered | 3 | Customer service | No "answer" in the rule |
| "Poor service and customer experience" | 1 | Customer service | Words between "customer" and "service" |
| Seller questioned honesty | 1 | Customer service or other | No matching word |
| Only "horrible" | 1 | None | No reason given |
So most rule misses come from wording. Claude reads for meaning and can place most of these rows. The sheet must show where Claude placed each one.
A simple check uses two sets of topic columns. Claude fills one set by meaning. A formula fills the other set by keyword, with REGEXMATCH or SEARCH. A third column shows whether the sets agree. For a topic with less than 80% agreement, read 20 rows that disagree.
"Customer service" has the most matches (128), so it is the most likely to be too high. Five low-star rows contain "emailed", and the rule counts all five as customer service. But "I emailed them" says only that the person made contact. Edge cases like this need Claude's judgment. The rules give a floor that anyone can reproduce.
After the check, put the tag rules in a comment on the header. The help page says team members can comment on cells, and Claude sees those comments (Claude Sheets help page). The next person can then read how each column was decided.
Classify, average and chart in the sheet (configuration example)
The prompts below follow the uses on the Claude Sheets help page (Claude Sheets help page). You can ask Claude to build a sheet in the chat. You can also select a range and ask about it, or ask Claude to add columns and tabs. We did not run these prompts in Claude.
In the chat (EveryInfra connector on):
1. Use everyinfra_call_api for trustpilot/reviews, company=gymshark.com, limit=200,
   date=last3months, mode=async; make a second call for 1-2 stars (stars=["1","2"]).
   Use everyinfra_get_job until both jobs finish.
2. Use reddit/search for gymshark, limit=25; use web/search for "gymshark reviews 2026".
3. Create a Claude Sheet with three tabs: Reviews / Reddit / Search.
   Reviews: deduplicate by id, no reviewer names. Reddit: remove trade posts.
   Search: dates as YYYY-MM-DD; convert relative times from 2026-11-18.

In the sheet (Reviews tab selected):
4. Add 6 topic columns (customer service, delivery, refund/return, quality,
   order/payment, sizing) with 0 or 1. One row can have several 1s.
5. Add a Summary tab: rows and mean rating by country; low-star rows by post week;
   reply rate only for reviews at least 7 days old.
6. Draw three charts: star mix (bar), topic share (bar), low-star reviews per week (line).
You can let Claude write the formulas. The help page says formulas stay in the cells, so you can check each number. The mean is AVERAGE(Reviews!C:C). The mean by country can use AVERAGEIF.
Topic share is the SUM of each column divided by the low-star count. The reply rate uses COUNTIFS with a "7 days old" condition. Sheets has no pivot tables yet. So summaries by country and by week need formulas like these.
Public videos show two details. In one video, the author imported an Excel file with 120 formulas (Mervin Praison test video, 2026-11-12). All formulas came through. The chart, the dropdowns and the conditional formatting were lost.
An export back to Excel then warned about three differences. Another author showed "Import from Google Sheets" (Brock Mesarich video, 2026-11-10). With the Google Sheets connector on, the import window listed the sheets in that account. The help page mentions neither detail, and the beta can change.
Keep one sheet going: add new data each week
The ZDNET test shows how to continue a sheet: paste its link into a new chat (ZDNET review). The table shows a weekly routine.
| Step | Where | Tool or action | Cost |
|---|---|---|---|
| 1. Fetch the last 7 days of reviews | Chat | everyinfra_call_api, date=last7days, async | $0.001389 per call |
| 2. Fetch newest Reddit posts | Chat | reddit/search, sort=newest | $0.000792 per call |
| 3. Read job results | Chat | everyinfra_get_job | Free |
| 4. Paste the sheet link, add rows | Sheet | Skip rows whose id exists | Plan usage |
| 5. Refresh the Summary tab | Sheet | Formulas and charts | Plan usage |
Watch for two kinds of repeats. On Trustpilot, 200 newest reviews usually overlap with the last pull. Our two calls shared 29 rows, 14.5% of the second call. On Reddit, the overlap is larger.
Two weekly pulls share about three weeks of the one-month range. Our relevance and newest results shared only 2 posts, so newest order suits weekly updates. Add a check column with COUNTIF(id column, id)>1. A value above 1 means a duplicate got in.
Search rows are 61.4% of the cost of mix A. Web results change slowly, so a monthly search is usually enough. That cuts the cost further.
The math: API fees for a 500-row sheet
Per-call billing means the cost of a row depends on the rows per call. trustpilot/reviews returned 200 rows per call for $0.001389. reddit/search returned up to 25 rows for $0.000792. web/search returned 10 rows for $0.001389. Per 1,000 rows, that is about $0.0069 for reviews, $0.0317 for Reddit and $0.1389 for web search. A search row costs 20 times as much as a review row.
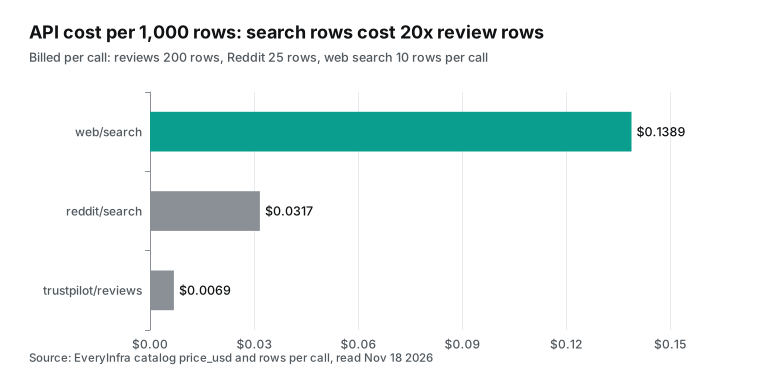
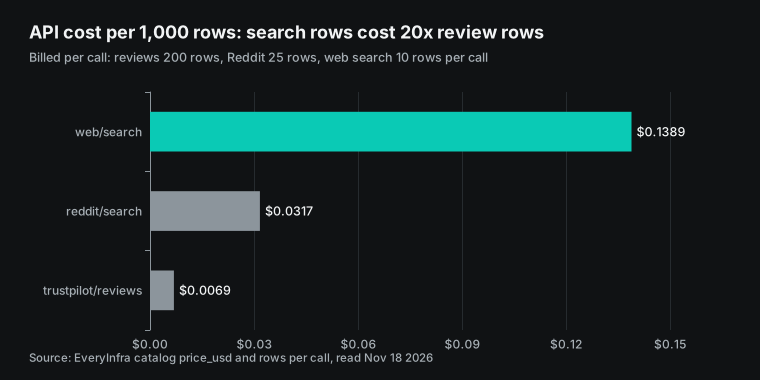
So the cost of a 500-row sheet depends on the source mix. We priced three mixes at catalog prices. The call count is rounded up from the maximum rows per call.
| Mix | Review rows | Reddit rows | Search rows | Calls | API fees | Search share of cost |
|---|---|---|---|---|---|---|
| A, mostly reviews | 400 | 50 | 50 | 9 | $0.011307 | 61.4% |
| B, even | 200 | 150 | 150 | 22 | $0.026976 | 77.2% |
| C, mostly search | 100 | 100 | 300 | 35 | $0.046227 | 90.1% |
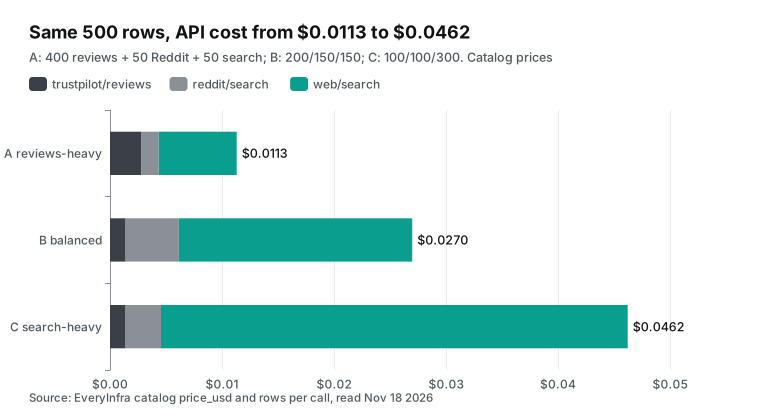
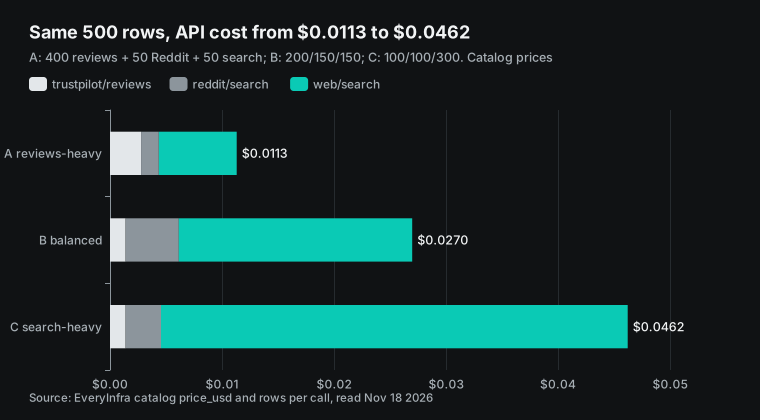
In all three mixes, search results are the largest cost. In mix C they are nine tenths. For a sheet that counts brand feedback, more review rows give more for the money. Search results help you find other reviews and threads, and 10 to 30 rows are usually enough.
| Update rate | Mix A | Mix B | Mix C |
|---|---|---|---|
| One sheet | $0.0113 | $0.0270 | $0.0462 |
| Daily for 30 days | $0.34 | $0.81 | $1.39 |
| Weekly for 52 weeks | $0.59 | $1.40 | $2.40 |
These are our API fees only. On the Claude side you pay the plan fee, and Sheets shares the usage limit with chat (usage limits).
Two free items also change the cost. First, failed calls and empty results are not charged. The 429 at 00:19:52 said that nothing was charged. The reddit/search notes say a call with no results is refunded. Second, everyinfra_list_capabilities and everyinfra_get_job are free. If Claude reads max_limit in the catalog first, it makes fewer calls than with blind retries.
Path 2: export CSV or xlsx, then import into Sheets
To keep a raw file, tell Claude to write the rows to CSV or xlsx in the chat. Then use "Import a CSV file" in Sheets. Claude can create Excel, PowerPoint, Word and PDF files with code execution. First turn on "Code execution and file creation" under Settings > Capabilities (create and edit files help page).
Sheets has four import options: a CSV file, Google Sheets, Excel, or a blank sheet. You can also paste from Excel or Google Sheets. Export gives .xlsx or CSV. "Send to" passes the sheet to Airtable, Asana, monday.com or Smartsheet (Claude Sheets help page, Anthropic launch post).
RFC 4180 describes the CSV format (RFC 4180). A field with a comma, a quote or a line break must be in double quotes. A quote inside a field is written as two quotes. Review texts have many line breaks and quotes.
The first Gymshark low rating alone has more than ten line breaks. If the CSV does not handle them, one review becomes several rows. xlsx is the Office Open XML format of ECMA-376 (ECMA-376). A line break in an xlsx cell does not break the row, so xlsx is safer for long text.
Claude Sheets, the Google Sheets connector or Claude for Excel
Anthropic now offers several routes, and each fits different data.
| Option | Where the data lives | Fetch and write in one flow? | Good for |
|---|---|---|---|
| Claude Sheets | Claude artifacts | Fetch in chat, then write | Light sheets for teams in Claude |
| Google Sheets connector (live editing beta) | Your Google Drive | EveryInfra and Google Sheets connectors in one chat | Sheets in Google, collaborators without Claude |
| Claude in Google Sheets add-on | The one open Google sheet | Sees only the current file | Formulas in an existing sheet |
| Claude for Excel | Excel files | Claude inside Excel | Pivot tables, macros, Power Query |
The Google Workspace connectors help page says Claude can edit Google Docs, Sheets and Slides live next to the chat. You turn on each connector in the chat's Connectors menu (Google Workspace connectors help page). The add-on works differently. Google limits it to the open file, unless you also connect a Google Drive MCP (Claude in Google Docs, Sheets and Slides).
For public data, the Google Sheets connector is the closest to a sheet that takes data directly. In one chat, the EveryInfra connector fetches and the Google Sheets connector writes. The sheet stays in Google Drive. Collaborators open it with a Google account.
The AI Advantage review makes a point about sharing (The AI Advantage video, 2026-11-13). Everyone has a Google account. To share a Claude sheet, you invite people into Claude or make a public link.
The ZDNET author sees it the other way. A native sheet in Claude removes the work of moving data between tools (ZDNET review). One set of data can then feed a sheet, a whiteboard and a deck. Pick the route that fits where your collaborators work.
Limits and cautions
First, approvals. Each call to a custom connector can ask for approval. On GitHub, a Team plan user reported this in Cowork for a custom remote MCP connector (claude-ai-mcp issue #491). The prompt came on every call, and "allow for this task" was gray. Mix C takes 35 calls, and 35 approvals is not practical. Set the two free tools to always allow, and keep approval on everyinfra_call_api.
For large batches, you can also use the MCP connector in the Claude API. It connects the Messages API to a remote MCP server. For now it supports tool calls only and needs a beta header (MCP connector docs). Teams that work in a terminal can add EveryInfra to Claude Code as an HTTP server (Claude Code MCP docs). They then import the output file into Sheets.
Second, data controls in the beta. The help page says Sheets has no HIPAA or ZDR support yet. On Enterprise, Sheets is off until an admin turns it on.
Admins can limit it to some groups with custom roles (artifacts admin guide). Public reviews contain names and personal stories. Leave reviewer names out of the sheet. Check each person's access level before you share it (sharing artifacts help page).
Third, what you can fetch. The catalog notes for amazon/reviews say that US reviews need a login and are not available now. Other Amazon sites usually show about a dozen featured reviews per product.
That is why we used Trustpilot for shop reviews. reddit/search covers only the last month. web/search returns 10 results per call. Also read each platform's data terms, such as the Reddit Data API Terms (Reddit Data API Terms).
Fourth, call rate. Our test key allows 10 calls per minute. Above that it returns 429, does not charge, and gives a wait time in seconds.
Mix C needs at least 4 minutes at this rate. Put a rule in your prompt: "no more than 8 calls per minute; on 429, wait and retry". In async mode, everyinfra_get_job does not count toward the limit. So a batch submit with a later read is less likely to hit the limit.
Fifth, check Claude's tags and numbers. The help page says each change is outlined and formulas stay in cells (Claude Sheets help page). Version history lets you go back. After Claude tags the topics, read 20 random rows yourself. If they differ from the keyword rules a lot, tell Claude to tag again.
Industry updates
- 2026-11-10: Claude Sheets and Whiteboards enter beta, and Dashboards becomes Claude Data (Anthropic launch post). For readers: sheets now live in Claude, but the fetch still happens in the chat.
- 2026-11-10: interactive connectors open full screen next to the chat, built on the MCP Apps extension (Anthropic article, MCP Apps overview). For readers: a data service built as an MCP App could show a live result table.
- 2026-11-16: the Claude Sheets help page now says at least 200,000 filled cells. A November 11 reading said 100,000 (Claude Sheets help page). For readers: read the page on the day you plan.
- 2026-10-28: Fill with Gemini in Google Sheets adds a web source to each cell and handles 3,000 cells per request (Google Workspace Updates). For readers: a
urlcolumn does the same job for API rows. - 2026-10-16: ChatGPT Slides ships in Spaces, as MIXED reports from an OpenAI release note (MIXED report). For readers: AI products keep documents in their own workspace, so data import is a shared problem.
- 2026-10-08: Claude Dashboards enters beta with links to BigQuery, Snowflake and other platforms (Anthropic launch post). For readers: scheduled dashboards go to Claude Data, and one-off tagging goes to Sheets.
FAQ
Can Claude Sheets refresh data through an MCP connector?
No. The help page says a sheet cannot pull live data from connected apps. Fetch the data in a chat with the connector on. Then tell Claude to build a sheet or add a tab. For scheduled refresh, use Claude Data. Based on the Claude Sheets help page.
How do I add a claude sheets connector?
Claude has no connector made only for Sheets. Add a custom connector for the chat under Customize > Connectors > + Add > Add custom connector. Enter https://api.everyinfra.com/mcp/all and choose Sign in when needed. Or enter /mcp with your key in a request header. Based on the custom connectors help page and add a connector that isn't in the directory.
Why switch from Google Sheets to Claude Sheets?
Someone asked this in the launch thread on Reddit r/claude, and Anthropic did not answer there (r/claude thread). From the help page, Claude Sheets fits light sheets for teams in Claude. If the sheet is already in Google, or collaborators have no Claude account, use the Google Sheets connector.
Is claude google sheets mcp the same as Claude Sheets?
No. The first is the Google Workspace Sheets connector, which edits a sheet in your Google Drive. The second is Claude's own spreadsheet. Both can share one chat with the EveryInfra connector. Based on the Google Workspace connectors help page.
How much does a 500-row sheet cost?
At catalog prices, our API fees are about $0.0113 for mostly reviews, $0.0270 for an even mix and $0.0462 for mostly search. On the Claude side, Pro costs $20 on monthly billing. Based on the 5 calls in this article and the Claude pricing page.
Can Claude Sheets export to Excel, and what is lost on import?
It exports .xlsx and CSV, and PDF export is not available yet. In a public video, an Excel import kept the formulas but lost the chart, dropdowns and conditional formatting. Based on the Claude Sheets help page and the Mervin Praison test video.
Get started: public data in one sheet in three steps
- Get an API key from the EveryInfra quickstart, or sign in through
/mcp/all. Prices are on the pricing page. - Add the custom connector in Claude, and turn it on from the "+" menu in a chat.
- Fetch Trustpilot reviews, Reddit search and web search, then build a Claude sheet.
The same connector works with other Claude features. For competitor data in meetings, see the Claude Meetings article. For speaker research before an event, see the RainFocus connector article. To sort product reviews with Claude and export a table, see the Yandex Market review article. Platform overviews: Trustpilot scraper API, Reddit scraper API and web search API.
References
- Get started with Claude Sheets, Anthropic Help Center, updated 2026-11-16, read 2026-11-18, https://support.claude.com/en/articles/18324300-get-started-with-claude-sheets
- Claude Whiteboards, Claude Sheets, and Claude Data, Anthropic, 2026-11-10, https://claude.com/resources/articles/sheets-whiteboards-data
- Working with Claude Sheets, Whiteboards, and Interactive Connectors, Anthropic, 2026-11-10, https://claude.com/resources/articles/more-ways-to-work-with-claude-sheets-whiteboards-and-interactive-connectors
- Open your apps in Claude and work in them together, Anthropic, 2026-11-10, https://claude.com/resources/articles/interactive-connectors-full-tool
- Claude post on X, 2026-11-10, https://x.com/claudeai/status/2120206365759094857
- Plans & pricing, Anthropic, read 2026-11-18, https://claude.com/pricing
- Use connectors to extend Claude's capabilities, Anthropic Help Center, updated 2026-11-06, https://support.claude.com/en/articles/11176164-use-connectors-to-extend-claude-s-capabilities
- Get started with custom connectors using remote MCP, Anthropic Help Center, updated 2026-11-13, https://support.claude.com/en/articles/11175166-get-started-with-custom-connectors-using-remote-mcp
- Add a connector that isn't in the directory, Claude docs, read 2026-11-18, https://claude.com/docs/connectors/custom/add-unlisted
- Authentication for connectors, Claude docs, read 2026-11-18, https://claude.com/docs/connectors/building/authentication
- Connectors overview, Claude docs, read 2026-11-18, https://claude.com/docs/connectors/overview
- How Claude suggests connected apps, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/14730684-how-claude-suggests-connected-apps
- Use Google Workspace connectors, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/10166901-use-google-workspace-connectors
- Use Claude in Google Docs, Sheets, and Slides, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/16951679-use-claude-in-google-docs-sheets-and-slides
- Create and edit files with Claude, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/12111783-create-and-edit-files-with-claude
- How do usage and length limits work, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/11647753-how-do-usage-and-length-limits-work
- Get started with Claude Whiteboards, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/18324319-get-started-with-claude-whiteboards
- Get started with Claude Data, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/17454700-get-started-with-claude-data
- Sharing artifacts, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/9547008
- Artifacts admin guide for Team and Enterprise plans, Anthropic Help Center, read 2026-11-18, https://support.claude.com/en/articles/16994751
- Build live dashboards and animate explainers with Claude, Anthropic, 2026-10-08, https://claude.com/resources/articles/dashboards-and-motion
- MCP connector, Claude Platform docs, read 2026-11-18, https://platform.claude.com/docs/en/agents-and-tools/mcp-connector
- IP addresses, Claude Platform docs, read 2026-11-18, https://platform.claude.com/docs/en/api/ip-addresses
- Connect Claude Code to tools via MCP, Claude Code docs, read 2026-11-18, https://code.claude.com/docs/en/mcp
- Release notes (Claude apps), Anthropic, read 2026-11-18, https://docs.anthropic.com/en/release-notes/claude-apps
- Tools (MCP specification 2025-06-18), Model Context Protocol, https://modelcontextprotocol.io/specification/2025-06-18/server/tools
- Transports (MCP specification 2025-06-18), Model Context Protocol, https://modelcontextprotocol.io/specification/2025-06-18/basic/transports
- Authorization (MCP specification 2025-11-25), Model Context Protocol, https://modelcontextprotocol.io/specification/2025-11-25/basic/authorization
- MCP Apps overview, Model Context Protocol, read 2026-11-18, https://modelcontextprotocol.io/extensions/apps/overview
- RFC 9728: OAuth 2.0 Protected Resource Metadata, IETF, https://datatracker.ietf.org/doc/html/rfc9728
- RFC 4180: Common Format and MIME Type for CSV Files, IETF, https://datatracker.ietf.org/doc/html/rfc4180
- ECMA-376 Office Open XML File Formats, Ecma International, https://ecma-international.org/publications-and-standards/standards/ecma-376/
- Custom remote MCP connector prompts on every tool call (issue #491), GitHub anthropics/claude-ai-mcp, read 2026-11-18, https://github.com/anthropics/claude-ai-mcp/issues/491
- Model Context Protocol specification repository, GitHub, https://github.com/modelcontextprotocol/modelcontextprotocol
- EveryInfra capability catalog, EveryInfra, read 2026-11-18 00:14 SGT, https://api.everyinfra.com/api/v1/social/catalog
- EveryInfra /mcp/all protected resource metadata, EveryInfra, read 2026-11-18 00:19 SGT, https://api.everyinfra.com/.well-known/oauth-protected-resource/mcp/all
- EveryInfra remote MCP endpoint, EveryInfra, called 2026-11-18 00:16 SGT, https://api.everyinfra.com/mcp
- Files you can store in Google Drive, Google Help Center, read 2026-11-18, https://support.google.com/docs/answer/37603
- Excel specifications and limits, Microsoft Support, read 2026-11-18, https://support.microsoft.com/en-us/office/excel-specifications-and-limits-1672b34d-7043-467e-8e27-269d656771c3
- Fill with Gemini now provides cell-level citations for web sources, Google Workspace Updates, 2026-10-28, https://workspaceupdates.googleblog.com/2026/10/fill-with-gemini-now-provides-cell-level-citations-for-web-sources-and-supports-larger-requests.html
- Trustpilot API documentation, Trustpilot, read 2026-11-18, https://developers.trustpilot.com/
- Data API Terms, Reddit, read 2026-11-18, https://redditinc.com/policies/data-api-terms
- Claude's New Whiteboards, Sheets & Data, The AI Advantage (YouTube), 2026-11-13, https://www.youtube.com/watch?v=SDipcfxxa8s
- Anthropic Just Dropped Claude Whiteboard, Sheets and Data, Brock Mesarich (YouTube), 2026-11-10, https://www.youtube.com/watch?v=7LLCexpekZI
- Claude Sheets Just Took On Excel. I REALLY Tested It, Mervin Praison (YouTube), 2026-11-12, https://www.youtube.com/watch?v=rTCQKw3NjFI
- Introducing Claude Whiteboards, Sheets, and Data, Claude (YouTube), 2026-11-10, https://www.youtube.com/watch?v=YewAJPawE7I
- 4 ways Anthropic's new Claude Sheets beat using a Google Sheets connector, ZDNET, 2026-11-16, https://www.zdnet.com/innovation/claude-sheets-review-ai-spreadsheet-tool/
- Anthropic Takes On Google And Microsoft With Claude Sheets, Engadget, 2026-11-10, https://www.engadget.com/2312177/anthropic-takes-on-google-and-microsoft-with-claude-sheets/
- Anthropic launches Claude Meetings, TechCrunch, 2026-11-10, https://techcrunch.com/2026/11/10/anthropic-launches-claude-meetings-to-turn-workplace-discussions-into-plans-and-tasks/
- Anthropic Launches Claude Whiteboards and Sheets in Beta, Unite.AI, 2026-11-10, https://www.unite.ai/anthropic-launches-claude-whiteboards-and-sheets-in-beta/
- Introducing Claude Whiteboards, Claude Sheets, and Claude Data (discussion thread), Reddit r/claude, read 2026-11-18, https://www.reddit.com/r/claude/comments/1xsv0tu/introducing_claude_whiteboards_claude_sheets_and/
- ChatGPT Slides has shipped, MIXED, 2026-10, https://mixed-news.com/en/chatgpt-slides-launch-windows-10-powerpoint-mxc-component/
- Claude Sheets and Whiteboards: How To Start, Fynl, 2026-11-11, https://fynl.io/guides/claude-sheets-whiteboards
Reference BL-178