ChatGPT Scheduled Tasks + MCP: A Weekly Demand Radar
A ChatGPT scheduled task design that reads Reddit and Quora each Monday through the EveryInfra MCP server. Measured API cost: $0.007226 a week. The first data call in each chat needs one approval.
Yes, you can build it, and the data is cheap: one weekly "demand radar" costs $0.007226 in EveryInfra API fees, or about $0.38 for 52 weeks. What you need to plan for is not money but approval. On October 26, 2026, at 17:23 Singapore time (SGT), we read the tool list of the EveryInfra remote MCP server.
Of 25 tools, the two that fetch data, everyinfra_call_api and everyinfra_search, carry readOnlyHint=false and destructiveHint=true, because each call spends money. OpenAI's developer guide Add custom MCP server says that ChatGPT supports both read and write tools. A tool without readOnlyHint counts as a write action, and write actions need approval by default. So the first call in each chat shows a prompt: select allow, and you can choose to remember it for that chat. The scheduled tasks article says that a task pauses when an action needs approval.
At the screen, that is one more click. To run the job unattended, either open approvals for this app in a Business or Enterprise workspace, or split the work in two. Another scheduler fetches the data. ChatGPT only reads it and writes the report.
In this article, a "demand radar" is a short report that runs every Monday morning. It uses fixed keywords and fixed communities. It looks at Reddit and Quora for the week's complaints and questions. It picks the 5 strongest posts of each type, with links and a one-line summary.
It helps product managers, SaaS marketers, and content planners answer one question. The question is "what did users talk about this week?" and nothing more. It does not forecast sales, and it does not decide who is right.


The part that people miss is the permission gate. A ChatGPT scheduled task is not a fixed script. At the set time, the model reads your instructions again and calls tools by itself. Before each tool call, ChatGPT checks the tool's annotations and your permission setting.
Then it calls the tool or asks you first. Per OpenAI's developer guide, a tool that is not marked read-only gets the prompt the first time it is called in each chat, and one click on allow lets it through. When you sit at the screen, "ask you" is one more click. At 9:00 on a Monday with nobody watching, "ask you" means the task stops. Each section below answers one question: on which plan and with which setting does this gate need a person, and how do you keep it from stopping a scheduled task?
The short answer: how far chatgpt scheduled tasks get on each plan
The table below collects the limits from OpenAI's documentation that matter for this job. Each cell comes from the OpenAI help center as we read it on October 26, 2026. We have no ChatGPT account for this test, so the table shows what the documents say. It does not show what we ran.
| Plan | Active scheduled tasks | Fastest repeat | Custom MCP | Data tool (not read-only) in a scheduled task |
|---|---|---|---|---|
| Free, Go | 3 | Once a day, in windows such as morning or night | Not listed in the help center; one forum user says Free still needs developer mode | Not documented; do not depend on it |
| Plus | 5 | Hourly, at exact times | Not listed in the help center | Not documented; do not depend on it |
| Pro ($100 / $200 / $500) | 15 | Hourly, at exact times | Yes; the help center FAQ says read and fetch permissions only | The developer guide supports read and write tools, with approval for writes; a pending approval pauses the task |
| Business | 10 | Hourly, at exact times | Admins and owners only | Available; may need approval, and approval pauses the task |
| Enterprise, Edu | Enterprise 15, Edu 10 | Hourly, at exact times | Admins can grant "Create plugins with MCPs" by role | Same, plus per-action control |
The task limits, the repeat rules, and the Free windows come from the "Review scheduled task limits" section of Scheduled tasks in ChatGPT. The custom MCP scope comes from the FAQ of Connecting custom MCP servers in ChatGPT. Pro prices come from About ChatGPT Pro tiers. Plus costs $20 a month, per What is ChatGPT Plus?.
The help center does not say whether Free accounts can add custom MCP servers. One forum reply on October 7, 2026 says Free users must still turn on developer mode under "Security and login" in settings. That is a user report, so we mark it "not confirmed."
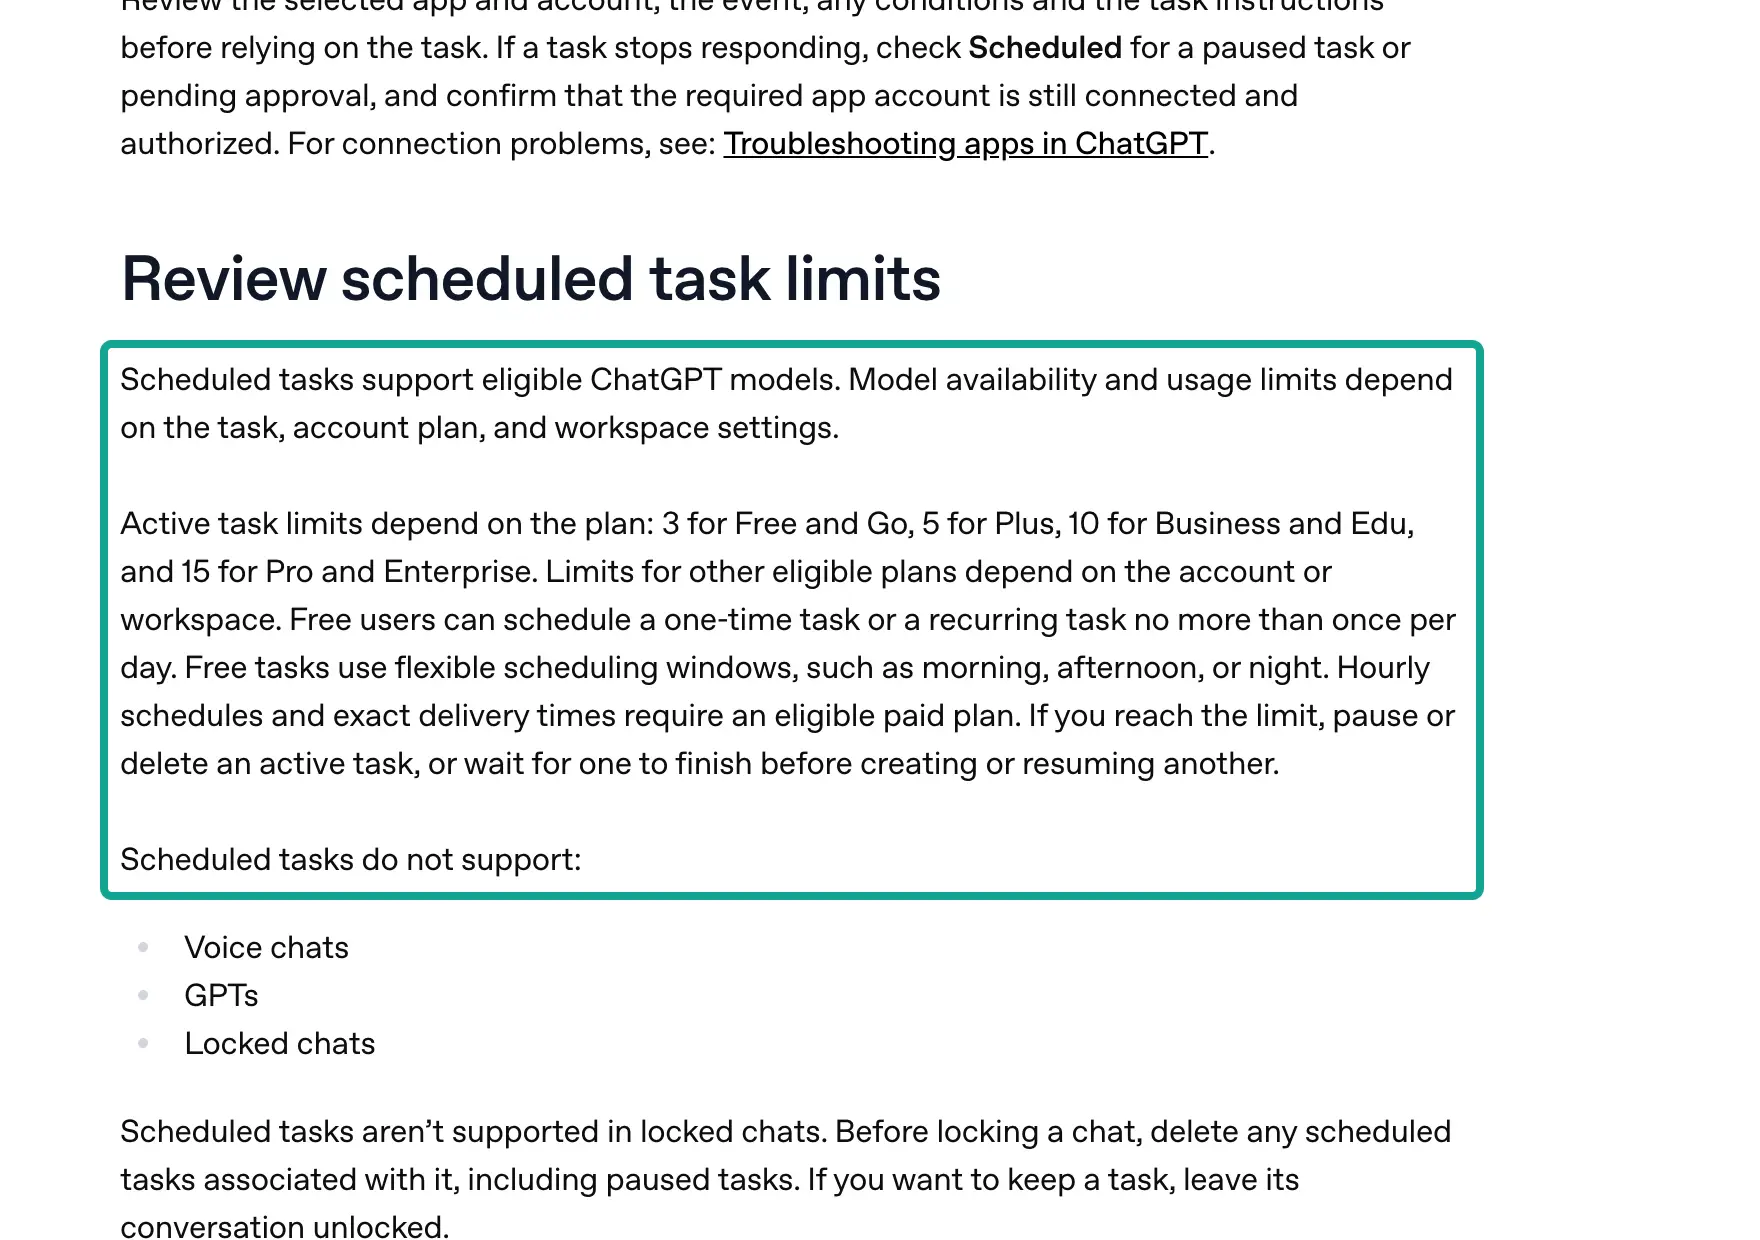
Two decisions follow from this table. First, on Plus or Pro, the easy path is not "ChatGPT calls our data tool." The easy path is the split design in the "Three designs" section. In a Business or Enterprise workspace where the admin is willing to allow this app's actions, a direct MCP connection is the shortest path. Second, a weekly radar never hits the repeat limit on any paid plan. The number to watch is active tasks. Plus has 5 slots, so one task per product category fills the plan at 5 categories.
One run, six stops
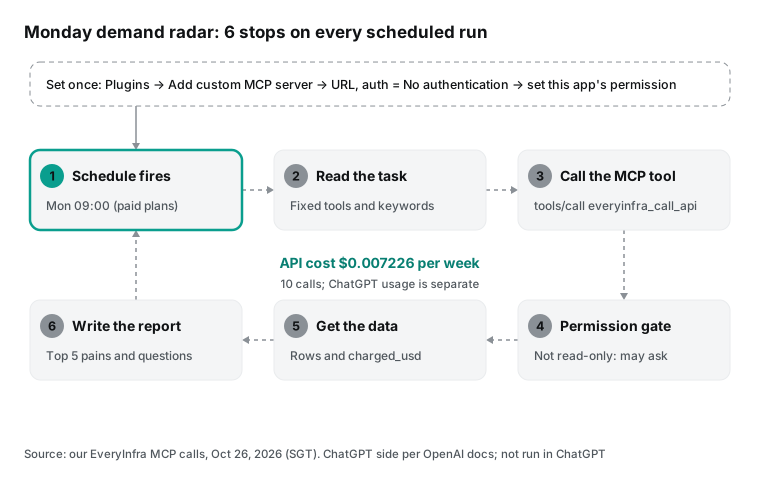
Stops 1 and 6 belong to ChatGPT. Stops 3 and 5 belong to EveryInfra. Stops 2 and 4 decide whether the job runs the same way every week. Stop 2 needs fixed values. Each run, the model reads your instructions again. If the instructions leave room for choice, the model can pick other keywords, sort orders, or limits each week.
Then the cost and the results change too. OpenAI's developer page on scheduled tasks gives the same advice. It says to name the skill or tool in the task prompt when the workflow should not rely on automatic tool choice. It also says to test the prompt in a normal chat before you schedule it. Stop 4 gets its own section below.
Step 1: add a chatgpt custom mcp connector (no developer mode now)
On October 1, 2026, the OpenAI lead of the plugins platform posted on the official forum. Custom MCP servers no longer need developer mode. All eligible users can open the Plugins page, select "+", and then select "Add custom MCP server" from the menu. The workspace permission once named "Developer mode" got a new name. The help center now calls it "Create plugins with MCPs." The developer page Connect and test your plugin lists the steps. Enter a name and a description. Under Connection, enter the public HTTPS URL with the /mcp path.
Configure authentication. Accept the risk warning. Select "Create as a plugin." Then review the tools that ChatGPT finds.
Think about authentication first. The authentication chapter asks MCP servers that need accounts to use OAuth 2.1 and to publish metadata at /.well-known/oauth-protected-resource. A third-party guide, AnythingMCP's ChatGPT page, records three choices in the form. They are "OAuth," "No authentication," and "OAuth or no authentication" in that order. It shows no field for an API key header. At 17:42 SGT we sent one GET to each discovery path on api.everyinfra.com:
| Discovery path | Status | What it means for ChatGPT |
|---|---|---|
/.well-known/oauth-protected-resource | 404 | OAuth finds no metadata |
/.well-known/oauth-protected-resource/mcp | 404 | Same |
/.well-known/oauth-authorization-server | 404 | Same |
POST /mcp with User-Agent curl/8.5.0 | 200, 0.119 s | We do not block ChatGPT's check request |
So in ChatGPT you choose "No authentication" and put the key in the URL: https://api.everyinfra.com/mcp?key=YOUR_KEY. We did not click through this in ChatGPT. Two facts support it. When we called our MCP server with no key at 17:30 SGT, the server's own error named two ways to send the key. The text was "header Authorization: Bearer or ?key= query param." The EveryInfra gateway also accepts both forms for MCP.
We tested the last row on purpose. On September 3, 2026, a developer reported on the official forum that ChatGPT's check request used the User-Agent curl/8.5.0. His firewall blocked it as a script, and ChatGPT showed only "does not implement OAuth." We sent our initialize call with the same User-Agent and got 200.
A key in a URL has a cost. RFC 6750, section 2.3 says that URLs with tokens are likely to go into logs. It says not to use this method unless the header cannot carry the token. Section 5.3 also says not to pass bearer tokens in page URLs. ChatGPT stores the URL, and workspace members who can see the app settings can see it too.
Our advice is a separate key for ChatGPT with three limits. Allow only reddit/* and quora/* capabilities (scope_mode=selected). Set a USD spend limit (spend_limit_usd, live since October 26, 2026). When the key reaches the limit, the API returns 403 key_spend_limit_reached and charges nothing. Then set an expiry date.
All three fields are in our OpenAPI document. With this article's recipe, a year of API fees is less than $0.40. A $2 limit covers a year with room to spare, and it caps the loss if the URL leaks.
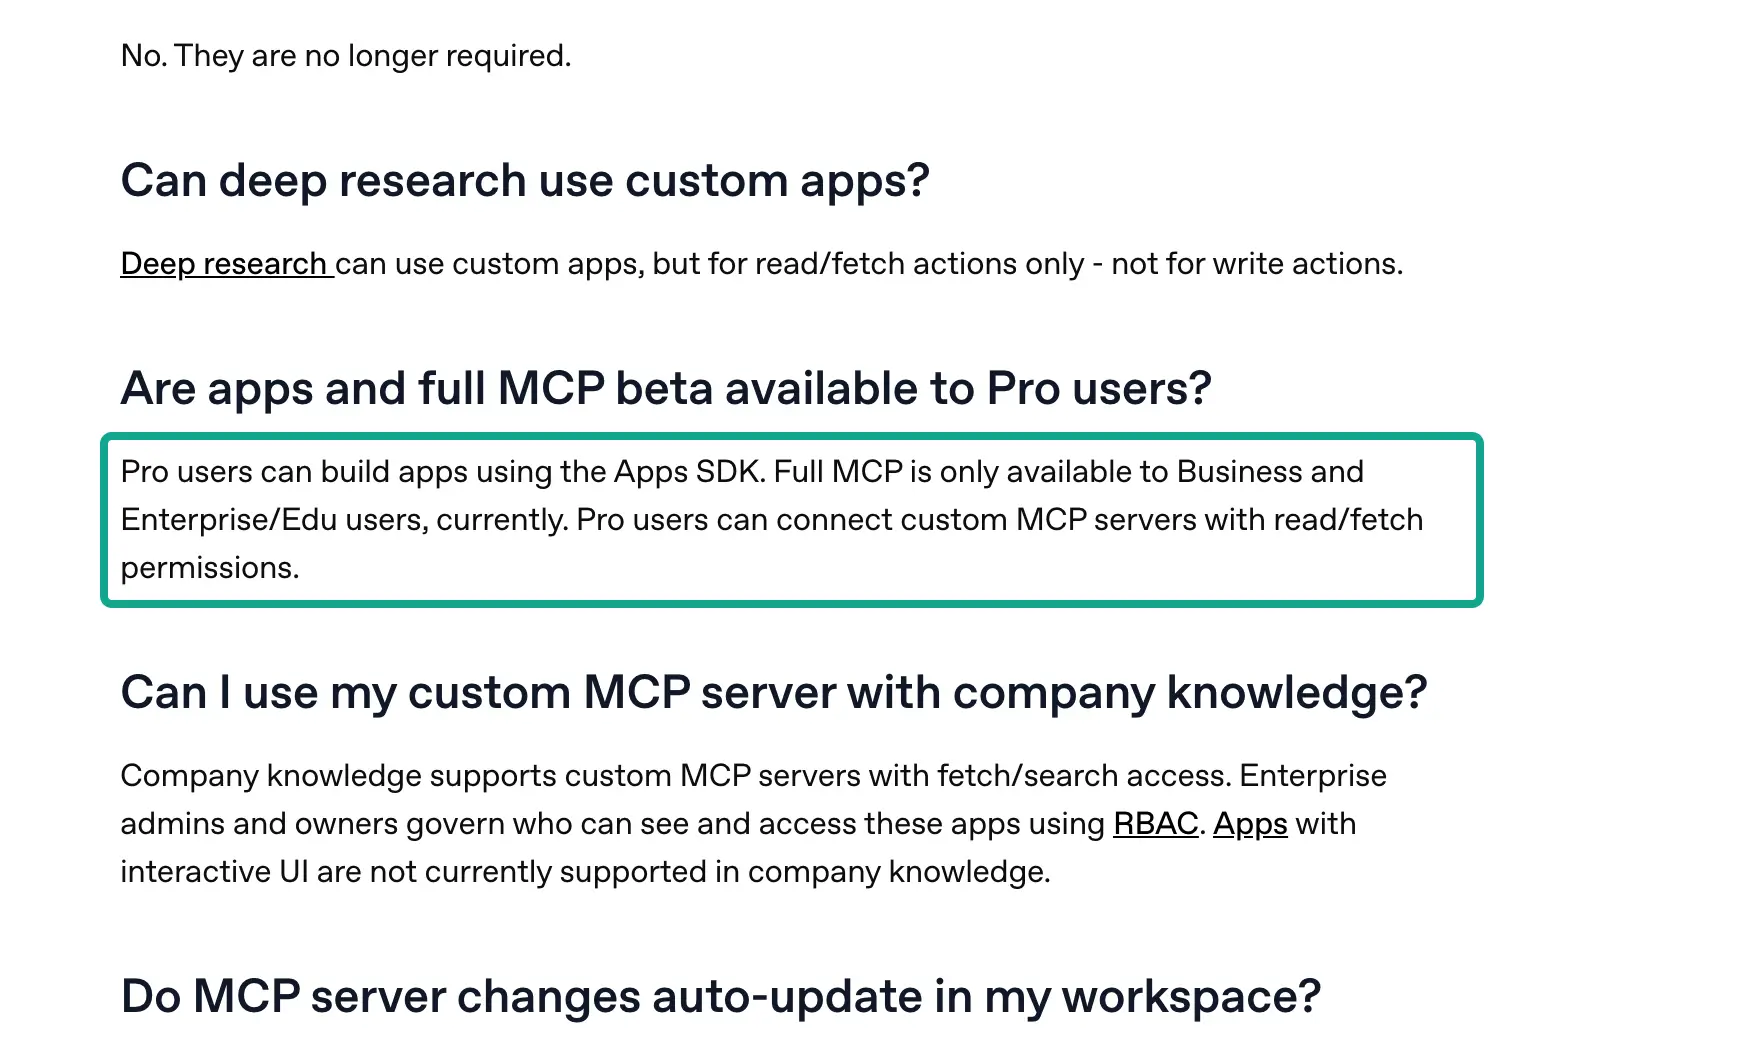
That sentence does not match OpenAI's developer guide. Add custom MCP server opens with "ChatGPT supports both read and write tools from your server." Its section "Reviewing and confirming tool calls" says that ChatGPT uses readOnlyHint to find read-only tools, and tools without it count as write actions. Write actions need approval by default. You can remember the approval for a tool for one chat; a new chat or a refresh asks again.
By that rule, our data tool works in ChatGPT: the first call in each chat shows a prompt, and you select allow. It is not blocked. We did not test this on a Pro account. If you see a different result on Pro, trust what you see.
One real round trip: what ChatGPT sends and what we return
When ChatGPT calls a tool on a custom MCP server, it sends one JSON-RPC tools/call request. At 17:34:47 SGT we sent the same request with curl. The only change: the key went in the Authorization header.
curl -s https://api.everyinfra.com/mcp \
  -H "Authorization: Bearer $EVERYINFRA_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Accept: application/json, text/event-stream" \
  -d '{"jsonrpc":"2.0","id":4,"method":"tools/call",
       "params":{"name":"everyinfra_call_api",
                 "arguments":{"platform":"reddit","action":"search",
                              "params":{"keyword":"robot vacuum keeps getting stuck","sort":"top","limit":10}}}}'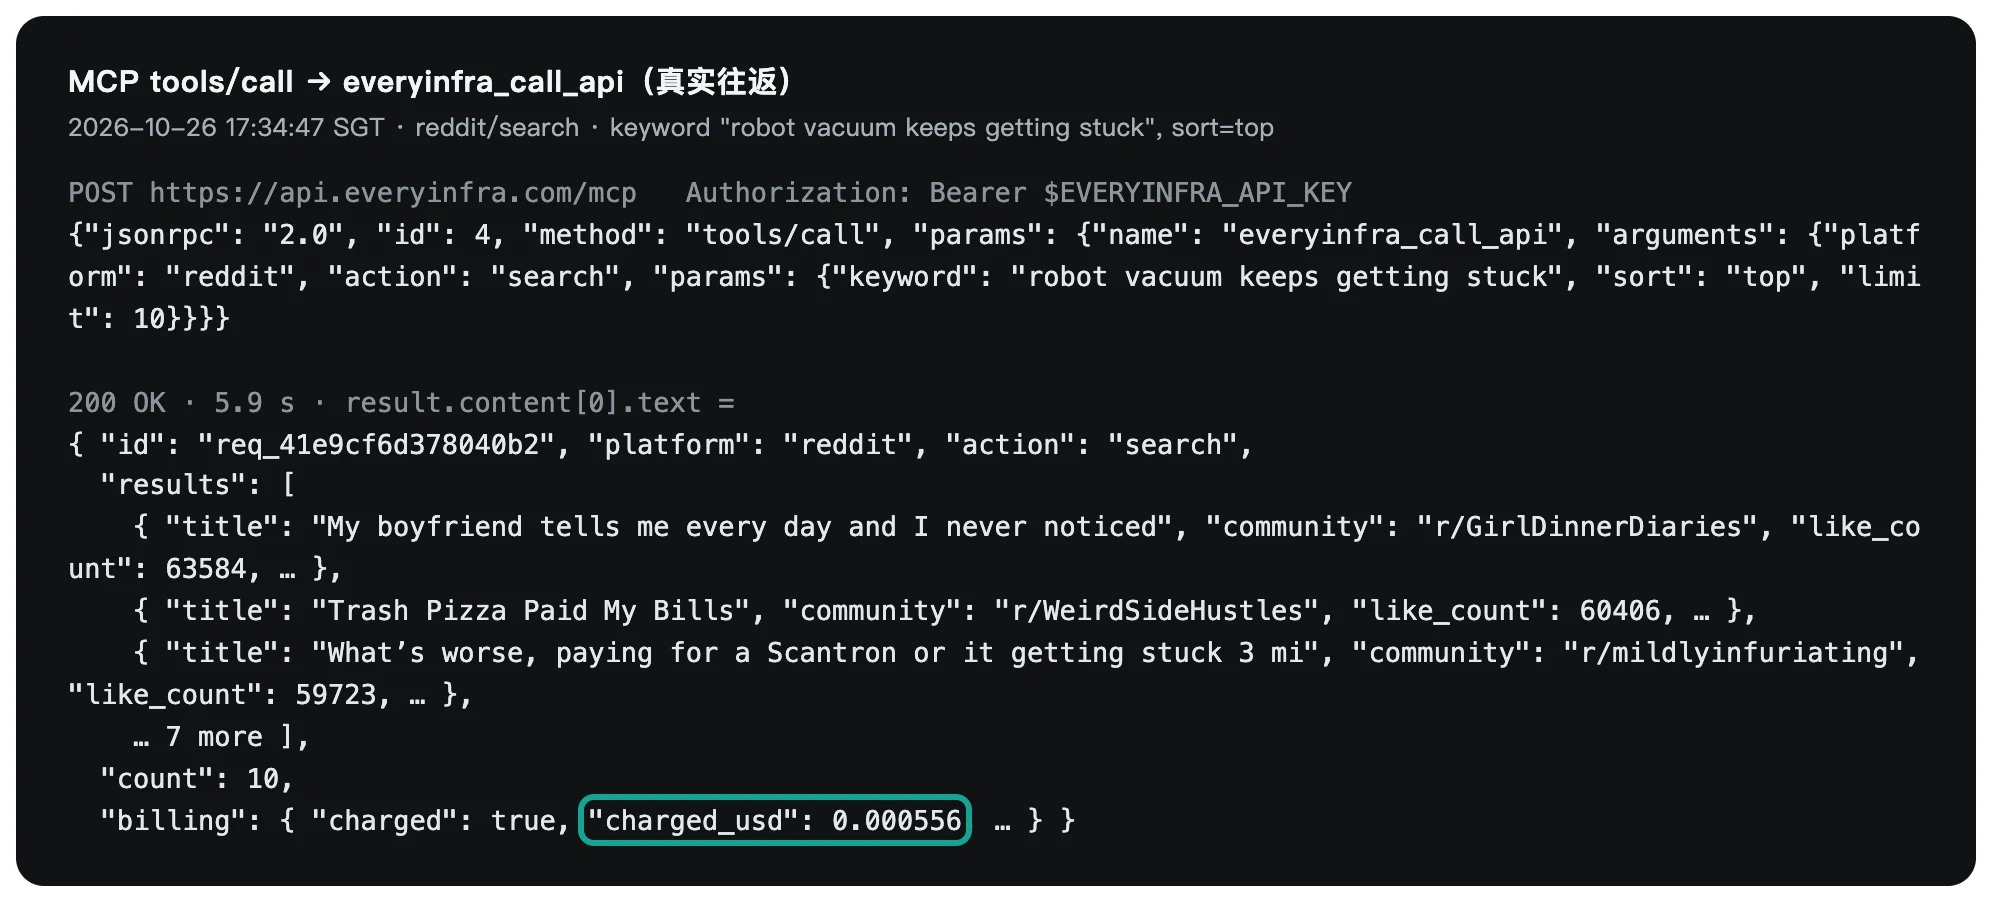
The call took 5.9 seconds, returned 10 rows, and cost $0.000556. That equals the price_usd of reddit/search in the catalog. The 10 fields in the rows (id, url, title, text, author_username, community, like_count, comment_count, posted_at, platform) are all in the catalog's response_fields. No field is outside the catalog. But none of the 10 results mentions "vacuum." The first one is a dating post with 63,584 points.
The catalog explains why. The time window of reddit/search is fixed at the last month, and sort=top sorts by score. A five-word phrase matches a post when any one word matches. The result is the month's highest-scoring posts on all of Reddit that happen to contain "stuck" or "getting."
At 17:35:11 SGT we sent the same phrase with sort=relevance. All 10 results mentioned "vacuum," and 2 contained all five words. So the API worked. The parameter that the model chose was the problem.
In a chat, you see a bad result and change it. In a scheduled task, nobody looks, and the model can pay for the wrong posts every week. So stop 2 must fix sort and use keyword phrases of 2 to 3 words. It must also ask the report to list rows returned and rows that match for each call. One look tells you if the week's data went wrong.
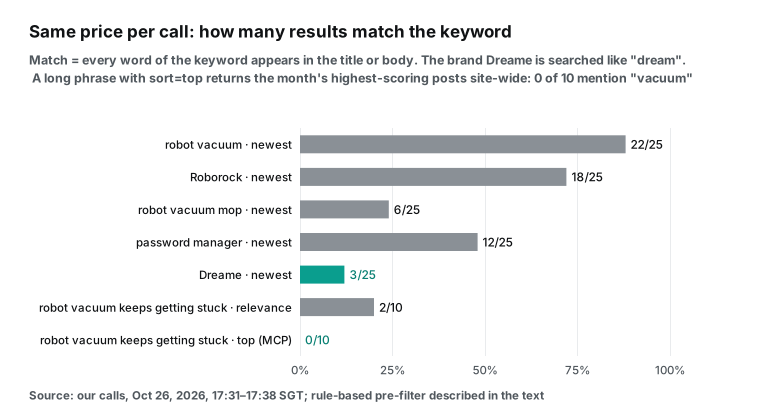
The other teal bar is Dreame, a robot vacuum brand. At 17:31:36 SGT, only 3 of its 25 results were about Dreame. The others were dream posts from r/Dreams and fiction ads, because the search treated "Dreame" like the word dream. Roborock, a name that does not look like a common word, did much better: 18 of 25. If your brand name looks like a common English word, keyword search fills with noise. Use the brand's own community with reddit/subreddit_posts (Dreame has r/Dreame_Tech), or add a category word to the keyword.
Why the data tools ask for approval: the annotations of 25 tools
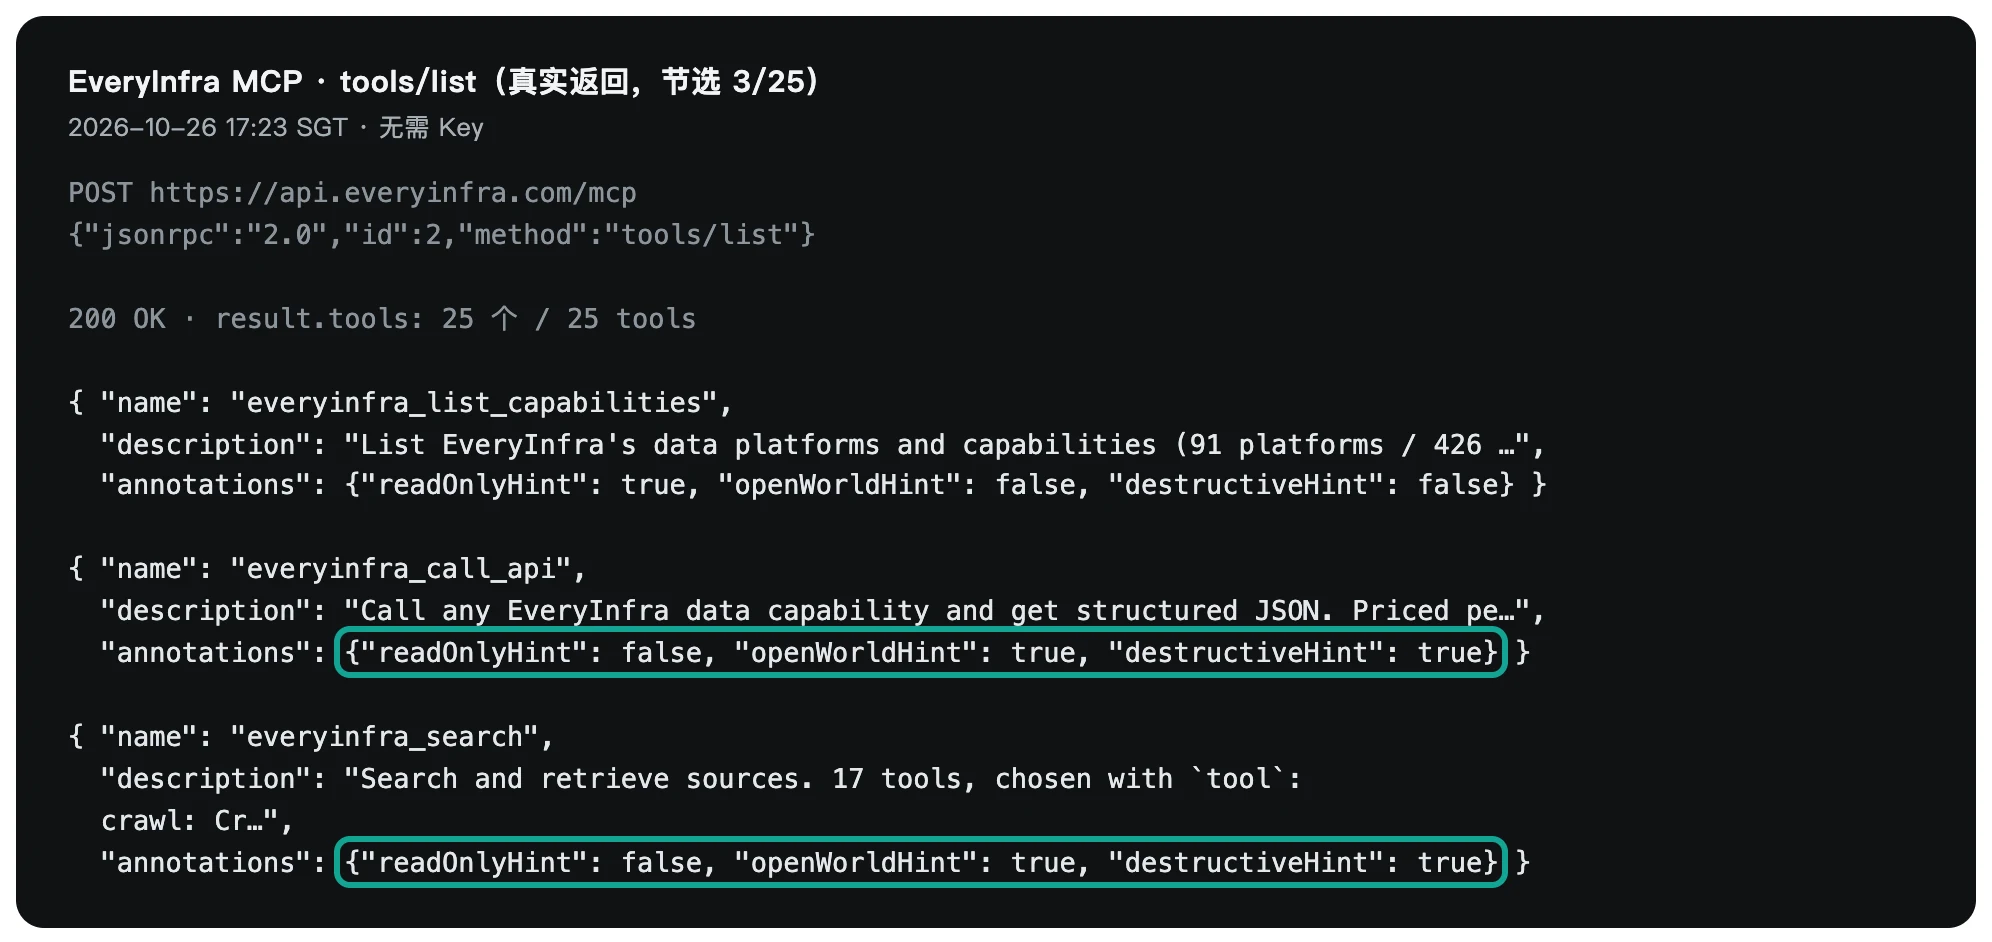
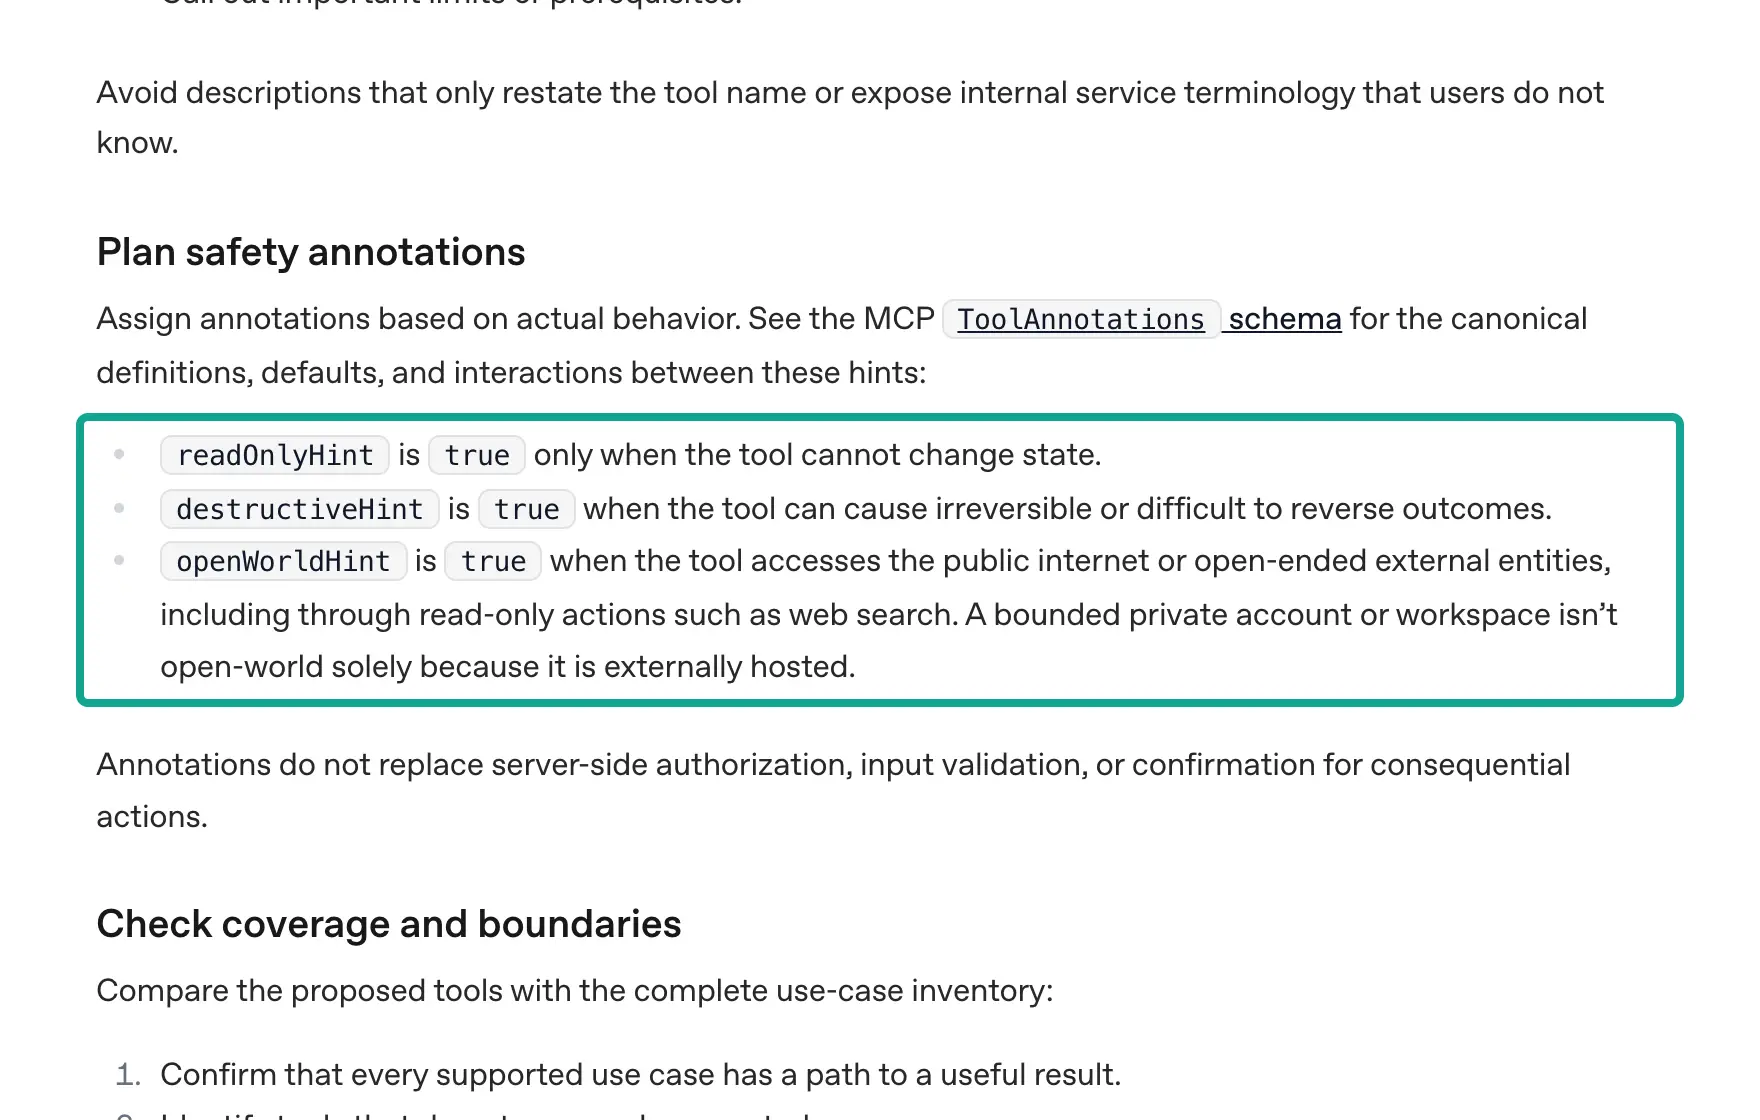
The MCP specification gives each tool a few annotations. The ToolAnnotations definition in the 2025-11-25 specification says that readOnlyHint true means the tool does not modify its environment, and the default is false. destructiveHint only has meaning when the tool is not read-only, and its default is true. openWorldHint means the tool works with an open world of external entities, and its default is true. OpenAI's plugin documentation says to set readOnlyHint to true only when the tool cannot change state.
It says that annotations help ChatGPT and Codex choose confirmation and safety behavior. An annotation does nothing by itself, but the host uses it to decide when to ask. For example, Codex has an MCP setting default_tools_approval_mode. With the value writes, it "prompts for tools that aren't marked read-only," per OpenAI's MCP page. ChatGPT works the same way: Add custom MCP server says it uses readOnlyHint to find read-only tools, treats tools without it as write actions, and asks for approval on write actions by default.
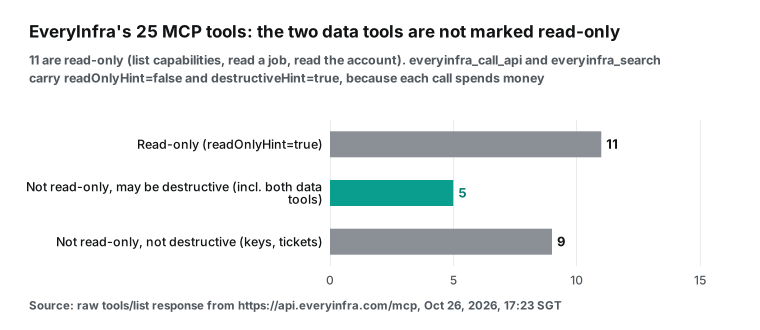
Of our 25 tools, 11 are read-only. They list capabilities, CAPTCHA types, keys, and tickets. They read a job, the account, usage, request logs, billing, and one ticket. One gets a top-up link.
The other 14 are not read-only, and 5 of them may be destructive. Two of the 5 are the data tools everyinfra_call_api and everyinfra_search. The other 3 have nothing to do with this job (one of them deletes a key). Why do the data tools not say "read-only"?
They change nothing on Reddit. But they take money from your wallet, and that changes the environment. Our rule is simple. A tool that reaches external sites gets openWorldHint=true. A paid call always gets destructiveHint=true.
We think this is right. If a tool that spends money says "read-only," the host lets it run with no question. When the model loops by mistake, you then have no chance to stop it.
On top of annotations, ChatGPT has your own permission setting. Managing app permissions in ChatGPT lists four levels. "Always ask" asks before reads and changes. "Allow read actions" reads without asking but asks before changes. "Allow low-risk actions" approves low-risk actions, and higher-risk actions may need approval or be denied.
"Allow all actions" runs supported actions with no more prompts. You can only set this last level for one app or one account. The account-wide and workspace-wide selectors do not offer it. The same page says the "Always allow" button is not offered to managed-workspace members or for actions that need extra safety review. The plugin changelog shows that these "when to ask" settings went live on June 12, 2026.
| Your setting | What our data tool (not read-only, may be destructive) does | Result in a scheduled task |
|---|---|---|
| Always ask | Asks every time; select allow | The task waits for you |
| Allow read actions | Not a read, so it asks | Same |
| Allow low-risk actions (default) | Marked destructive, so probably not low-risk: it asks | Same |
| Allow all actions (one app only) | No more prompts for supported actions | Can run unattended; forum users report that scheduled runs were still blocked by safety checks |
The second and third columns are our reading of the documents. ChatGPT does not publish the rule for "low-risk." In a normal chat, at any level, the most you get is one prompt on the first call: select allow and remember it for the chat, and that chat does not ask again. Scheduled tasks add one more thing to know, and the forum reports below are about it.
On October 4, 2026, a user posted a regression report on the OpenAI forum. The user's weekly scheduled task reads Gmail, does research, and decides which email to send. Gmail was set to "Allow all actions," and the task prompt gave standing approval. At the step that sends email and writes to Google Sheets, the call was blocked.
The message was "This tool call was blocked by OpenAI's safety checks" with no other detail. The report lists failures from September 30 to October 3. On October 5, another user pasted the same type of task prompt into a normal chat, and 8 of 8 Trello writes succeeded.
In the scheduled run, the writes were blocked. By October 8, replies still reported GitHub writes that worked on some days and failed on others, while reading and sorting email kept working. Another report from October 6 to 8 is worse. After a blocked GitHub write, hourly tasks changed to disabled about 64 to 65 seconds after the run, and the next run did not happen. These are user reports, and OpenAI has not given a finding in those threads.
OpenAI's documents say that write actions need approval and then run. They do not say that scheduled tasks cannot write. What these reports show is that some users saw approved writes blocked by safety checks in scheduled runs. ChatGPT treats our data tool as a write action. So if the radar must run unattended and reliably, do not put the data fetch inside the scheduled task.
Three designs: which one fits you
In ChatGPT the data tool needs approval, and nobody is there to approve a scheduled run. So you have three options. Open the gate in a workspace that allows it. Move the data fetch out of ChatGPT so that ChatGPT only reads. Or skip ChatGPT scheduled tasks.
| Design | For whom | How | Cost and risk |
|---|---|---|---|
| A. Direct MCP | Business, Enterprise workspaces | The admin creates and publishes the app, sets "Allow all actions" for it, and runs the task once by hand in a normal chat | Forum users report that scheduled runs can still be blocked by safety checks; the key is in the URL, so use a limited key |
| B. Split: outside fetch, ChatGPT reads | Plus, Pro, personal accounts | At 08:00 on Monday, cron, n8n, or GitHub Actions calls our REST API and writes a file to Google Drive or GitHub. At 09:00, the ChatGPT task reads that file with the Drive or GitHub connector and writes the report | One more scheduler; ChatGPT only reads, which is the most stable case |
| C. No ChatGPT scheduled task | People who want full automation and can write a little code | Your own cron calls the OpenAI Responses API with the remote MCP tool (require_approval: "never", allowed_tools), or you use Claude Code cloud scheduled tasks | Token billing; not in the ChatGPT interface |
Design B comes from a reply in the same forum thread by someone who builds enterprise automation. The AI makes the decision and writes a structured record. A deterministic program that you control does the action (reply of October 7, 2026). For a demand radar, the "action" is the data fetch. A scheduler can call EveryInfra with no human approval. The ChatGPT step only reads a file, which is the stable side of the line.
We tested a daily n8n workflow that calls EveryInfra. Change its keywords and write its output to Google Drive, and you have the first half of design B. For design C, the Responses API MCP guide shows how require_approval skips approvals and how allowed_tools imports only the tools that you need. Claude Code cloud scheduled tasks are available on Pro, Max, Team, and Enterprise and run while your laptop is closed. We did not test either path in this article. We list them as options only.
What the radar should fetch: three sets of real calls
A radar is only useful if its data is from this week and from this category. On October 26, 2026, from 17:31 to 17:41 SGT, we ran three sets with one test key. Set one is a SaaS category that many English readers know: password managers (keyword "password manager," community r/PasswordManagers). Set two is a hardware category: robot vacuums (keywords "robot vacuum," "Roborock," "Dreame," "robot vacuum mop," community r/RobotVacuums).
Set three uses Spanish keywords. In total we sent 32 requests. 22 were billed, for $0.016397. The other 10 were planned error tests, rate-limited requests, and empty results, and none of them cost money.
The first issue is time span. The catalog says the time window of reddit/search is fixed at the last month, and its max_limit is 25. With sort=newest, 25 posts span only hours. "password manager" covered 7.1 hours. "robot vacuum" covered 15.6 hours, "Roborock" 24.4 hours, and "Dreame" only 0.2 hours (it counted every new post with "dream" in it).
If the Monday run takes only the "newest 25," you see Sunday afternoon to Monday morning, and you miss Tuesday to Saturday. A community pull is different. reddit/subreddit_posts with sort=top, date_range=past_week, and limit=100 returned all 20 top posts of the week for r/PasswordManagers. They run from October 19 to October 26, a span of 160.1 hours. For r/RobotVacuums it returned 100 posts over 166.3 hours. Both are close to one full week.
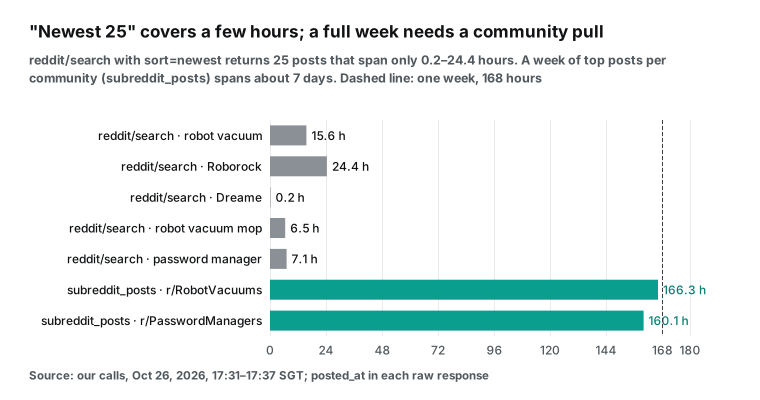
So the core of this job is reddit/subreddit_posts. Use keyword search only to find communities that you do not know yet. Our pre-set criterion for this point counted how many of 25 posts fall in the last 7 days. All 25 did. So by the original line, the answer was that weekly runs are enough.
But that line measured the wrong thing. All 25 posts were in the last 7 days because all of them were in the last few hours. We recorded this criterion as "badly designed" in our test log. We wrote the conclusion from the span, and we did not change the original criterion.
Keyword search also brings noise. The 25 "password manager" results came from 25 different communities. Only 12 contain both words. Others were a casino promotion, an app promotion, and login help posts for unrelated apps. A community pull has no such problem, because every post is from the community that you chose.
The second issue is what the week's posts contain. We pre-filter with fixed rules in the header of our analysis script. A post is a "question" when its title ends with a question mark. It is also a question when the title starts with how, what, which, best, or anyone.
A post "has complaint words" when its title or the first 400 characters of its body contain words such as stuck, broken, issue, avoid, or return. In r/PasswordManagers, 8 of 20 posts are questions and 1 has complaint words. In r/RobotVacuums, 49 of 100 are questions and 35 have complaint words.
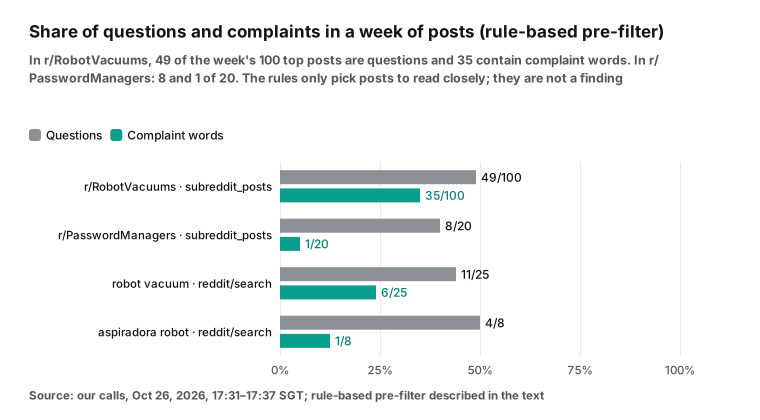
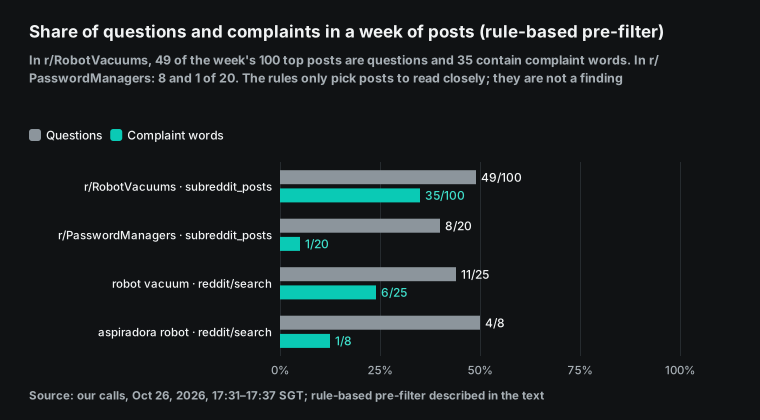
The rules only pick posts to read closely. They are not a finding. In r/PasswordManagers, the post with the most comments (76) has the title "Password manager scene is such a mess right now" and no complaint words. Our word list does not catch it as a complaint, but it is the clearest complaint of the week. Two posts asked for recommendations from "paranoid" users (35 and 30 comments).
One user tested whether three password managers catch a password change on 5 sites (37 comments, 35 points, the top score of the week). Another post asked where the security audit for a new product is (20 comments). The ChatGPT task should do the real sorting, because a model is good at reading slang. It can tell what a user is unhappy about. Our rules do one job: show if questions or complaints went up this week compared with last week.
The third issue is comments. We called reddit/comments with limit=100 on the two posts with the most comments. They returned 73 and 49 comments. The API returns top-level comments and does not expand replies, as our article on why Reddit comments look incomplete explains. In the "mess" thread, 13 comments had complaint words.
The top-voted replies told the poster to stop looking for a perfect product, or to self-host. In the "what do you actually use" thread, one user said they left their old manager because of recent problems with the app and with customer service. These details rarely appear in app store reviews. They are what a product team needs: why people switch and what makes them distrust a vendor.
The fourth issue is Quora volume. quora/questions with date_range=past_week_last_7_days and limit=30 found 4 new "password manager" questions in a week and 11 in 30 days. Two of the 4 weekly questions asked about password managers for AI agents. The same week, r/PasswordManagers had a post about an "AI agent integration" from a large vendor. Two sources with the same new topic in one week is the kind of signal that a radar exists to catch.
For robot vacuums, Quora had 2 questions in a week and 30 in a month (the limit, so the true number is higher). "Roborock" had 0 in a week. That call cost nothing, and the response said "reason": "empty_result_refunded". Quora adds "what do people think before they buy." The volume is small, so a monthly pull is enough.
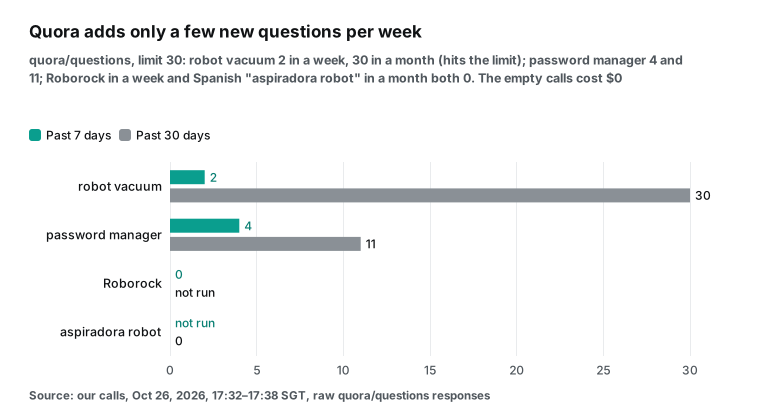
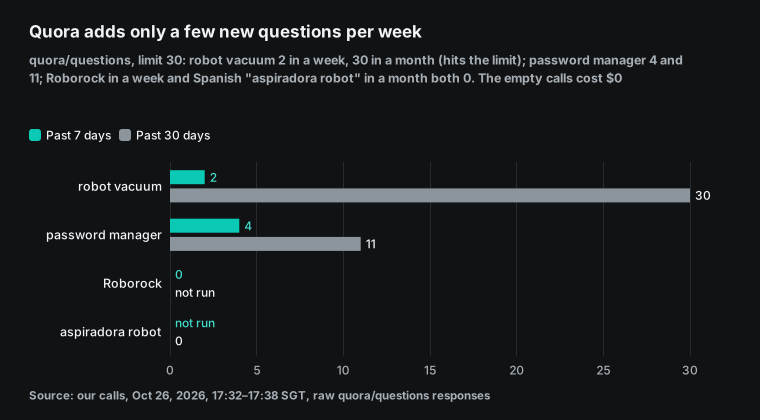
The Spanish set shows a language trap. reddit/search for "aspiradora robot" (relevance) returned 8 posts, and 7 matched. They came from Latin American communities such as r/AskChile and r/Colombia. But "robot aspirador" (newest) returned 11 posts, mostly from Portuguese communities, because Portuguese calls a robot vacuum an aspirador robot. On Quora, "aspiradora robot" returned 0 in a month (refunded).
"robot aspirador" over a year returned 5 English questions about "aspiring" robotics firms. Because the result was not empty, it cost $0.001389. For a radar in more than one language, test each language's keywords alone. Do not translate English keywords and hope.
| Set | Capability and parameters | Rows | Match | Span | Charged |
|---|---|---|---|---|---|
| Password managers | reddit/subreddit_posts r/PasswordManagers, top, past_week, 100 | 20 | all from that community | 160.1 h | $0.000556 |
| Password managers | reddit/search password manager, newest, 25 | 25 | 12 | 7.1 h | $0.000556 |
| Password managers | quora/questions password manager, past_week, 30 | 4 | 4 | — | $0.001389 |
| Password managers | reddit/comments, "mess" thread, limit 100 | 73 | — | — | $0.000556 |
| Robot vacuums | reddit/subreddit_posts r/RobotVacuums, top, past_week, 100 | 100 | all from that community | 166.3 h | $0.000556 |
| Robot vacuums | reddit/search Dreame, newest, 25 | 25 | 3 | 0.2 h | $0.000556 |
| Robot vacuums | quora/questions Roborock, past_week, 30 | 0 | — | — | $0 (refunded) |
| Spanish | quora/questions robot aspirador, past_year, 30 | 5 | 0 | — | $0.001389 |
How to write the task prompt
With these numbers, the task prompt can be strict. Below is a configuration example for a ChatGPT scheduled task. We did not run it in ChatGPT. Three parts matter.
Each call names its platform, action, and parameters, so the model does not choose. The report lists the calls and their cost at the end. When a call fails or is blocked, the model does not retry with other parameters. It lists the planned call so that you can run it by hand.
Run every Monday at 09:00 (America/New_York). Use only everyinfra_call_api from the @EveryInfra plugin. Make the calls below in order. Do not change parameters. Do not add calls.
1. platform=reddit, action=subreddit_posts, params={subreddit: "PasswordManagers", sort: "top", date_range: "past_week", limit: 100}
2. platform=reddit, action=subreddit_posts, params={subreddit: "Bitwarden", sort: "top", date_range: "past_week", limit: 50}
3. platform=reddit, action=search, params={keyword: "password manager", sort: "relevance", limit: 25}
4. platform=quora, action=questions, params={keyword: "password manager", date_range: "past_week_last_7_days", limit: 30}
5. From step 1, take the 5 posts with the highest comment_count. For each, call platform=reddit, action=comments, params={url: <post url>, limit: 100}
Output:
- "Complaints this week": top 5. One-line summary, post link, comment count. Describe the issue; do not name individual users.
- "Questions this week": top 5, same format.
- Compare with last week's report. Deduplicate by post url. Mark new topics.
- Appendix: for each call, rows returned, rows that match the keyword, billing.charged_usd, and the total.
If a call fails or is blocked: do not retry with other parameters. List its platform, action, and params in the appendix, then continue.
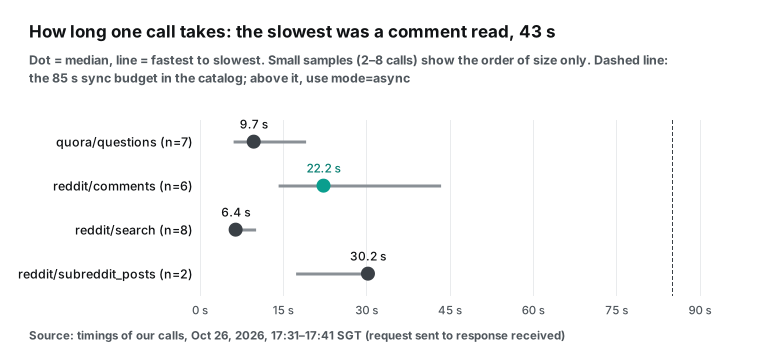
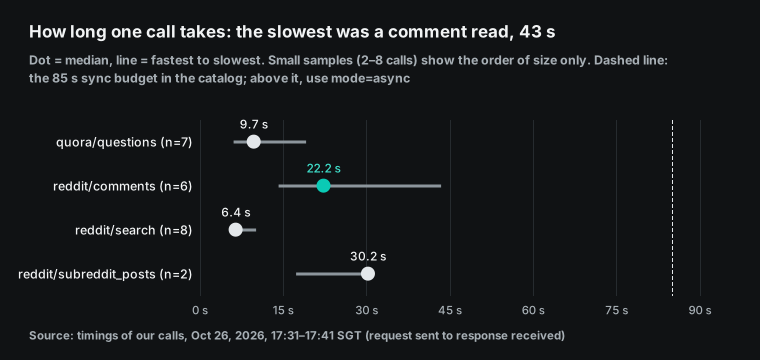
Step 5 is the slowest part of the radar. Our 6 reddit/comments calls between 17:33 and 17:41 SGT had a median of 22.2 seconds, and the slowest took 43.4 seconds. ChatGPT does not publish a timeout for one tool call. Codex's MCP settings use a default tool_timeout_sec of 60 seconds, which is a useful reference. Our catalog sets an 85-second budget for sync calls. Above that, add "mode": "async" to the request body and read the result with everyinfra_get_job.
A sample report from this week's real data
To show what a good report looks like, we wrote a sample by hand. It uses the r/PasswordManagers weekly top 20 posts, two comment threads, and the Quora pull from our 17:31 to 17:41 SGT run. ChatGPT did not write it. It shows what a weekly report must contain, and that each line must point back to a real post.
| Section | Item (comment count) | Evidence |
|---|---|---|
| Complaint 1 | "The password manager scene is a mess": a user finds a problem with every top product (76) | Post title and 73 top-level comments, 13 with complaint words |
| Complaint 2 | A new product has no public security audit (20) | Post title |
| Complaint 3 | A user left their old manager over recent app and support problems (in a 56-comment thread) | Top-level comment |
| Complaint 4 | Few products save every form field, so users stay with one vendor (7) | Post title |
| Complaint 5 | A vendor "turning into Google" with too much under one account (in a 56-comment thread) | Top-level comment |
| Question 1 | "What password manager do you actually use and recommend?" (56) | Title and 49 top-level comments |
| Question 2 | Thoughts on two new products (41) | Title |
| Question 3 | Honest feedback on a business-focused vault (11) | Title |
| Question 4 | Password managers for AI agents: benefits and must-have features | 2 Quora questions in one week, plus 1 Reddit post on an agent integration |
| Question 5 | "Can a password manager really make your accounts more secure?" (5 answers) | Quora |
Two points stand out. First, complaints and questions overlap a lot. The threads with the most comments look like questions, but their comments are full of complaints. So the report cannot sort by title alone. The $0.00278 for 5 comment reads is the best-spent money in the radar.
Second, the value of the report is the week-to-week change. One week only shows old themes: trust, audits, and switching. After a few weeks, a theme that suddenly grows, such as "password managers for AI agents," is the signal that product and marketing teams want. That is why we tested "run again later: what changed?" in a later section.
What it costs per week
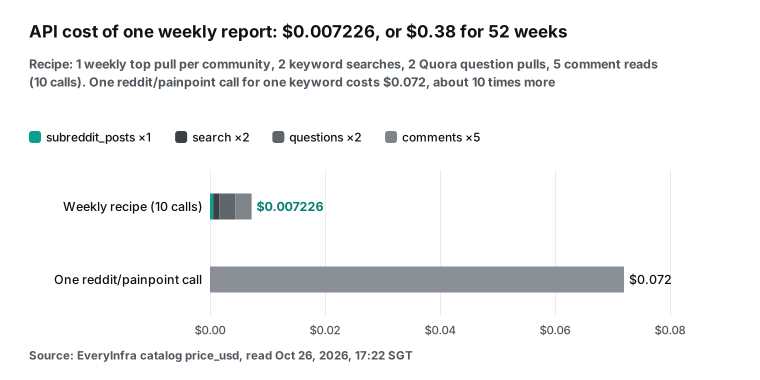
We use the price_usd from the capability catalog as read at 17:22 SGT. The weekly recipe has 10 calls: 1 reddit/subreddit_posts, 2 reddit/search, 2 quora/questions, and 5 reddit/comments.
| Capability | Unit price | Calls per week | Subtotal |
|---|---|---|---|
reddit/subreddit_posts | $0.000556 | 1 | $0.000556 |
reddit/search | $0.000556 | 2 | $0.001112 |
quora/questions | $0.001389 | 2 | $0.002778 |
reddit/comments | $0.000556 | 5 | $0.002780 |
| Total | 10 | $0.007226 |
52 weeks cost $0.375752. Three categories, one radar each, cost about $1.13 a year. Empty results are refunded, so the real number can only be lower. If you want a ready-made pain summary, the catalog also has reddit/painpoint at $0.072 per call. It finds posts by keyword, reads their comments, and returns negative comment counts and frequent words. One call costs as much as 10 weeks of the recipe. Use it once to scout a new category, not every week.
ChatGPT's own cost is separate, and you cannot turn it into a weekly number. The help center says Work and Codex share one usage structure. ChatGPT's pricing page gives ranges of messages per 5 hours for Plus (15 to 160 for GPT-6.1 Sol). It warns that similar tasks can use very different amounts.
In an r/codex post from October 5, 2026, a Plus user wrote about his 7:00 daily task. It ran for 13 minutes and used 29% of his 5-hour allowance. OpenAI support told him that scheduled tasks run in Work and share the allowance with Codex. At that scale, the ChatGPT side of a demand radar is much larger than the $0.007226 in API fees.
Rate limits, empty results, and failures: what you pay
In this test we hit four kinds of "no data." All four cost $0, but they affect a scheduled task in different ways.
| Case | Our real response | Charged | What it means for a scheduled task |
|---|---|---|---|
| No key | REST 401 missing_key; MCP returns isError: true and names two ways to send the key | $0 | If the URL lacks ?key=, the model reads a clear error instead of failing silently |
| Wrong parameter | sort: "latest" returns 422 with an allowed list; sort: "newst" returns 422 with did_you_mean: ["newest"] | $0 | The model can fix it, but a strict prompt never gets here |
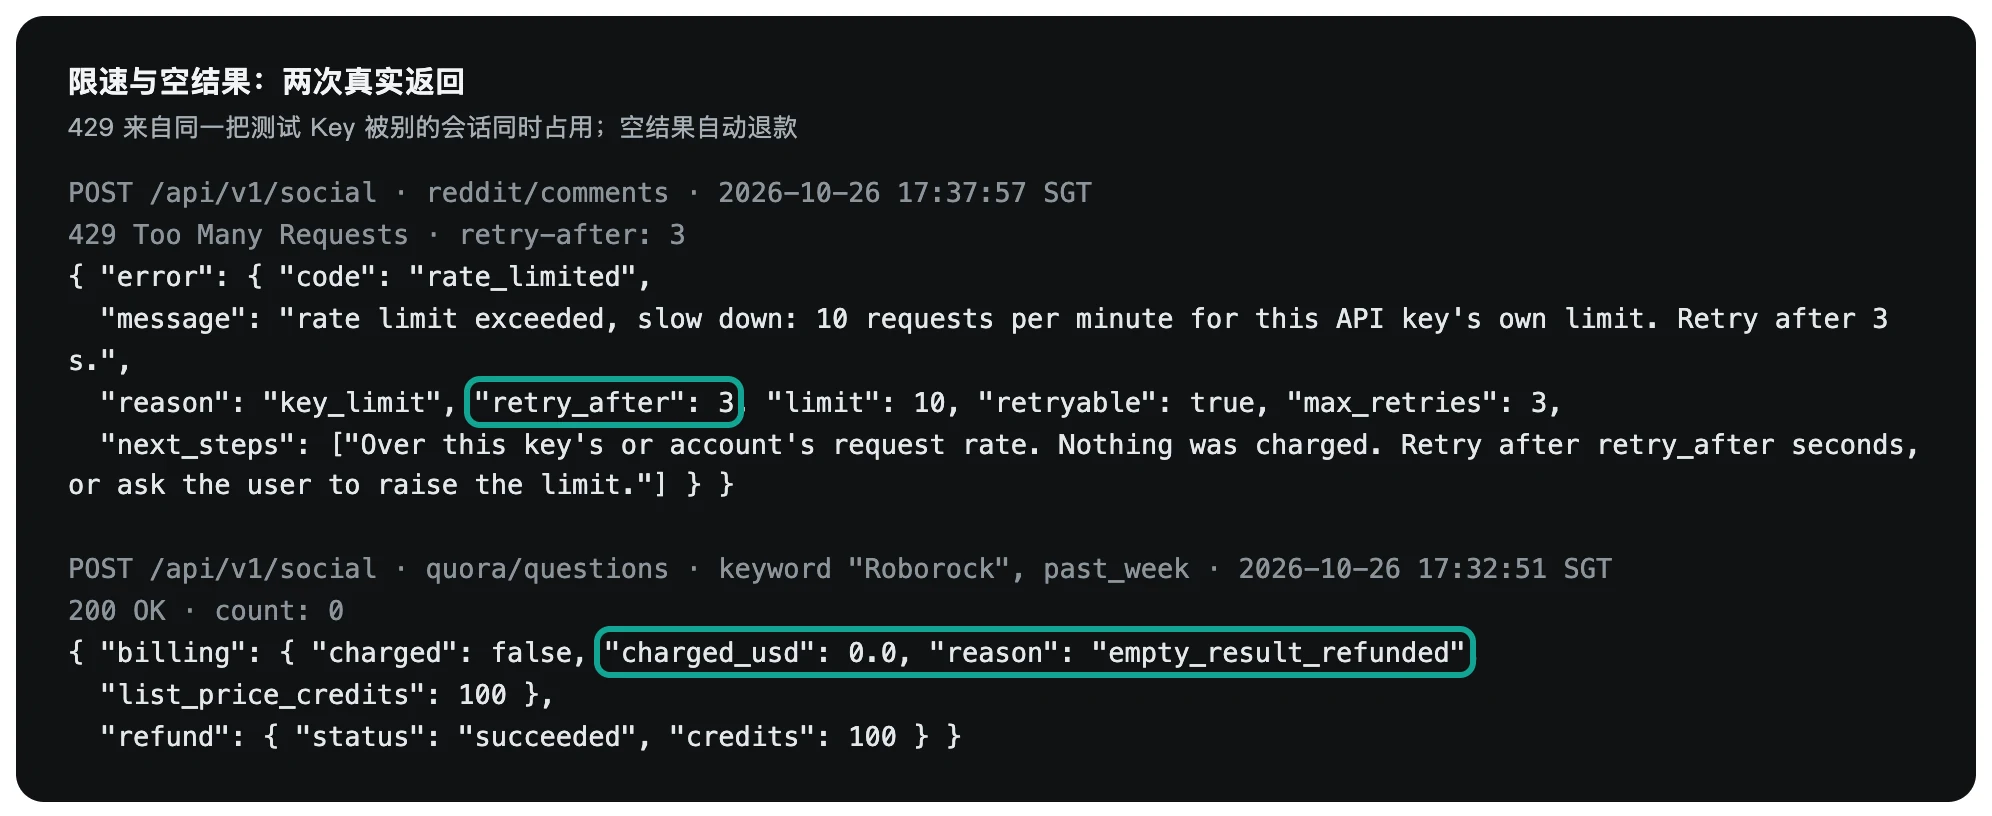
| Rate limit | 4 responses of 429 from 17:37:57 SGT, retry_after 3 s, limit 10 per minute | $0 | Other sessions used the same test key at that time. Let the model wait a few seconds and retry |
| Empty result | quora/questions for Roborock, 0 in a week, empty_result_refunded | $0 | Write "no new questions this week"; it is not a failure |
One detail matters here. We hit 4 rate limits because other sessions used this test key at the same time. The limit of 10 per minute is this key's own setting, not the limit for production keys. The OpenAPI document gives an account limit of 60 requests per minute.
One radar makes 10 calls, so it does not normally hit a limit. But if several category tasks share one key and all run at 09:00 on Monday, they can. Put a few minutes between them.
chatgpt scheduled tasks not working: common causes and fixes
In search suggestions, "not working" is the first word after "chatgpt scheduled tasks." We combined the limits in OpenAI's documents with forum reports. Nine causes matter for this job. The first five have official text. The last four are user reports, and we treat them as reports.
| Symptom | Cause | Source | Fix |
|---|---|---|---|
| The task did not run and shows "paused" | An action that needs approval pauses the task; tasks that nobody opens can pause; a deleted or archived chat pauses its task | Help center: Scheduled tasks | Check Scheduled for pending approvals; open the report every few weeks |
| You cannot create a new task | You reached the active task limit (3/5/10/15) | Same | Pause or delete unused tasks |
| A Free task is not on time | Free uses windows such as morning or night, at most once a day | Same | Use a paid plan for exact times |
| The task cannot read project files | Tasks created in a project cannot open the project's uploaded files | Same | Put the reference text in the task prompt, or in a place that a connector can read |
| You cannot create a task in a GPT, a voice chat, or a locked chat | Scheduled tasks do not support these | Same | Create it in a normal chat or in Work |
| Writes are blocked (user reports) | "blocked by OpenAI's safety checks," while the same prompt works in a normal chat; the documents only say writes need approval | Forum reports since October 4, 2026 | Move the data fetch to an outside scheduler; ChatGPT only reads (design B) |
| The task disables itself after a run | About one minute after a failed write, the task changes to disabled | Forum report, October 6 to 8, 2026 | Same; check the task status each week |
| Adding a custom MCP server shows "does not implement OAuth" | A firewall blocked the check request, or the server has no OAuth | Forum report, September 3, 2026 | For EveryInfra, choose "No authentication" |
| The task uses a lot of Work allowance | Scheduled tasks run in Work and share the allowance with Codex | r/codex, October 5, 2026; pricing page | Keep the task prompt short and strict; ask for a summary only |
A help thread on r/ChatGPT with more than 30 replies mixes several of these problems. One user's hourly task stopped writing to GitHub and then turned itself off. Another user's Monday task did not appear in the task list for three weeks. A third user asked why a task did not run. The model replied that it did the work, but the user could not see it. That last case is the one to worry about.
A model's account of what it did is not evidence. That is why our prompt asks for a call list and charged_usd at the end of the report. Whether a call happened, how many times, and what it cost should come from our call records. Each call in the console has a request_id. Another thread calls auto-pause a paradox.
A task that works well needs no attention, but a task that gets no attention can pause as unused. Send the Monday radar to a place that you really read. That is part of the fix.
Run it again within the hour: how to deduplicate week to week
A weekly radar compares each Monday with the Monday before. We wanted to know what changes between two runs and which field to deduplicate on. So we repeated three calls from the first set with the same parameters. Before the test, we wrote down the line "at least 45 minutes apart." The first repeat ran from 18:13:31 to 18:14:28 SGT. That was 38.7 to 42.4 minutes after the first run, which is below our line.
We recorded it that way in our test log. So we did a second repeat from 18:21:02 to 18:21:52 SGT, 46.1 to 50.0 minutes after the first run, which meets the line. The 6 extra calls cost $0.003336. With them, the full test has 38 requests, 28 billed, for $0.019733.
| Call | First run (SGT) | Rows: first → repeat 1 → repeat 2 | New in repeat 2 | Gone in repeat 2 |
|---|---|---|---|---|
reddit/search robot vacuum, newest, 25 | 17:31:05 | 25 → 25 → 25 | 1 (a deals post) | 1 (the oldest) |
reddit/subreddit_posts r/RobotVacuums, top, past_week, 100 | 17:32:11 | 100 → 24 → 100 | 1 (a new question about 3.8 cm door sills) | 1 (the week's top post) |
reddit/subreddit_posts r/PasswordManagers, top, past_week, 100 | 17:35:46 | 20 → 19 → 19 | 0 | 1 |
The table gives three lessons. First, past_week is a moving window of 168 hours that ends when you call. It is not a calendar week. The top post of r/RobotVacuums, "Lol avoid Eureka" with 32 points, was posted on October 19, 2026, at 10:09 UTC. At 18:13 SGT, which is 10:13 UTC on October 26, it was more than 7 days old and left the window.
The same thing happened in r/PasswordManagers to a post from October 19 at 10:06 UTC. If the task always runs at the same time, each post falls in exactly one week. If a Monday run starts late, for example because the task was paused and you resumed it, you lose the posts at the edge. If it starts early, you see some posts twice.
Second, deduplicate by id or url, not by title. Posts that stay between runs keep the same id and url, even when their points and comment counts change. Keep last week's list of id values in the report, or in the file of design B. Mark a post as "new" when its id is not in that list.
In our Spanish set, one user posted the same question in two Chilean communities two and a half minutes apart. Those are two posts with two id values. Use a normalized title only as a second filter for cases like that.
Third, and least expected: the row count is not stable. With the same parameters, r/RobotVacuums returned 100 rows, then 24, then 100 again, in less than 50 minutes. The 24 rows of the first repeat were exactly the posts with 5 points or more. The 76 posts with 0 points were missing, and together they had 16 comments. The 24-row response came with status 200 and was billed as usual.
For the radar this does not matter much, because every post that goes into the report was there. But it does matter if you count posts to measure the week's volume. That is why the report's appendix lists rows per call. Sometimes a community pull returns less than half the rows of the week before. Then run that call once more before you decide that the community went quiet.
There is one more effect, and it is true of any ranking by votes. A post from Sunday night reaches the Monday run with only a few hours of votes. The next week, it is outside the window. So posts from the last days of the week tend to rank low. If this matters to you, add a short list of "posts from the last 24 hours with the most comments" to the report. It needs no extra calls: filter the same community pull by posted_at.
Field reference: every field the report uses
We checked the fields of these capabilities one by one against response_fields in the catalog. This table lists only the fields that the radar uses. Platform and capability pages: Reddit data API, Quora data API, reddit/search, reddit/subreddit_posts, reddit/comments, and quora/questions.
| Capability | Field | Meaning | Use in the radar |
|---|---|---|---|
reddit/search, reddit/subreddit_posts | id, url | Post ID and link | Deduplicate and compare with last week |
| Same | title, text | Title and body | Input for sorting |
| Same | community | Subreddit name without the r/ prefix | See where talk is concentrated |
| Same | like_count, comment_count | Score and comment count | Rank posts; pick posts for comment reads |
| Same | posted_at | Post time | Check that the post is from this week |
| Same | flair | The post's flair text | Some communities use it for "recommendation" or "help" |
reddit/comments | text, like_count, posted_at | Comment body, score, time | Read the details of a complaint |
quora/questions | title, url, posted_at | Question title, link, time | "Questions this week" |
| Same | answer_count, follower_count | Answers and followers | See if anyone answers |
Both Reddit capabilities also return author_username, but the radar does not need it. Reddit's Responsible Builder Policy prohibits inferring sensitive traits such as health or politics from the data. It also prohibits attempts to re-identify users. The prompt line "do not name individual users" exists for that reason.
The same data without ChatGPT
For the scheduler in design B, or to look at the data by hand first, call the REST API. The parameters are the same as in MCP, without the JSON-RPC wrapper:
curl -s https://api.everyinfra.com/api/v1/social \
  -H "Authorization: Bearer $EVERYINFRA_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"platform":"reddit","action":"subreddit_posts",
       "params":{"subreddit":"PasswordManagers","sort":"top","date_range":"past_week","limit":100}}'
At 17:35:46 SGT this request returned the 20 posts of the week in 30.2 seconds and cost $0.000556. The catalog gives a max_limit for each capability. reddit/search is 25 (higher values are cut to 25). reddit/subreddit_posts and reddit/comments are 100.
quora/questions is 200. Billing is per call, not per row, so a full limit within the cap gives the most data for the money. The full first steps are in the quickstart. For MCP in general, see our remote MCP acceptance test and the MCP server page.
Where this approach stops working
First, we did not test any ChatGPT behavior. We can only write what the documents said on October 26, 2026. OpenAI changes plan and permission rules often (most help center pages we cite showed "updated hours ago"), so check again before you rely on them. Second, two OpenAI pages differ on whether Pro can call the data tool. The help center FAQ says Pro custom MCP has read/fetch permissions only. The developer guide says read and write tools are supported, with approval for writes. We follow the developer guide, and we did not test Pro.
Third, our question and complaint rules are a pre-filter. A sample of 20 or 100 posts shows that there are "many," not a share. For shares, run for several weeks and check samples by hand each week. Fourth, Reddit stops RSS on November 13, 2026. It also plans to close its public API by March 2027 (TechCrunch, September 30, 2026, original in the r/modnews post). A radar built on RSS must change; we covered how to replace Reddit RSS monitoring.
Fifth, the radar says what users talk about, not how big a market is. Reddit and Quora users are not all buyers. Compare the findings with sales and support data.
Recent changes
- August 25, 2026: scheduled tasks can respond to app events and can be shared (ChatGPT release notes). Plus and Pro users can start Work tasks on new Gmail or Slack messages or GitHub pull request changes. Free users can have 3 active tasks. For you: a time-based radar does not change, but you can share a finished radar with a teammate who connects their own apps.
- September 29, 2026: supported plugins can start automations from MCP events (same release notes; developer page: MCP Events). It needs MCP 2.0 (protocol version 2026-07-28), and the server pushes events by webhook. For you: EveryInfra is a pull API and does not push events. To get "alert me on new posts," you still pull on a schedule.
- October 1, 2026: custom MCP no longer needs developer mode (OpenAI staff reply on the forum). Add servers from the Plugins page; the workspace permission has a new name. For you: old guides that tell you to find a "Developer mode" switch are out of date.
- From October 4, 2026: user reports of blocked writes in scheduled tasks (official forum; no reply from OpenAI yet). Reads are not affected. For you: the documents say write actions need approval and then run, but for a tool that spends money or changes data with nobody watching, moving it out of ChatGPT is the most stable choice.
- September 30, 2026: Reddit announces the end of RSS on November 13 and app registration before January 12, 2027 (r/modnews). For you: a radar that follows communities by RSS must change before November 13.
- October 26, 2026: EveryInfra keys can have a USD spend limit (
spend_limit_usdandkey_spend_limit_reachedin the OpenAPI document). For you: cap the key before you put it in a ChatGPT URL.
FAQ
Are chatgpt tasks and chatgpt scheduled tasks the same thing? Yes, they are two names for one feature. The old interface said "Tasks." The help center title is now "Scheduled tasks in ChatGPT," and the entry is the Scheduled page in the sidebar. It supports one-time, recurring, and monitoring tasks. Source: search suggestions list "chatgpt tasks" next to "chatgpt scheduled tasks" (read October 26, 2026); help center.
chatgpt scheduled tasks not working: what do I check first? Open the Scheduled page and look for "paused" or a pending approval. The help center says an action that needs approval pauses the task, and tasks that nobody opens can pause. Then check whether you created the task in a project, a GPT, a voice chat, or a locked chat. If the task writes data, look for "blocked by OpenAI's safety checks" in the run (a case that forum users have reported). Source: suggestions "chatgpt scheduled tasks not working" and "chatgpt scheduled tasks not showing"; help center; forum report.
Does a chatgpt custom mcp connector still need developer mode? No. It changed on October 1, 2026. Open Plugins, select "+", and select "Add custom MCP server" from the menu. In a Business workspace, only admins and owners can create one. In Enterprise and Edu, admins grant the permission by role. Source: suggestion "chatgpt custom mcp connectors"; OpenAI staff reply; help center.
What is the chatgpt scheduled tasks limit? It depends on the plan. Active tasks: 3 for Free and Go, 5 for Plus, 10 for Business and Edu, 15 for Pro and Enterprise. Paid plans can repeat hourly; Free at most once a day. Event-triggered tasks can run up to 30 times per hour and 720 times per day across all of them. Source: suggestion "chatgpt scheduled tasks limit"; help center.
Can ChatGPT call the EveryInfra data tools if they are not marked read-only? Yes. OpenAI's developer guide says ChatGPT supports read and write tools. A tool without readOnlyHint counts as a write action, and write actions need approval by default: the first call in each chat shows a prompt, you select allow, and you can remember it for that chat. A new chat asks again. In a scheduled task nobody is there to approve, so the task pauses; run the task once by hand in a normal chat before you schedule it. Source: Add custom MCP server; our tools/list reads on October 26, 2026, at 17:23 and 20:04 SGT.
Which authentication do I choose for EveryInfra in ChatGPT? Choose "No authentication" and put the key in the URL as ?key=. We publish no OAuth metadata, and all three discovery paths return 404, so OAuth fails. Use a separate key with limited capabilities and a USD spend limit. Source: our probe on October 26, 2026, at 17:42 SGT; developer page on authentication.
How much does a weekly demand radar cost? The API fee for 10 calls is $0.007226 a week, about $0.38 a year. Empty results are refunded. ChatGPT's plan and Work usage are separate. Source: our calculation from the price_usd values in the capability catalog on October 26, 2026; real charges matched the catalog.
Related reading
- A daily n8n report that calls EveryInfra: a test of the 2.45 scheduler
- Remote MCP acceptance: from "tools found" to "really usable"
- Reddit ends RSS on November 13: how to change your monitoring
- Why Reddit comments look incomplete
- Multi-platform reputation monitoring
- Reddit pain point research: reddit/painpoint
- Pricing
References
- Scheduled tasks in ChatGPT, OpenAI Help Center, read October 26, 2026, <https://help.openai.com/en/articles/10291617-scheduled-tasks-in-chatgpt>
- ChatGPT Work and Codex, OpenAI Help Center, read October 26, 2026, <https://help.openai.com/en/articles/20001275>
- ChatGPT release notes (entries of August 25, September 29, and October 20, 2026), OpenAI Help Center, <https://help.openai.com/en/articles/6825453-chatgpt-release-notes>
- Connecting custom MCP servers in ChatGPT, OpenAI Help Center, read October 26, 2026, <https://help.openai.com/en/articles/12584461-connecting-custom-mcp-servers-in-chatgpt>
- Managing app permissions in ChatGPT, OpenAI Help Center, <https://help.openai.com/articles/20001495>
- Connected apps in ChatGPT, OpenAI Help Center, <https://help.openai.com/en/articles/11487775-apps-in-chatgpt>
- About ChatGPT Pro tiers, OpenAI Help Center, <https://help.openai.com/articles/9793128>
- What is ChatGPT Plus?, OpenAI Help Center, <https://help.openai.com/en/articles/6950777-what-is-chatgpt-plus>
- What is ChatGPT Go?, OpenAI Help Center, <https://help.openai.com/en/articles/11989085-what-is-chatgpt-go>
- ChatGPT Business release notes (Team tasks, September 29, 2026), OpenAI Help Center, <https://help.openai.com/en/articles/11391654-chatgpt-business-release-notes>
- ChatGPT Enterprise and Edu release notes, OpenAI Help Center, <https://help.openai.com/en/articles/10128477-chatgpt-enterprise-and-edu-release-notes>
- Regression: Scheduled Tasks safety checks block authorized Gmail sends and Google Sheets writes, OpenAI Developer Community, October 4, 2026 (user report), <https://community.openai.com/t/1403242>
- Developer Mode missing from Security & Login on ChatGPT Pro (OpenAI staff reply, October 1, 2026), OpenAI Developer Community, <https://community.openai.com/t/1402157>
- Feature Request: Use an Identifiable User-Agent for Custom MCP Server Validation, OpenAI Developer Community, September 3, 2026 (user report), <https://community.openai.com/t/feature-request-use-an-identifiable-user-agent-for-custom-mcp-server-validation/1394731>
- ChatGPT Scheduled Tasks fail to write to GitHub and automatically disable themselves, OpenAI Developer Community, October 8, 2026 (user report), <https://community.openai.com/t/chatgpt-scheduled-tasks-fail-to-write-to-github-and-automatically-disable-themselves-after-failed-executions-without-user-authorization/1404882>
- Connect and test your plugin, OpenAI Developers, <https://developers.openai.com/plugins/deploy/connect-chatgpt>
- Authentication, OpenAI Developers, <https://developers.openai.com/plugins/build/auth>
- Define tools (Plan safety annotations), OpenAI Developers, <https://developers.openai.com/plugins/plan/tools>
- Build an MCP server, OpenAI Developers, <https://developers.openai.com/plugins/build/mcp-server>
- Plugin UI changelog (App permission controls, June 12, 2026), OpenAI Developers, <https://developers.openai.com/plugins/changelog>
- MCP Events, OpenAI Developers, <https://developers.openai.com/plugins/build/mcp-events>
- Scheduled tasks (Codex), OpenAI Developers, <https://developers.openai.com/codex/app/automations>
- MCP and Connectors (Responses API), OpenAI Developers, <https://developers.openai.com/api/docs/guides/tools-connectors-mcp>
- Model Context Protocol, ChatGPT Learn, <https://learn.chatgpt.com/docs/extend/mcp>
- Pricing (ChatGPT Work and Codex), ChatGPT Learn, <https://learn.chatgpt.com/docs/pricing>
- Schema Reference: ToolAnnotations, Model Context Protocol 2025-11-25, <https://modelcontextprotocol.io/specification/2025-11-25/schema#toolannotations>
- Authorization, Model Context Protocol 2025-11-25, <https://modelcontextprotocol.io/specification/2025-11-25/basic/authorization>
- RFC 6750: The OAuth 2.0 Authorization Framework: Bearer Token Usage, IETF, October 2012, <https://www.rfc-editor.org/rfc/rfc6750>
- RFC 9728: OAuth 2.0 Protected Resource Metadata, IETF, <https://datatracker.ietf.org/doc/html/rfc9728>
- MCP Inspector, Model Context Protocol, <https://modelcontextprotocol.io/docs/tools/inspector>
- Continuing our infrastructure updates: What's changing in the coming months, r/modnews, September 30, 2026, <https://www.reddit.com/r/modnews/comments/1wubgvt/continuing_our_infrastructure_updates_whats/>
- Reddit is killing RSS feeds and ending public API access because of AI bots, TechCrunch, September 30, 2026 (secondary; original in 31), <https://techcrunch.com/2026/09/30/reddit-is-killing-rss-feeds-ending-public-api-access-because-of-ai-bots/>
- Responsible Builder Policy, Reddit Help, <https://support.reddithelp.com/hc/en-us/articles/42728983564564-Responsible-Builder-Policy>
- Scheduled tasks failing, r/ChatGPT (user thread), <https://www.reddit.com/r/ChatGPT/comments/1x049yo/scheduled_tasks_failing/>
- Isn't this kind of a paradox for scheduled tasks?, r/ChatGPT (user thread), <https://www.reddit.com/r/ChatGPT/comments/1wvnhp8/isnt_this_kind_of_a_paradox_for_scheduled_tasks/>
- Did ChatGPT Scheduled Tasks recently start consuming your Codex/Work usage allowance?, r/codex, October 5, 2026 (user report), <https://www.reddit.com/r/codex/comments/1wxxqwh/did_chatgpt_scheduled_tasks_recently_start/>
- Automate work with scheduled tasks, Claude Code Docs, <https://code.claude.com/docs/en/routines>
- ChatGPT Scheduled Tasks: What They Are and How to Use Them, Zapier, September 2, 2026 (secondary), <https://zapier.com/blog/chatgpt-scheduled-tasks/>
- ChatGPT MCP: Connect MCP Servers to ChatGPT, AnythingMCP, September 25, 2026 (secondary), <https://anythingmcp.com/guides/clients/chatgpt>
- EveryInfra capability catalog, read October 26, 2026, 17:22 SGT, <https://api.everyinfra.com/api/v1/social/catalog>
- EveryInfra OpenAPI document, read October 26, 2026, 17:42 SGT, <https://api.everyinfra.com/openapi.json>
- r/PasswordManagers community page, <https://www.reddit.com/r/PasswordManagers/>
- Add custom MCP server (section "Reviewing and confirming tool calls"), OpenAI Developers, read October 26, 2026, 20:05 SGT, <https://developers.openai.com/api/docs/guides/custom-mcp-server>
Reference BL-55