Douban API in 2026: Official Access, Open Source or Pay-Per-Call
Douban API in 2026: we tested three routes. Official keys need a deal, most GitHub tools need cookies, and paid calls cost $0.0139 per 1,000 comments.
Yes, you can still get Douban data through an API, but there are three different routes and each has a catch. The official Douban API stopped issuing keys to the public in 2018, and commercial use now needs written permission from Douban. GitHub has many Douban scrapers, but the most-starred ones are old, and most of the active ones need a logged-in cookie. Pay-per-call data APIs work without your own Douban account. One of the services in this comparison is EveryInfra, our own API, so we are a vendor here.
Our numbers come from two sources. We read the catalog on November 21, 2026 at 00:13 Singapore time. We made 17 live calls between 00:19 and 00:31. Within Douban, our price per record differs by about 1,700 times by data type. One call returns 100 popular short comments for $0.001389, which is $0.0139 per 1,000. Long reviews cost $0.024 each, which is $24 per 1,000.
Does Douban have an official API?
Douban had a full public API for years. An Internet Archive copy of the developer site from June 26, 2018 describes access to books, films, music, local events and interest-based user relations. It also offered "log in with Douban" for third-party apps. Douban's own Python client, douban/douban-client, documents the old quota: public calls without an API key were limited to 10 per minute per IP address. That repository is archived, has 741 stars, and its last commit is from 2014-06-22.
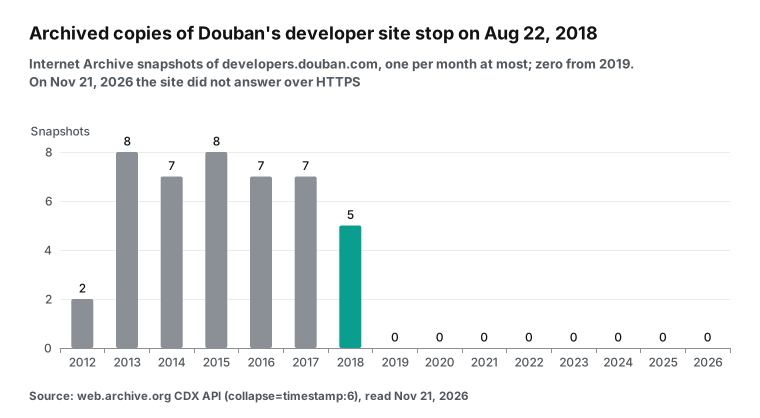
We found no formal shutdown notice from Douban. To date the change, we used two records that anyone can check again. The first record is the Internet Archive CDX index for developers.douban.com. With one record per month at most, it holds 44 records from 2012-08-05 to 2018-08-22, and none after 2018. The last record with status 200 is from 2016-12-27. All later records are 301 redirects.
The second record comes from developers. A 2022 blog post called Douban Escape Plan gives three dates. The platform shut down in September 2018. The book API ended in April 2019, and the film API ended in 2020.
A V2EX thread from August 18, 2020 shows the last step from the user side. Several API keys that people shared online all stopped on the same day with the error invalid_credencial2. The archive records stop in late August 2018, and developers reported the shutdown in September 2018. The two records agree.
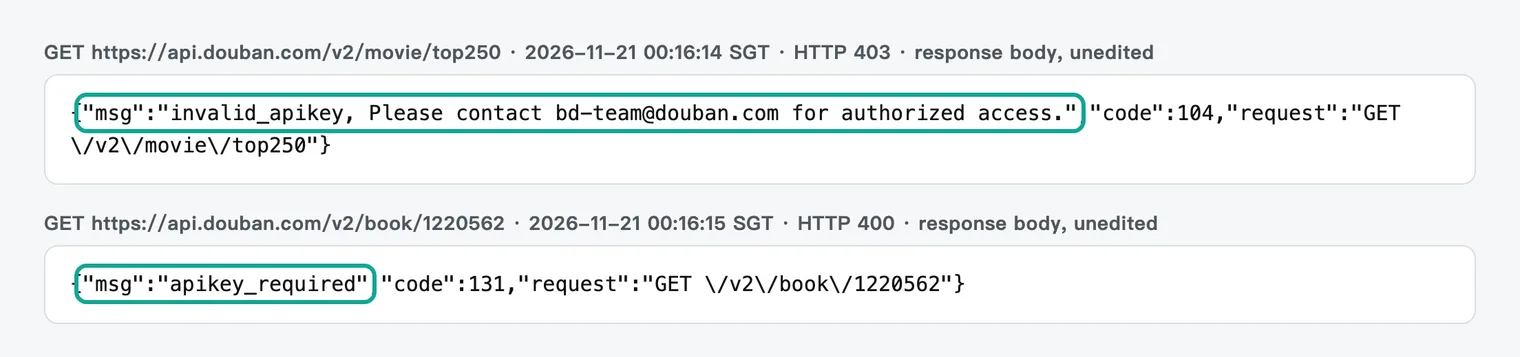
To see the situation in 2026, we called the old endpoints directly on November 21 at 00:16 Singapore time. The film endpoint https://api.douban.com/v2/movie/top250 returned HTTP 403 with error code 104. The body said "invalid_apikey, Please contact bd-teamhttps://api.douban.com/v2/book/1220562 returned HTTP 400 with code 131 and the message apikey_required. So the API host still answers, but it refuses anonymous calls and points you to Douban's business team.
At the same time, the developer domain still resolved to a Douban forwarding server. An HTTPS request to it got no response at all, and curl recorded status 000. There is no self-service page where you can register an app today. We checked this on 2026-11-21 and found no public sign-up page, price list, quota table or review criteria.
The only documented way in is the email address in Douban's Legal Notice. Section 2, item 3 tells anyone who wants to use Douban content to contact bd-team
| Official channel | What we saw on 2026-11-21 | What it gives | What it needs |
|---|---|---|---|
| api.douban.com v2 | Anonymous calls return 403 invalid_apikey or 400 apikey_required | Book, film and music data with a valid key (old scope) | A key issued by Douban; no public channel |
| developers.douban.com | Domain resolves, HTTPS gives no response; archive records stop on 2018-08-22 (301 redirect) | Nothing | No entry point |
| Business permission via bd-team | Contact named in the Legal Notice, section 2, item 3 | Depends on the contract; not public | Written permission; terms not public |
| Douban app internal API | Open-source tools say it needs request signing and login | Same data as the app | Signing constants, account, SMS check |
Item 2 of the same section lists uses that need written permission, and the list is broad. It includes selling the data as a product, showing Douban scores or user comments in a commercial product, and training large language models. It also includes data statistics, analysis reports, opinion monitoring and marketing. It names "data collection, web crawlers or similar" that harm or may harm Douban's rights.
The current Terms of Use are a revision published on May 27, 2025. Clause 9.6 forbids interference with the service and tools made for that purpose. These two documents apply the same way to all three routes. An open-source script, a paid API and your own scraper all solve the technical problem. None of them gives you Douban's permission.
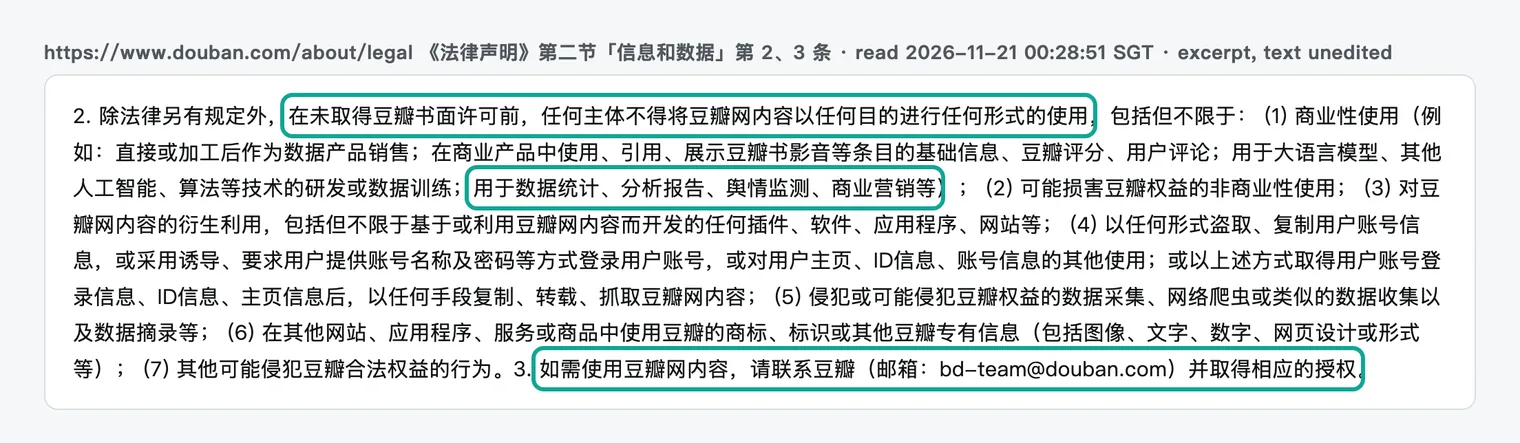
We do not give legal advice. We only show the source text. Item 2 names "opinion monitoring" and "analysis reports". It does not name personal reading logs or class projects. Check the clause text yourself, or ask a lawyer, to see which item fits your use. If you ask Douban for permission, write a complete first email. Say who you are and which data you need: titles, scores, short comments, long reviews or group posts. Give the volume, the frequency, the storage location, and whether you will show, sell or train on the data.
Do the old video tutorials still work?
We used youtube/search with the query "Douban API" and picked the first 3 relevant videos. The first one is a Python tutorial uploaded on 2022-08-11 with 26 views. The second one is a REST API lesson from 2019-06-19 with 124 views. The third one is a server-side request demo from 2021-10-08 with 27 views. All three are in Chinese.
None of the three has captions. Our youtube/transcript calls returned empty results and cost $0, so we can only judge from titles and descriptions. All three show direct calls to the old api.douban.com endpoints. Based on our 00:16 test, that code now stops at the first request with invalid_apikey or apikey_required. One more result in the top 10 was a 2024 tutorial about breaking the app's request signature. Clause 9.6 of the Terms of Use forbids cracking the service, so we do not cover it.
Is there a ready-made Douban API? The three routes side by side
Yes, all three routes exist today: official permission, open-source projects and pay-per-call APIs. They differ on five points. Who maintains the code? Do you need a Douban account or cookie? Who pays for failures? Can you connect it to an AI tool? Who gets Douban's written permission?
The EveryInfra column comes from the catalog and live calls. The open-source column comes from raw GitHub API data. The official column comes from the requests above. We do not name other pay-per-call services. Their column lists what you should check.
| Item | Douban written permission | GitHub open source | EveryInfra pay-per-call | Other pay-per-call services |
|---|---|---|---|---|
| Billing unit | Set by contract; not public | Free; you pay for servers and proxies | Per call; long reviews per row | Check each price page |
| Per 1,000 short comments | Not public | $0 (no labor or proxy cost counted) | $0.0139 (100 per call) | Check rows per call |
| Per 1,000 long reviews | Not public | $0 | $24 ($0.024 each) | Check per call or per row |
| Failed and empty calls | Set by contract | Your cost | Not billed (7 empty and 1 x 422 in our run, all $0) | Check refund rules |
| Douban account or cookie | Needs an issued key | 8 of 18 READMEs mention cookies or login | Not needed | Check |
| MCP support | None | 6 MCP or CLI projects, mostly local | Remote MCP with 12 tools | Check |
| Douban written permission | Yes, if you sign | No | No; you must get it yourself | No |
| Maintenance | Douban | Individual authors, most inactive | Us | Each vendor |
A pay-per-call API handles fetching, parsing, retries and billing, so it saves engineering time. It does not sign a contract with Douban for you.
Can you still use the Douban projects on GitHub?
On November 21, 2026 at 00:17 Singapore time, we used the GitHub search API with five queries. The queries were douban api, douban spider, douban crawler, douban mcp and the Chinese term for a Douban crawler. We took the top 15 results by stars for each query. Then we removed general collections that only mention Douban in passing. That left 18 repositories that focus on Douban, with 8,301 stars in total. For each one, we read the repository data, the latest commit and the README.
| Repository | Stars | Last commit | License | Cookie or login | Purpose |
|---|---|---|---|---|---|
| lanbing510/DouBanSpider | 2,791 | 2020-04-08 | None stated | Not in README | Douban Books scraper |
| fugary/calibre-douban | 1,385 | 2025-11-08 | Apache-2.0 | Not in README | Calibre metadata plugin |
| iphysresearch/TOP250movie_douban | 1,032 | 2019-04-12 | BSD-2-Clause | Each spider logs in first | Top 250 comments and sentiment model |
| baabaaox/ScrapyDouban | 789 | 2022-01-14 | None stated | Not in README | Film and book Scrapy spiders |
| douban/douban-client | 741 | 2014-06-22 (archived) | None stated | Needs API key | Old official API client |
| fugary/calibre-web-douban-api | 464 | 2024-06-09 | Apache-2.0 | Not in README | Calibre-Web metadata |
| JimSunJing/douban_crawler | 204 | 2022-05-09 | MIT | Not in README | Back up your own Douban records |
| kxy000/doubanapi | 181 | 2020-05-26 | None stated | No code | Copy of old API docs |
| wanglin2/douban_api | 179 | 2022-06-19 | MIT | Not in README | Self-hosted Douban API |
| kaito-kidd/douban-group-spider | 163 | 2021-01-08 | None stated | Not in README | Group post scraper |
| cxfksword/douban-api-rs | 148 | 2022-10-21 (archived) | MIT | Optional cookie | Film metadata for Jellyfin |
| acdzh/douban-book-api | 117 | 2023-01-30 | MIT | Not in README | Third-party book API |
| AaronZ345/douban-cli | 62 | 2026-10-22 | MIT | Login for account actions | CLI and MCP |
| jackjin1997/douban-mcp | 20 | 2026-11-17 | MIT | Cookie for detail pages | MCP server |
| moonlin1213/cove-douban-mcp | 15 | 2026-08-29 | Apache-2.0 | Uses your logged-in Chrome | Read-only MCP |
| yoyooyooo/douban-mcp | 9 | 2025-03-23 | None stated | Cookie in config | MCP server |
| openplayx/mcp-douban | 1 | 2026-11-17 | MIT | Film endpoints without login; general search needs login | HTTP API and MCP |
| BugenZhao/douban-mcp | 0 | 2026-10-25 | None stated | Password login, maybe SMS check | MCP over the app API |
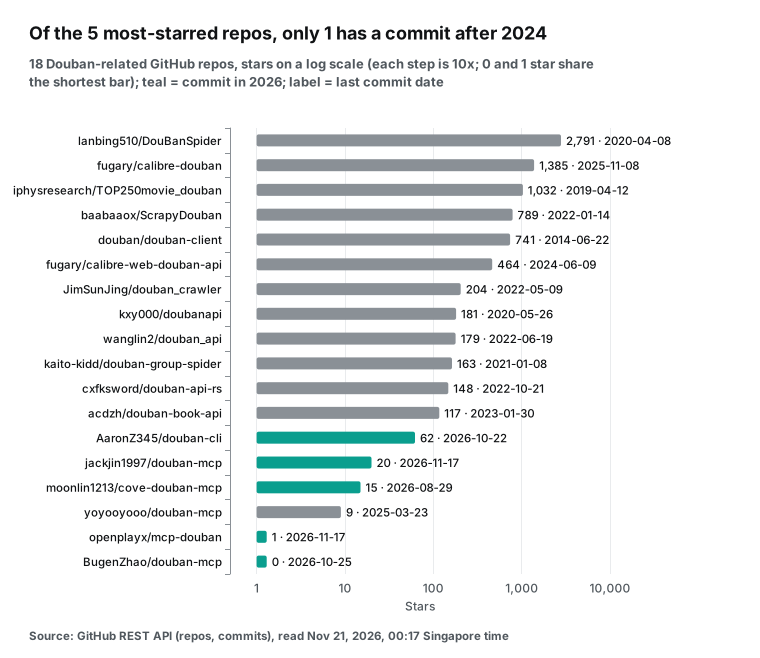
Stars and activity point in opposite directions. Of the 5 most-starred repositories, only calibre-douban has a commit after 2024.
The 11 repositories with a last commit before 2025 hold 6,809 stars. The 5 repositories with a 2026 commit hold only 98 stars. Most stars date from the years when the old API still worked. If you sort by stars, you mostly pick code that nobody maintains.
The projects that are still active in 2026 moved to MCP, and most of them need an account. The README of jackjin1997/douban-mcp is specific. Search and the Top 250 list work without login. Single film and book pages redirect to sec.douban.com, so the tool needs a DOUBAN_COOKIE for stable access. Its backup path through the app API was removed because the server now requires a request signature. The error was invalid_request_997.
BugenZhao/douban-mcp uses that app API. It signs requests with shared client constants from the app and logs in with your password. On account-protection error 9000, it triggers an SMS check.
moonlin1213/cove-douban-mcp takes another path. It does not export cookies, but it uses the Douban session in your local Chrome. openplayx/mcp-douban uses only the mobile film endpoints. Its README says these need no login, but general search does. When Douban refuses a request, it returns a dedicated refusal error code and lists rule changes, IP blocks or rate limits as causes.
Seven of the 18 repositories state no license. GitHub's documentation says that without a license, default copyright law applies and the author keeps all rights. Check how this applies to you. Two repositories are archived, and their authors no longer update them. Check the license column before you build an internal tool on any of them.
Two uses fit these projects well. Calibre users who want Douban metadata for their own e-book library can use the two fugary plugins, which exist for that job. The description of calibre-douban says that Douban no longer provides a book API. People who want to back up their own Douban ratings can use JimSunJing/douban_crawler or the export script from the Douban Escape Plan post. Both read only your own pages, which is personal data for personal use. That is a different case from bulk collection of other people's comments.
Open-source scripts run on your own machine and network, so Douban's anti-bot checks see your IP and your account. A 2021 study of animated-film comments (Wu et al., Entertainment Computing) is one example. Its Google Scholar excerpt says that Douban's IP limits made collection harder. In the 2020 V2EX thread, one developer warned that page parsing "is too exposed" and easily triggers anti-scraping checks.
Douban's robots.txt disallows 29 paths for all crawlers, including /search, /subject_search, /j/ and /people/*/collect. The Crawl-delay: 5 line is present but commented out. The robots.txt on movie.douban.com is identical byte for byte. RFC 9309 defines these rules as requests to crawlers, not as access control.
What does it take to build your own Douban scraper?
There is a fourth route: write the scraper yourself. The open-source READMEs describe the obstacles clearly, and they come in a fixed order. The first obstacle is request rate. TOP250movie_douban sets a download delay of 1.8 seconds per spider and runs only two or three spiders at once, "to avoid a ban." The second obstacle is login. In the same project, each spider logs in first. The 2026 README of jackjin1997/douban-mcp says detail pages without a cookie redirect to sec.douban.com.
The third obstacle is request signing for the app API. Calls without a valid signature fail, so working projects must ship the app's client constants. The fourth obstacle is page changes. The README of acdzh/douban-book-api warns that HTML parsing can hit anti-scraping limits or fail to parse. When the rules break, you wait for the author to update them.
Together, these four obstacles turn your own scraper into a maintenance task. You need an account, a set of proxies and parsing rules that break when pages change. You also need time to stop and repair the pipeline. The monthly example later in this guide costs $0.46 per month for short comments and group posts with a pay-per-call API. Your own scraper saves that money, but you guard all four obstacles yourself.
For a one-time research project with a small sample, a script is a reasonable choice. For a weekly job that feeds a report, the maintenance usually costs more than the API fees.
Which Douban API is best? What to compare in a pay-per-call service
Compare five numbers: rows per call, price per row, billing for failed and empty calls, field coverage, and whether you must supply an account. A price "per call" tells only half the story. At the same $0.001389 per call, 100 rows per call and 3 rows per call differ by 33 times per 1,000 rows.
Our catalog is public, and you can read it without a key: Douban capabilities in the EveryInfra catalog. The compact catalog we read on 2026-11-21 at 00:13 Singapore time lists 106 platforms and 626 capabilities, and 591 of them are marked as available. Douban has 4 capabilities, and the catalog marks all 4 as available.
| Capability | Price | Default and maximum in the catalog | Parameters | Fields listed |
|---|---|---|---|---|
douban/search title search | $0.001389 per call | 20 by default, up to 50 | keyword; type is all, movie, book or music | 14 |
douban/comments short comments | $0.001389 per call | 20 by default, up to 200 | Title page url | 14 |
douban/reviews long reviews | $0.024 per review | 15 by default, up to 50 | Title page url | 16 |
douban/group_topic group topic and replies | $0.001389 per call | 1 topic per call; replies 20 by default, up to 100 | Topic url, max_replies | 13 |
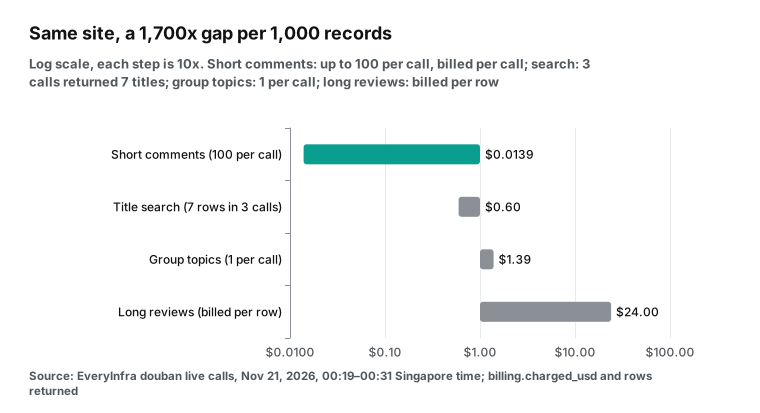
The four bars use the rows that our calls actually returned. At 00:26 Singapore time, douban/comments with limit=100 returned 100 rows and cost $0.001389, which is $0.0139 per 1,000. douban/reviews costs $0.024 per review. Our 00:26 call asked for 2 reviews and cost $0.048, and the response showed units 2 and rows_per_unit 1. The ratio is 24 ÷ 0.0139 ≈ 1,727.
The price gap follows the content. The long review endpoint takes a title page, for example the page for The Three-Body Problem. Each long review also has its own page, such as a film review posted on 2026-11-11. The douban/reviews capability returns a set of reviews for one title page, not one review by its own link.
The two reviews we got were both posted in April 2008. One had 4 stars and one had 5 stars, with 268 and 149 replies. Each row has a title, a star rating, a reply count and a link to the review page. The texts had 3,265 and 1,283 Chinese characters. The 100 short comments had a median of 45.5 characters and a maximum of 367. For text mining and sentiment analysis, short comments give the right volume and price. Use long reviews when you need complete essays.
Search costs more per row because it returns few rows. The catalog default is 20, but our three searches returned 3, 3 and 1 rows. A film-and-TV search for a 2026 spy-drama title returned 1 film and 2 TV series. A book search for The Three-Body Problem returned the three volumes of the trilogy. A search for The Wandering Earth with type all returned only the 2016 book, not the film.
Three calls cost $0.004167 for 7 titles, which is $0.60 per 1,000. Search mainly turns a title into a page URL for later calls, so its total cost is usually small.
For other pay-per-call services, check the same items. Count the rows that come back, not the documented maximum. Check whether long text fields have a separate price. Check billing for empty results and refusals. Check whether you must supply a Douban cookie and whether a remote MCP server exists. Call the same title URL once in each service and compare rows and charges. That test is more reliable than a price page.
One live test: what 17 calls returned
On November 21, 2026, from 00:19 to 00:31 Singapore time, we sent 17 requests in three rounds. Round 1 ran from 00:19 to 00:23 and covered search, short comments, a group topic and video search. Round 2 ran at 00:26 and tested long reviews and 100 short comments. Round 3 ran from 00:29 to 00:31 and tested film comments, the reply limit and an untyped search.
| Singapore time | Capability | Input | Result | Charged (USD) |
|---|---|---|---|---|
| 00:19:00 | douban/search | 2026 spy-drama title, movie | 3 titles (1 film, 2 series), 35.7 s | 0.001389 |
| 00:19:50 | douban/search | The Three-Body Problem, book | 3 titles | 0.001389 |
| 00:20:04 | douban/comments | TV series not yet aired | 0 rows, not billed | 0 |
| 00:20:26 | douban/group_topic | One topic in a box-office group | 1 topic, 20 replies | 0.001389 |
| 00:21:03 | douban/comments | The Three-Body Problem, default size | 20 rows | 0.001389 |
| 00:21:32 | youtube/search | Douban API | 10 videos | 0.000778 |
| 00:21:41 | douban/comments | A user profile URL on purpose | 0 rows, not billed | 0 |
| 00:22:00 to 00:23:16 | youtube/transcript | 3 videos | No captions, not billed | 0 |
| 00:26:14 | douban/reviews | The Three-Body Problem, limit=2 | 2 reviews | 0.048 |
| 00:26:43 | douban/comments | The Three-Body Problem, limit=100 | 100 rows | 0.001389 |
| 00:29:52 | douban/comments | The Shawshank Redemption, limit=200 | 0 rows, not billed | 0 |
| 00:30:08 | douban/group_topic | Same topic, max_replies=100 | 24 reply rows, 23 unique | 0.001389 |
| 00:30:24 | douban/search | The Wandering Earth, all | 1 title (the book) | 0.001389 |
| 00:30:46 | douban/search | type=tv | 422; only all, book, movie, music allowed | 0 |
| 00:30:59 | douban/comments | The Shawshank Redemption, default size | 0 rows, not billed | 0 |
| Total | 17 requests, 9 billed | 0.058501 |
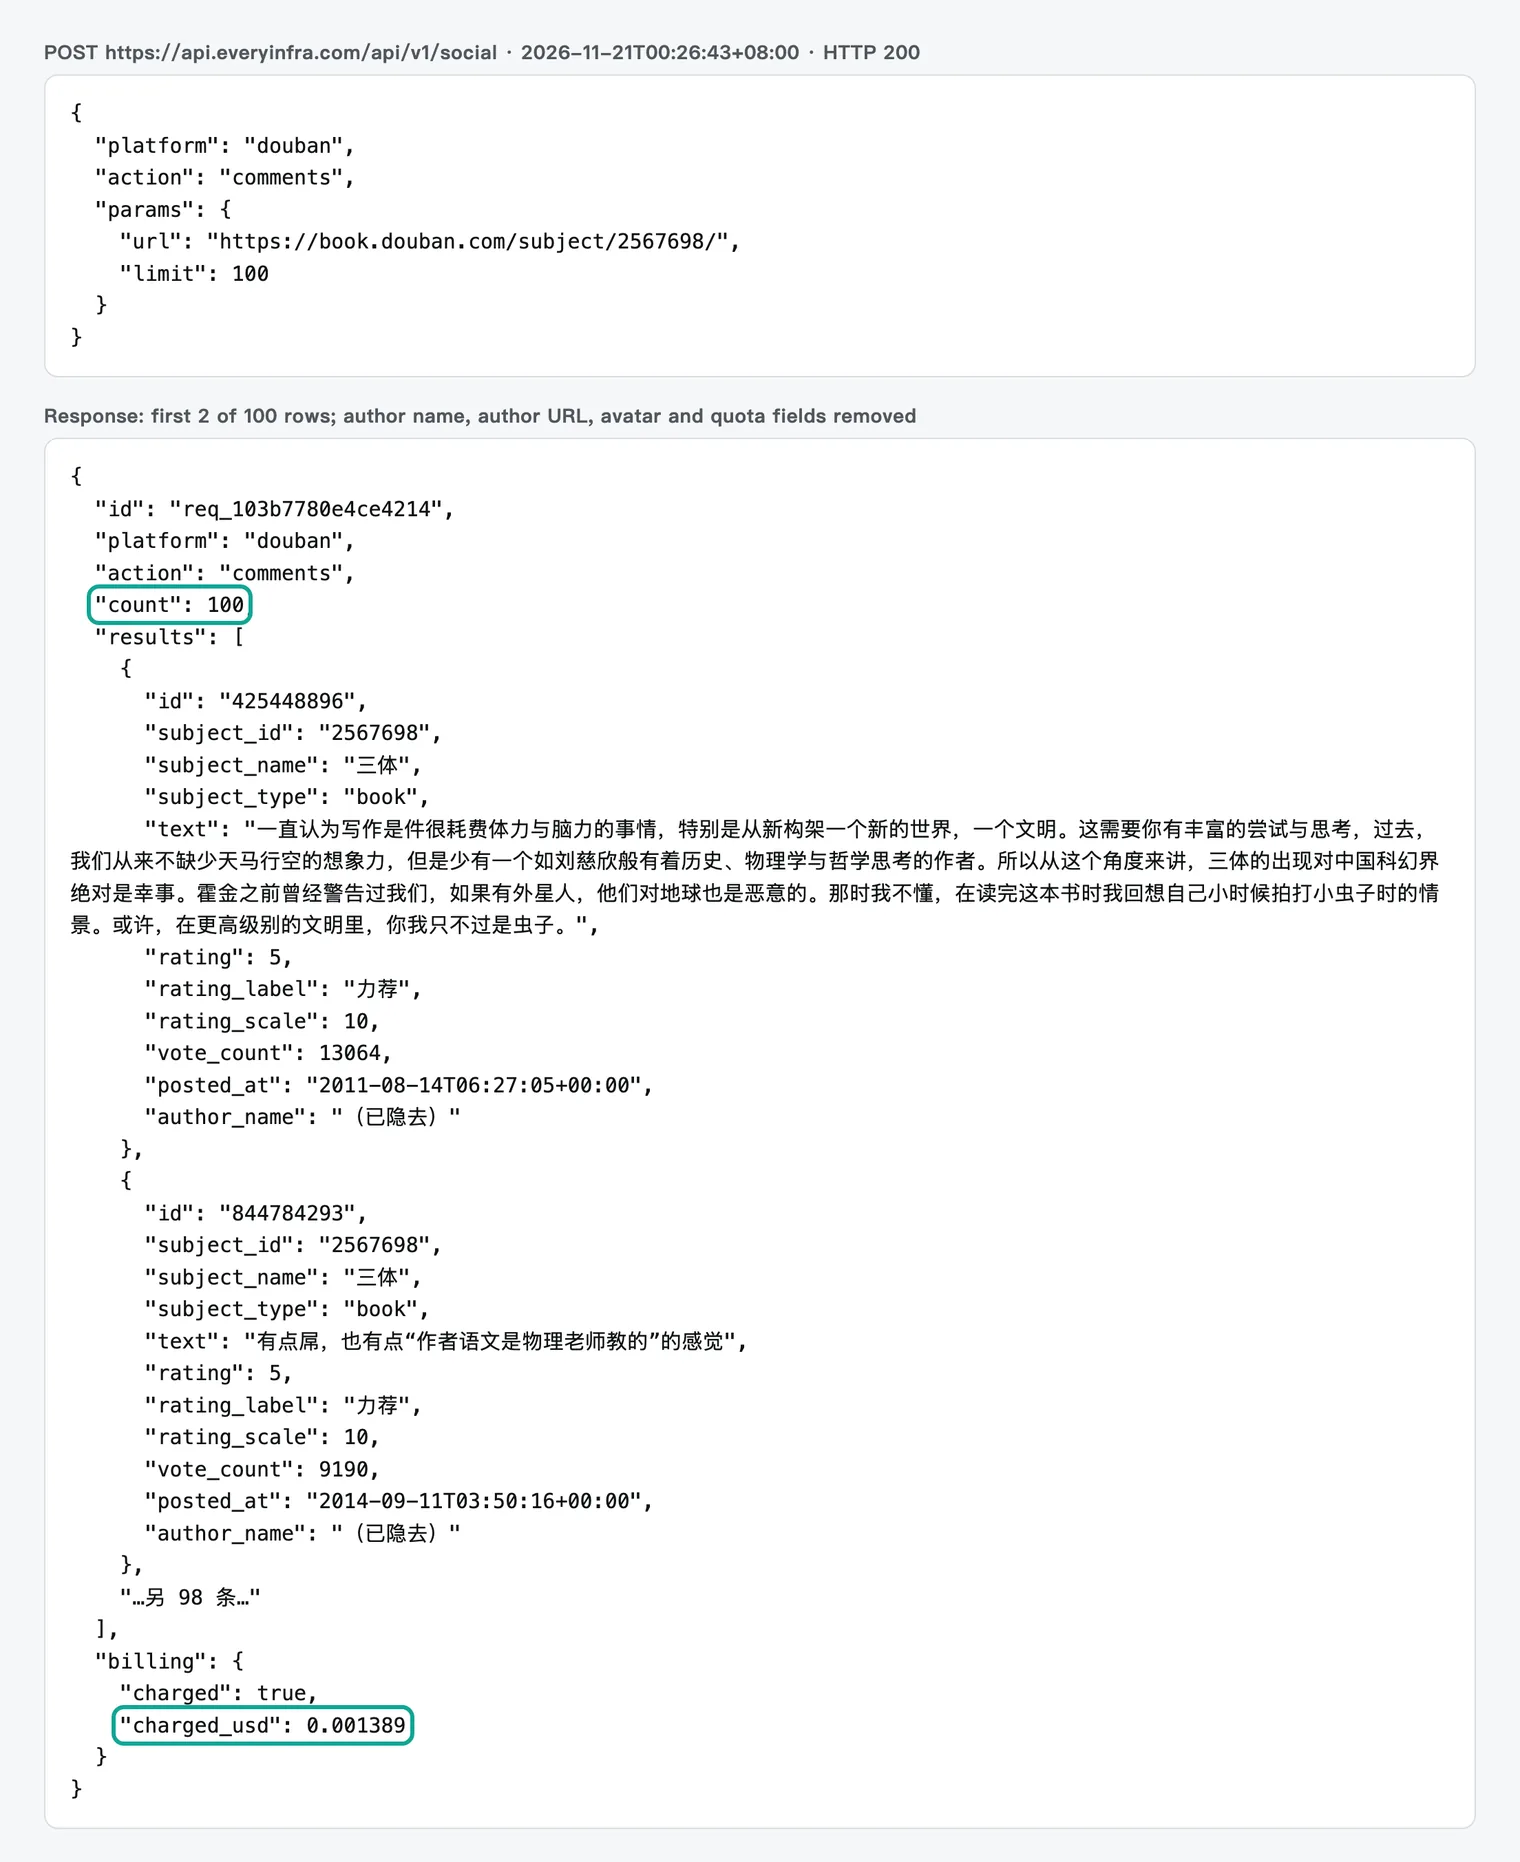
For book comments, the default call returned 20 rows, and the limit=100 call returned 100 rows. The first 20 IDs were identical and in the same order in both calls. The 100 rows had no duplicate IDs. Each row has the text, a star rating, a "helpful" count in vote_count, and a timestamp. The helpful counts ranged from 12 to 13,064, with a median of 87.
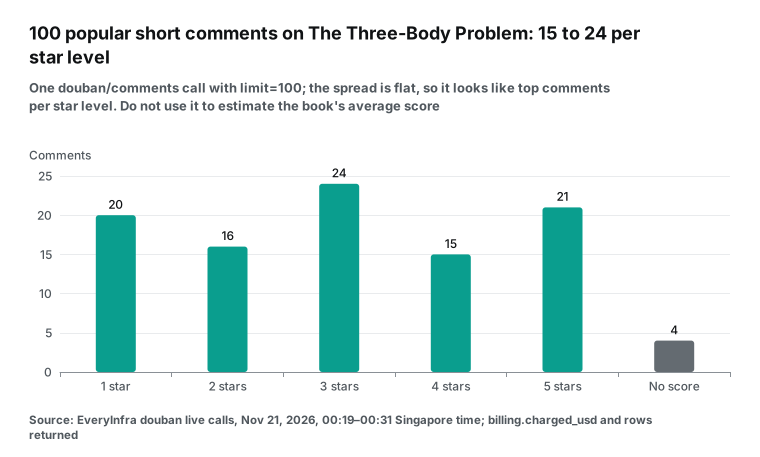
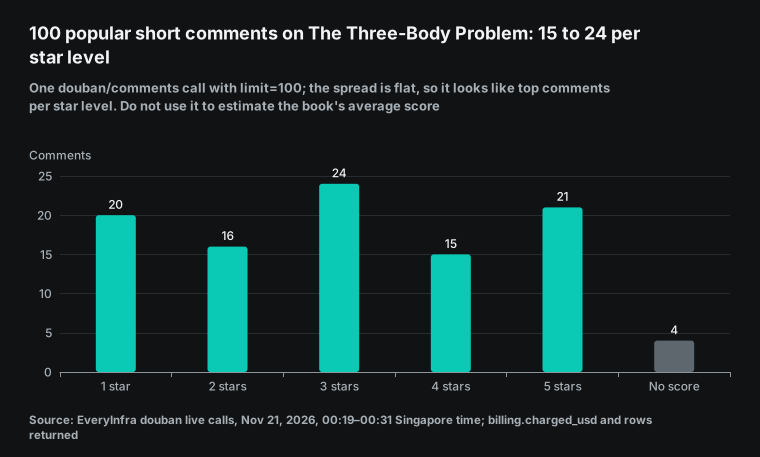
The star ratings in these 100 comments are almost flat. The counts are 20, 16, 24, 15 and 21 for 1 to 5 stars, and 4 comments have no score. A book's real rating spread is rarely this even. So the endpoint seems to return popular comments picked per star level. That is useful to learn why people gave one star or five stars. It is not useful to compute an average score.
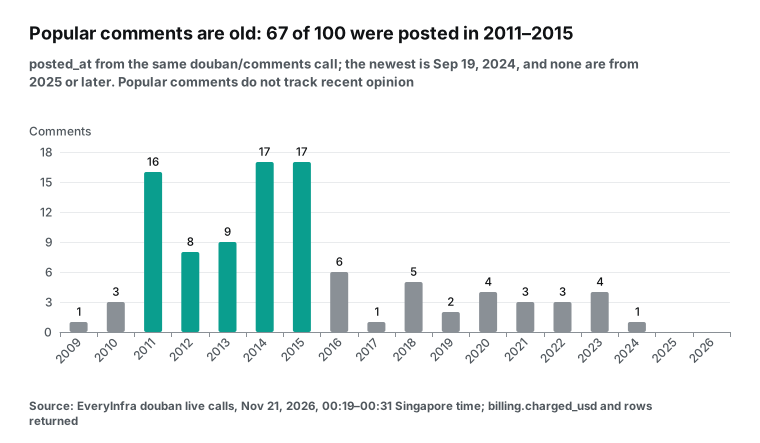
The timestamps confirm that these are popular comments. Of the 100 rows, 67 were posted between 2011 and 2015. The newest one is from 2024-09-19, and none are from 2025 or later. The catalog shows no sort option for douban/comments, so you cannot ask for the newest comments. This capability cannot track how opinion on a new film changes in its first week. For that job, look at group discussions instead.
What can you learn from 100 short comments?
We grouped the 100 comments by star level and took the median helpful count for each level. Comments with 2 or 4 stars got the highest median helpful counts. Among the 10 most helpful comments, 4 had 5 stars and 2 had 4 stars. Two had 3 stars, and 1 each had 1 or 2 stars. Nine of the 100 comments had more than 1,000 helpful votes.
| Star level | Comments | Median helpful votes | Median length (characters) |
|---|---|---|---|
| 1 star | 20 | 45.5 | 48.5 |
| 2 stars | 16 | 115.5 | 34 |
| 3 stars | 24 | 72.5 | 40 |
| 4 stars | 15 | 148 | 34 |
| 5 stars | 21 | 100 | 47 |
| No score | 4 | 46.5 | 84 |
Response time also matters for planning. The 12 successful Douban calls took from 8.5 to 35.7 seconds, with a median of about 15.5 seconds. The first search was the slowest. For a batch of several hundred titles, add "mode":"async" to the request body. You then get a job ID at once and poll the returned URL. The async_hint field in each response describes the same option.
Group topics show what people discuss now
Group topics are closer to current discussion. We used one topic posted on 2026-11-12 in a box-office discussion group. It asked whether an upcoming spy film would have a better plot than an earlier spy film by a famous director. At 00:20 we used the default of 20 replies. At 00:30 we set max_replies to 100 and got 24 rows, which matches the reply count of 24 on the topic page.
The replies were posted on 2026-11-14 (16 rows), 2026-11-15 (6 rows) and 2026-11-17 (2 rows). Their helpful counts ranged from 0 to 33, with a median of 7. The top reply, with 33 votes, quoted the earlier film's Douban score of 7.3 and its box office to defend it. The second reply, with 25 votes, doubted that the new film's director could handle a plot-driven drama. Group replies carry timestamps, so you can see what people compare a film with before release. Popular short comments are picked by helpful votes and do not show that order.
Two of the 24 rows had the same ID. The same reply from the same user at the same time appeared twice. After removing it, 23 unique replies remain. Remove duplicates by id before you store the data.
Three empty results were for film or TV pages. One was a TV series that has not aired yet, so zero comments is normal. The Shawshank Redemption returned zero rows twice, once with limit=200 and once with the default size.
Book comments worked during the same period. All three film and TV comment calls returned empty results and cost nothing. For film opinion, use group topics first. An empty result costs nothing, so a retry at another time costs nothing extra.
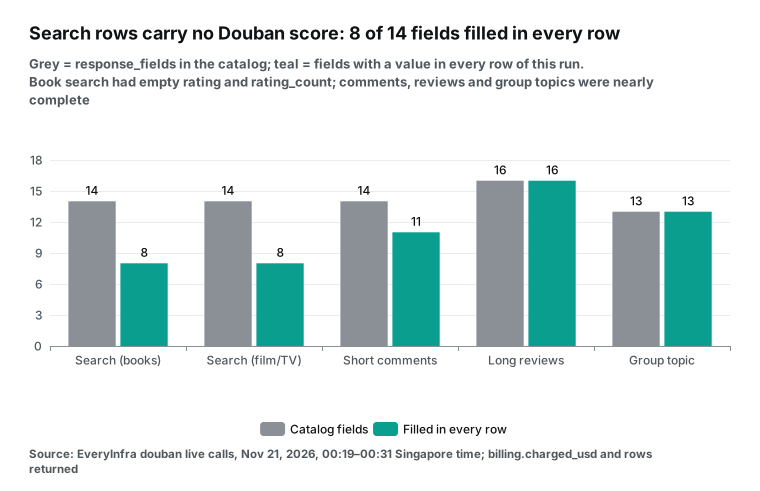
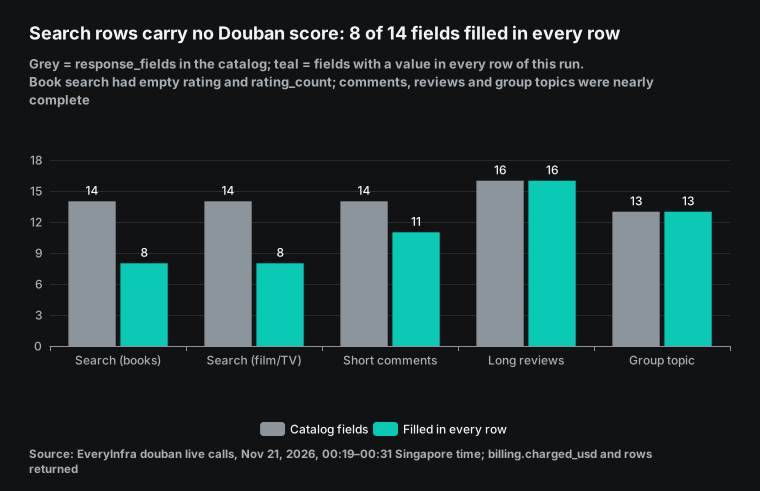
Field coverage was complete for long reviews and group topics: every catalog field had a value in every row. Short comments filled 11 of 14 fields in every row and 3 fields in some rows. For example, the 4 comments without a score had no rating.
Search did not fill all score fields. Book search returned empty rating, rating_scale and rating_count fields. Film search returned rating_count as 0. All three film results are not released yet: one is a 2028 film, and the other two are TV series from 2026 and 2028. So a count of 0 matches that fact. The book search for The Three-Body Problem returned the three volumes with author, year (2008, 2008 and 2010) and cover link. If you need Douban scores to rank books, get them from another source.
Errors behaved as a customer would expect. The type=tv call returned 422 with the allowed values, and it cost nothing. If you send calls too fast, you get 429 with a retry_after value in seconds and no charge. Wait, then retry. A user profile URL sent to douban/comments returned 200 with an empty result and no charge. In total, 9 of 17 calls were billed for $0.058501, and $0.048 of that was the two long reviews. To match refunds against charges, see failure refund reconciliation.
Douban API recommendations by use case
| Your job | Recommended route | Why |
|---|---|---|
| Sell Douban data or show Douban scores in a commercial product | Read section 2 of the Legal Notice, then contact bd-team | Section 2, item 2 lists these uses; check if it applies to you |
| Add Douban metadata to your Calibre library | fugary/calibre-douban or calibre-web-douban-api | Built for this job, Apache-2.0, latest commit 2025-11-08 |
| Back up your own Douban ratings | An export script that reads only your own pages | Personal data; no API needed |
| Look up a few titles in Claude, Cursor or another AI tool | A local MCP tool, or a remote MCP server | Local tools work at low volume, but detail pages often need a cookie |
| Pull popular comments for dozens of titles each week | Pay-per-call douban/comments | 100 rows for $0.001389; no proxies or logins to maintain |
| Follow a discussion in a Douban group | Pay-per-call douban/group_topic | Up to 100 replies per call; our test got 24 rows, 23 unique |
| Read complete book or film reviews | douban/reviews, billed per review | $0.024 each with full text; plan the budget for large volumes |
| Rank titles by Douban score or rating count | Our catalog has no title-detail capability; ask Douban about permission | Book search returned no scores in this run |
| Track the newest comments on a new film every day | Not available from our API in this run | No sort option; the endpoint returns popular comments |
Before you build a product, answer one question. Who will see the data after it leaves your computer? Item 2 lists uses that need written permission. A public data service is in that list. Scores and comments in a commercial product are also in it. The clause does not list internal research, topic planning or opinion checks item by item. Check the source text yourself.
A monthly budget: 50 titles and 20 group topics
Here is a concrete example. Assume that a publisher's social media team follows 50 book titles each week, with one call of 100 comments per title. The team also follows 20 group topics each week, with up to 100 replies per topic. At the start of each month, it searches the 50 titles to get their URLs. Each month, it reads 5 long reviews per title. For a 4-week month, the cost is as follows.
| Item | Calls or rows | Unit price (USD) | Subtotal (USD) |
|---|---|---|---|
douban/comments, 50 calls per week | 200 calls | 0.001389 per call | 0.2778 |
douban/group_topic, 20 calls per week | 80 calls | 0.001389 per call | 0.1111 |
douban/search, 50 calls per month | 50 calls | 0.001389 per call | 0.0695 |
douban/reviews, 5 per title | 250 reviews | 0.024 per review | 6.0000 |
| Total | 6.4584 |
The month costs $6.46, and long reviews are $6.00 of that, about 93%. Without long reviews, the same comment and group tracking costs $0.46 per month. So the main budget decision is whether you need full review text. With open-source scripts, the API cost is $0. However, 200 detail-page requests per week mostly need a cookie, based on the jackjin1997/douban-mcp README, and the account and IP risk stays with you. With Douban's permission, the price and terms are negotiated.
The same key also works for Zhihu data, Bilibili data and Douyin data. The billing model is the same. All Douban capabilities and a live playground are on the Douban API page.
When another route is a better fit
Our API has clear gaps. In these cases, another route works better.
You need Douban scores and rating counts. Our douban/search returned empty score fields in this run, and our Douban catalog has no separate title-detail capability. Item 2 of the Legal Notice lists "showing Douban scores in a commercial product" as a use that needs written permission. For long-term, large-scale use of scores, you can ask Douban about permission directly.
You need the newest comments in time order. douban/comments takes only a title URL and returns popular comments, and the newest one in our sample was from 2024. For a daily opinion report on a new film, this data does not keep up.
You need data about individual users, such as someone's "want to watch" list. Our catalog has no such capability. Douban's robots.txt also disallows paths such as /people/*/collect and /people/*/wish. Personal data also falls under China's Personal Information Protection Law. To export only your own records, use one of the personal backup tools above.
You need film comments right now. All three film or TV comment calls in this run were empty and cost nothing. Use group topics for film discussion.
Your volume is tiny and only for you. If you look up a few dozen books a month, an open-source tool or manual copying is enough. You do not need a paid API.
Rules to read before you collect Douban data
Two layers of rules apply to Douban data: Douban's own documents and the laws for all network data in China. We do not give legal opinions. The table lists the source documents and dates so that you or your lawyer can read them.
| Document | Published or in force | What it says about Douban data |
|---|---|---|
| Douban Legal Notice | Read on 2026-11-21 | No commercial use without written permission, including scores, comments, statistics, opinion monitoring and AI training; contact bd-team |
| Douban Terms of Use | Revision published 2025-05-27 | Clause 9.6 forbids interference with the service and tools made for that purpose |
| Douban robots.txt | Read on 2026-11-21 | 29 disallowed paths for all crawlers, including search and personal collection pages |
| Anti-Unfair Competition Law, 2025 revision | In force from 2025-10-15 | Article 13, paragraph 3: no access to or use of data that others hold lawfully by fraud, coercion or by bypassing technical measures |
| Supreme People's Court Guiding Case No. 262 | Published 2025-08-28 | Copying a platform's data set without permission so that it substitutes for the platform can be unfair competition |
| Network Data Security Management Regulations | In force from 2025-01-01 | General rules for processing network data |
| Personal Information Protection Law | In force from 2021-11-01 | Rules for processing nicknames, avatars, profile pages and other personal information |
Guiding Case No. 262 gives these facts. From November 2018 to May 2019, the defendant's app had 50,392 short videos that matched the original platform. They included 19,079 user nicknames and avatars, and 15,924 of them matched the original platform. In 127 places, comments matched in text, order and punctuation. The plaintiff asked for 40 million yuan. The Haidian District court awarded 5 million yuan in December 2020, and the Beijing Intellectual Property Court upheld the decision in March 2023.
The court used the term "substantial substitution." Users could see the same content on the defendant's app without using the original platform. The case text also says that, after the revised law took effect on October 15, 2025, courts apply Article 13, paragraph 3 to such conduct. The Supreme People's Court's 2025 set of typical unfair-competition cases also includes data-scraping disputes. A securities regulator's Beijing office published a copy.
In the case, the defendant's app showed a large volume of the same content. So users did not need the original platform, and the court found substitution. Compare your use with the case facts yourself, or with a lawyer. We do not give a conclusion.
Our responses include author names, author profile links and avatars. Keep only the fields that your analysis needs, and do not store nicknames and avatars when you can avoid it. Douban also has a complaint procedure for rights holders. If a user complains, the other party will want to know where the data came from and what you stored.
What changed in the last 60 days
In the last two months, several new MCP projects for Douban appeared on GitHub. All of them let AI assistants look up books and films directly.
AaronZ345/douban-cli was created on 2026-10-09 and had its last commit on 2026-10-22. It turns title lookups, lists, ratings and comment management into a command-line tool with an MCP interface. Its write tools default to dryRun=true. For readers, this means you can already ask an AI to tidy up your own Douban records, but write actions use your account.
BugenZhao/douban-mcp was created on 2026-10-25 and uses the Douban app API. It needs a password login and may need an SMS check. For readers, this means the app API gives the fullest data. But your login and the signing constants live on your machine, and the account risk is yours.
openplayx/mcp-douban was created on 2026-11-14 and had its last commit on 2026-11-17. It serves Douban film data as an HTTP API and an MCP server, and its README lists error codes for refused requests. For readers, this means you can run your own service, but you must handle IP blocks and page changes yourself.
The latest commit of jackjin1997/douban-mcp is from 2026-11-17. Its README still says that detail pages need a cookie and that the app API path was removed because of signing. For readers, this means that without an account, only list pages are stable today. Detail pages and comments need either an account or an API that someone else maintains.
At the protocol level, the MCP specification of 2026-07-28 made the core protocol stateless. The MCP roadmap lists extensions such as Tasks. Several local projects above keep a cookie, a login session or a password on your computer for detail pages, write actions or general search. A remote MCP server needs only its URL and an API key in your client config, with no Douban account.
Researchers keep using Douban data. A July 2026 paper on a multimodal Douban film review dataset built a set with posters, metadata and ratings. A 2025 study on review readability and box office used Douban short comments. A study of film marketing on Chinese social platforms used Douban and Maoyan data for 957 films. Research projects usually need large samples over long periods. The age bias in popular comments, with 67 of 100 from 2011 to 2015, can change a research result. Check which kind of comments you get before you sample.
FAQ
Does Douban have an official API?
It had one, but it no longer serves the public. On 2026-11-21 at 00:16 SGT, an anonymous call to the film endpoint on api.douban.com returned 403 and invalid_apikey, with a request to contact bd-team
Which Douban API is best, and is there a ready-made one?
It depends on your use. For commercial products, ask Douban for written permission first. For a personal Calibre library, use an open-source plugin. For weekly comment and group tracking without your own account, a pay-per-call API is the fastest start. In our test, 100 short comments cost $0.001389 and empty results cost $0.
Can I still get a Douban API key?
Not through a public channel. The old developer site does not respond, and we found no self-service sign-up on 2026-11-21. The shared keys that circulated online all stopped working in August 2020, as a V2EX thread records. For formal permission, follow the Legal Notice and email bd-team
Is there a Douban movie API I can use for film data?
Our douban/search finds film titles and returns their page URLs. In this run, short comments for film titles came back empty and were not billed, while book comments worked. Group topics are a working source for film discussion today.
Is there a Douban book API for Calibre?
Yes. For a personal e-book library, the Calibre plugins by fugary exist for this job. calibre-douban has 1,385 stars and an Apache-2.0 license, and its description says that Douban no longer provides a book API.
What is a Douban API proxy, and does it still work?
A Douban API proxy is a self-hosted service that scrapes Douban pages and returns data in the old API format. Tools such as Calibre and Jellyfin use it. wanglin2/douban_api describes itself as a replacement after the official API closed. cxfksword/douban-api-rs was built for Jellyfin and is archived after its 2022-10-21 commit. Whether a proxy works depends on whether its author keeps up with page changes and whether your server IP is blocked.
Can I match Douban titles to IMDb with an API?
Our Douban catalog has no IMDb lookup, and we did not test one. Search results return the Douban title, year and page URL. You can then match those fields to another database.
Getting started
Step 1: create an account in the EveryInfra console and get an API key. New accounts get a free trial balance. Step 2: read the catalog to confirm the parameters. The catalog needs no key.
curl -s "https://api.everyinfra.com/api/v1/social/catalog?platform=douban"Step 3: search for a title to get its URL, and then get its short comments. These are the request bodies we used in the test. Keep the key in an environment variable.
curl -s -X POST https://api.everyinfra.com/api/v1/social \
  -H "Authorization: Bearer $EVERYINFRA_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"platform":"douban","action":"search","params":{"keyword":"三体","type":"book"}}'

curl -s -X POST https://api.everyinfra.com/api/v1/social \
  -H "Authorization: Bearer $EVERYINFRA_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"platform":"douban","action":"comments","params":{"url":"https://book.douban.com/subject/2567698/","limit":100}}'
Each row from douban/comments has the fields in the catalog response_fields. id is the comment ID. subject_id, subject_name and subject_type identify the title and its type: book, movie or music. text is the comment. rating is the star level, rating_scale is the maximum scale, and rating_label is the text label for the level. vote_count is the number of "helpful" votes, and posted_at is the time with its time zone.
author_name, author_url and author_avatar_url describe the author, and platform is always douban.
douban/reviews adds url, title and reply_count. douban/group_topic adds group_id, group_name, group_url and a nested replies list. In each response, billing.charged_usd is the actual charge. For an empty result, it is 0, and billing.reason is empty_result_refunded. Remove duplicate group replies by id before you store them.
import json
data = json.load(open("group_topic.json"))
topic = data["results"][0]
seen, replies = set(), []
for r in topic["replies"]:
    if r["id"] not in seen:
        seen.add(r["id"])
        replies.append({k: r.get(k) for k in ("id", "text", "vote_count", "posted_at")})
print(topic["reply_count"], len(topic["replies"]), len(replies))
Step 4: connect an AI tool. The remote MCP address is https://api.everyinfra.com/mcp. See the MCP server page and the remote MCP setup guide. Here is a generic client configuration example.
{
  "mcpServers": {
    "everyinfra": {
      "url": "https://api.everyinfra.com/mcp",
      "headers": { "Authorization": "Bearer ${EVERYINFRA_API_KEY}" }
    }
  }
}
Our tools/list call to this address on 2026-11-21 at 00:26 Singapore time returned 12 tools. For Douban, use everyinfra_call_api with the same body as above. For prices, see the pricing page. For a similar comparison on another platform, read Xiaohongshu API: official or third party. For a full Python workflow, see the Douyin API Python tutorial and change the capability names to the Douban ones.
References
- Douban robots.txt, Douban, read 2026-11-21, <https://www.douban.com/robots.txt>
- Douban Movie robots.txt, Douban, read 2026-11-21, <https://movie.douban.com/robots.txt>
- Legal Notice, Douban, read 2026-11-21, <https://www.douban.com/about/legal>
- Terms of Use (revision of May 27, 2025), Douban, <https://www.douban.com/about/agreement>
- Complaint procedure for rights holders, Douban, <https://help.douban.com/complaint/>
- api.douban.com film Top 250 endpoint response, Douban, requested 2026-11-21, <https://api.douban.com/v2/movie/top250>
- api.douban.com book endpoint response, Douban, requested 2026-11-21, <https://api.douban.com/v2/book/1220562>
- Douban developer site, Douban, no response on 2026-11-21, <https://developers.douban.com/>
- Archived Douban developer home page, Internet Archive, 2018-06-26, <https://web.archive.org/web/20180626151022/https://developers.douban.com/>
- CDX snapshot index for developers.douban.com, Internet Archive, queried 2026-11-21, <https://web.archive.org/cdx/search/cdx?url=developers.douban.com&output=json&fl=timestamp,statuscode&collapse=timestamp:6>
- douban/douban-client, GitHub, <https://github.com/douban/douban-client>
- lanbing510/DouBanSpider, GitHub, <https://github.com/lanbing510/DouBanSpider>
- fugary/calibre-douban, GitHub, <https://github.com/fugary/calibre-douban>
- iphysresearch/TOP250movie_douban, GitHub, <https://github.com/iphysresearch/TOP250movie_douban>
- baabaaox/ScrapyDouban, GitHub, <https://github.com/baabaaox/ScrapyDouban>
- fugary/calibre-web-douban-api, GitHub, <https://github.com/fugary/calibre-web-douban-api>
- JimSunJing/douban_crawler, GitHub, <https://github.com/JimSunJing/douban_crawler>
- kxy000/doubanapi, GitHub, <https://github.com/kxy000/doubanapi>
- wanglin2/douban_api, GitHub, <https://github.com/wanglin2/douban_api>
- kaito-kidd/douban-group-spider, GitHub, <https://github.com/kaito-kidd/douban-group-spider>
- cxfksword/douban-api-rs, GitHub, <https://github.com/cxfksword/douban-api-rs>
- acdzh/douban-book-api, GitHub, <https://github.com/acdzh/douban-book-api>
- AaronZ345/douban-cli, GitHub, <https://github.com/AaronZ345/douban-cli>
- jackjin1997/douban-mcp, GitHub, <https://github.com/jackjin1997/douban-mcp>
- moonlin1213/cove-douban-mcp, GitHub, <https://github.com/moonlin1213/cove-douban-mcp>
- yoyooyooo/douban-mcp, GitHub, <https://github.com/yoyooyooo/douban-mcp>
- openplayx/mcp-douban, GitHub, <https://github.com/openplayx/mcp-douban>
- BugenZhao/douban-mcp, GitHub, <https://github.com/BugenZhao/douban-mcp>
- REST API endpoints for search, GitHub Docs, <https://docs.github.com/en/rest/search/search>
- RFC 9309: Robots Exclusion Protocol, IETF, 2022-09, <https://datatracker.ietf.org/doc/html/rfc9309>
- Thread: has the Douban API been shut off completely? (in Chinese), V2EX, 2020-08-18, <https://v2ex.com/t/699393>
- Thread: are all Douban book APIs unusable as of October 2019? (in Chinese), V2EX, 2019-10, <https://hk.v2ex.com/t/609234>
- Douban Escape Plan (in Chinese), ulyc blog, 2022-02-11, <https://ulyc.github.io/2022/02/11/Douban-Escape-Plan/>
- Guiding Case No. 262, unfair competition dispute over data copying (in Chinese), Supreme People's Court, 2025-08-28, <https://www.court.gov.cn/fabu/xiangqing/474451.html>
- Anti-Unfair Competition Law, 2025 revision (in Chinese), copy by the China National Intellectual Property Administration, <https://www.cnipa.gov.cn/art/2026/5/20/art_104_206437.html>
- Network Data Security Management Regulations (in Chinese), Ministry of Ecology and Environment copy, 2024-09-24, <https://www.mee.gov.cn/zcwj/gwywj/202410/t20241003_1087417.shtml>
- Personal Information Protection Law (in Chinese), copy by the National Bureau of Statistics, <https://www.stats.gov.cn/gk/tjfg/xgfxfg/202503/t20250310_1958923.html>
- Supreme People's Court 2025 typical unfair-competition cases (in Chinese), copy by the CSRC Beijing office, <https://www.csrc.gov.cn/beijing/c105536/c7657880/content.shtml>
- Model Context Protocol Specification 2026-07-28, MCP, <https://modelcontextprotocol.io/specification/2026-07-28>
- MCP Roadmap, MCP, <https://modelcontextprotocol.io/development/roadmap>
- Fang et al., Linguistic factors in digital entertainment success, Entertainment Computing, 2025, <https://doi.org/10.1016/j.entcom.2024.100911>
- Hua et al., Rating-aware argument generation for movie reviews, Multimedia Systems, 2026-07-16, <https://doi.org/10.1007/s00530-026-02499-0>
- Wu et al., Typical opinions mining based on Douban film comments in animated movies, Entertainment Computing, 2021, <https://doi.org/10.1016/j.entcom.2020.100391>
- Chou and Lin, Sequential film marketing in China, SSRN, 2025, <https://doi.org/10.2139/ssrn.5126807>
- EveryInfra Douban capability catalog, EveryInfra, read 2026-11-21, <https://api.everyinfra.com/api/v1/social/catalog?platform=douban>
- EveryInfra remote MCP server, EveryInfra, read 2026-11-21, <https://api.everyinfra.com/mcp>
- Python tutorial for the Douban API (video, in Chinese), YouTube, 2022-08-11, <https://www.youtube.com/watch?v=nrk09RQMfWE>
- REST API introduction with Douban API calls (video, in Chinese), YouTube, 2019-06-19, <https://www.youtube.com/watch?v=6udBuOr8LXA>
- Server-side requests to the Douban API (video, in Chinese), YouTube, 2021-10-08, <https://www.youtube.com/watch?v=lJHhSeipDgU>
- Douban group topic on an upcoming spy film (in Chinese), Douban Groups, 2026-11-12, <https://www.douban.com/group/topic/505471405/>
- The Three-Body Problem, book page, Douban Books, <https://book.douban.com/subject/2567698/>
- The Shawshank Redemption, film page, Douban Movie, <https://movie.douban.com/subject/1292052/>
- TV series page used in the empty-result test, Douban Movie, <https://movie.douban.com/subject/36218470/>
- Example of a long film review page (in Chinese), Douban Movie, 2026-11-11, <https://m.douban.com/movie/review/17895673/>
- Licensing a repository, GitHub Docs, <https://docs.github.com/en/repositories/managing-your-repositorys-settings-and-features/customizing-your-repository/licensing-a-repository>
Reference BL-205